RT by @_akhaliq: DeepSeek V4 Flash 0731 can now be run locally! 🐳 Run DeepSeek V4 Flash lossless 4-bit on 168GB RAM and 3-bit on 110GB RAM. V4 Flash 0731 outperforms V4 Pro. Run via Unsloth or llama.cpp. Smaller quants coming today. Guide: https://unsloth.ai/docs/models/deepseek-v4 GGUF: https://huggingface.co/unsloth/DeepSeek-V4-Flash-0731-GGUF
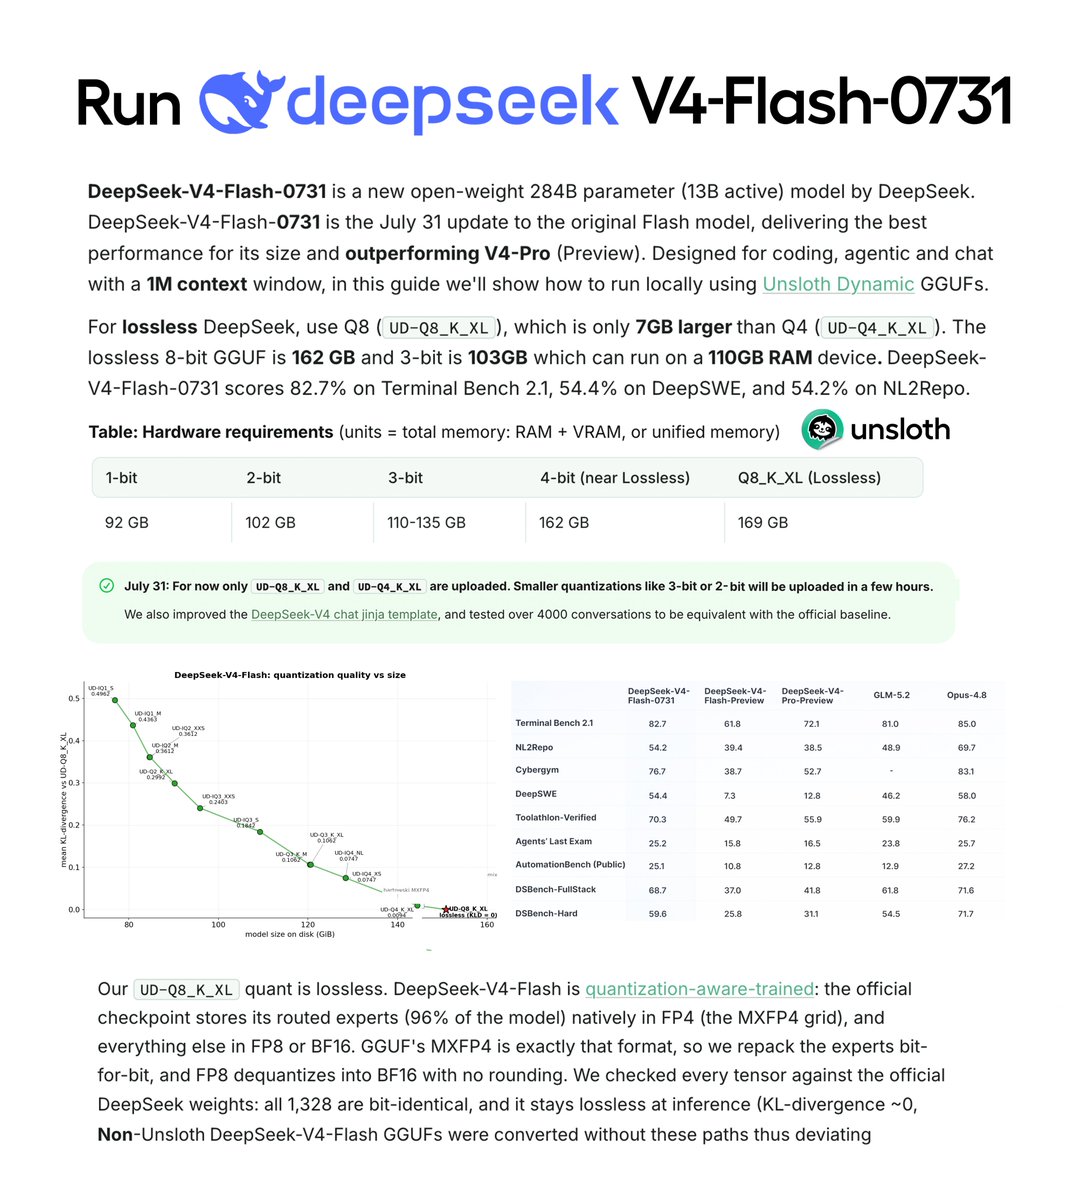
TL;DR - DeepSeek V4 Flash 0731 is now available for local execution through Unsloth or llama.cpp, alongside a public-beta API. Quantized builds reduce memory requirements while reportedly outperforming the V4 Pro preview.
- Lossless 4-bit quantization requires 168GB RAM; 3-bit requires 110GB.
- GGUF weights and an Unsloth deployment guide are available.
- The API supports the Responses API format and Codex integrations.
- DeepSeek reports significantly improved agent benchmark performance, though no specific results are provided.