RT by @_akhaliq: The models are improving the models. Locus, our automated AI research system, is…
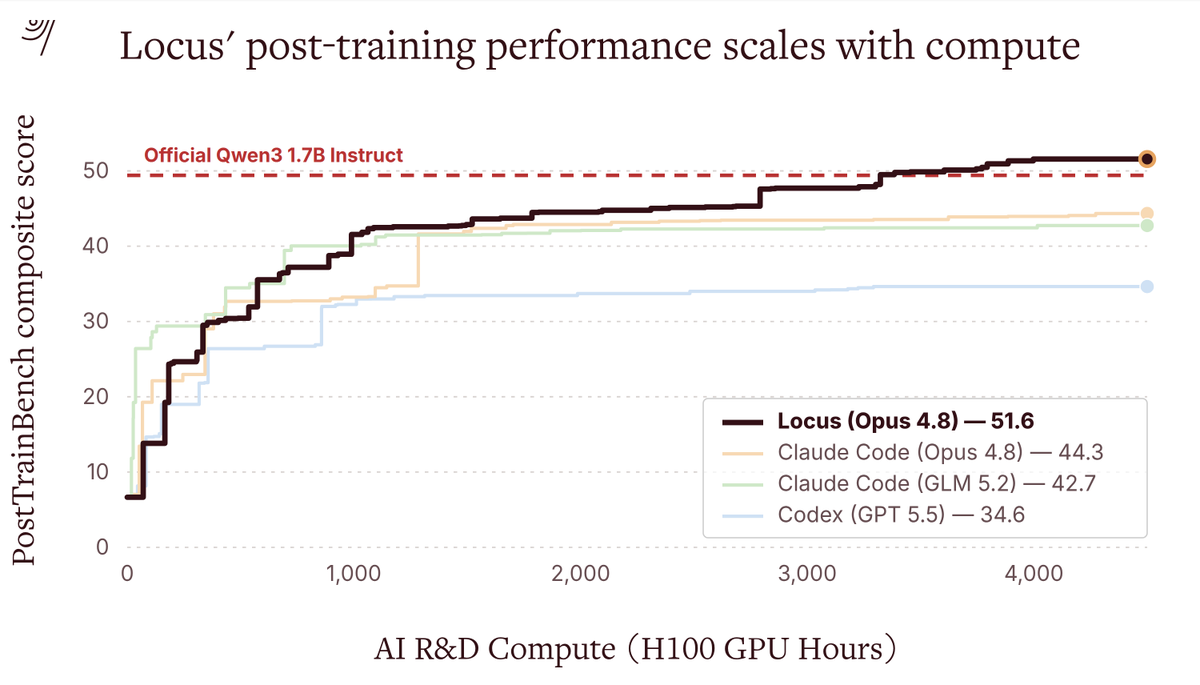
TL;DR - A company announcement (retweeted by @_akhaliq) claims Locus, an automated AI research agent, is SOTA on PostTrainBench and can post-train Qwen3 base models that beat the official human-post-trained Qwen3, with its outputs already serving millions in production. It's a concrete claim of recursive self-improvement — AI systems doing the ML research work that produces better models.
- PostTrainBench measures an agent's ability to post-train models across domains under a 10 H100-hour budget; the team introduces PostTrainBench+ with a much larger compute budget to better separate method quality.
- At thousands of H100 hours, Locus reportedly scales best, and its Qwen3 1.7B-Base models collectively surpass the official human-post-trained Qwen3 1.7B.
- Generalization test: run on all live prize-money Kaggle competitions with public leaderboards, Locus reached 4th-highest average rank among participants after 16 days.
- Caveat: this is a promotional thread summary — no ablations, baselines-by-name, or peer review are provided in the content, and "collectively surpass" is not defined per-task.