腾讯混元Hy ASR 3.0 preview:让语音识别理解上下文
TL;DR - Tencent Hunyuan released Hy ASR 3.0 preview, a speech-recognition model built on its Hy3 LLM that fuses acoustic transcription with semantic understanding, now live via Tencent Cloud API and in the Yuanbao app. It matters because it pushes ASR from literal transcription toward context-aware, intent-aligned output with strong dialect coverage.
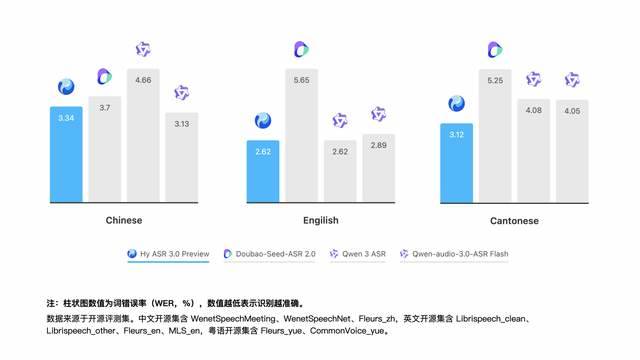
- Reports ~3% WER on open benchmarks: 3.34% Mandarin, 2.62% English, 3.12% Cantonese, plus leading results on self-built sets covering dialects, context understanding, and noisy/whispered audio.
- Architecture uses an MoE design with the Hy3 base model, paired with a self-developed unsupervised speech encoder trained on tens of millions of hours of audio, then jointly trained with the LLM.
- Post-training combines an SFT recipe spanning context, proper nouns, acoustic environments, 10 major dialect regions and 20+ sub-regions, followed by multi-stage RL targeting general accuracy, any-context handling, and long-tail scenarios.
- User-facing gains: homophone correction via context, hot-word injection for brand/industry terms, and stability in high-noise or whispered conditions; available through Tencent Cloud API, Yuanbao (free), with WorkBuddy integration in progress.