RT by @NVIDIAAI: 🚀 SGLang now officially supports @thinkymachines Inkling-Small running on 2×…
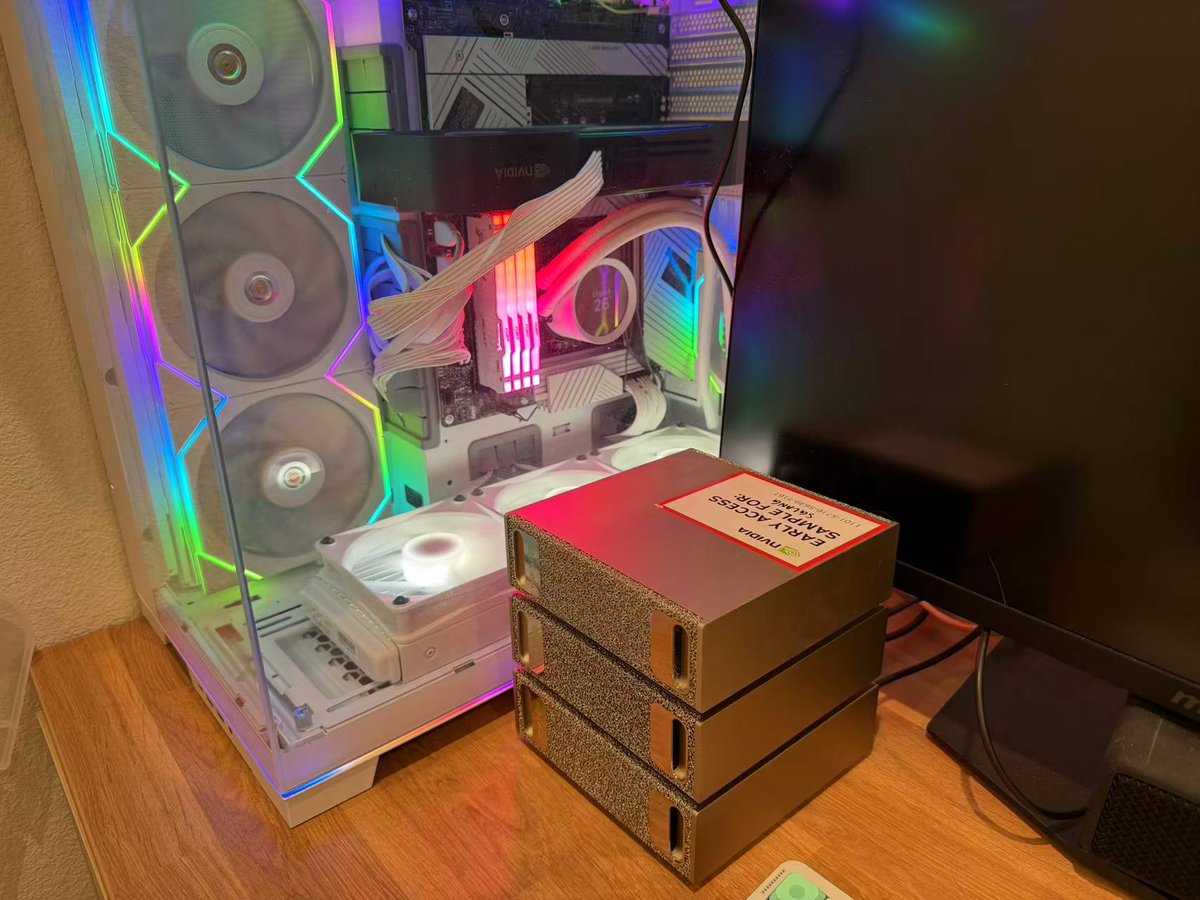
TL;DR - SGLang has added official support for Thinking Machines' Inkling-Small model running across two NVIDIA DGX Spark systems linked by ConnectX-7, enabling local agentic inference on compact desktop-class hardware. It matters because it pushes capable agent workloads off cloud GPUs onto small on-prem setups.
- Deployment spans 2× DGX Spark nodes interconnected via ConnectX-7, i.e. multi-node distributed serving rather than a single accelerator.
- Reported throughput is 24 tok/s at concurrency=1, measured without MTP (multi-token prediction); enabling MTP is implied as a future speedup path.
- Support was contributed by named community/individual developers, with DSpark support stated as coming soon and a cookbook provided for setup.
- Framed as enabling "strong agentic capabilities" locally, though no agent benchmarks or accuracy numbers are given in the post.