RT by @huggingface: we just released a new blog "Training a coding agent using the OpenCode harness…
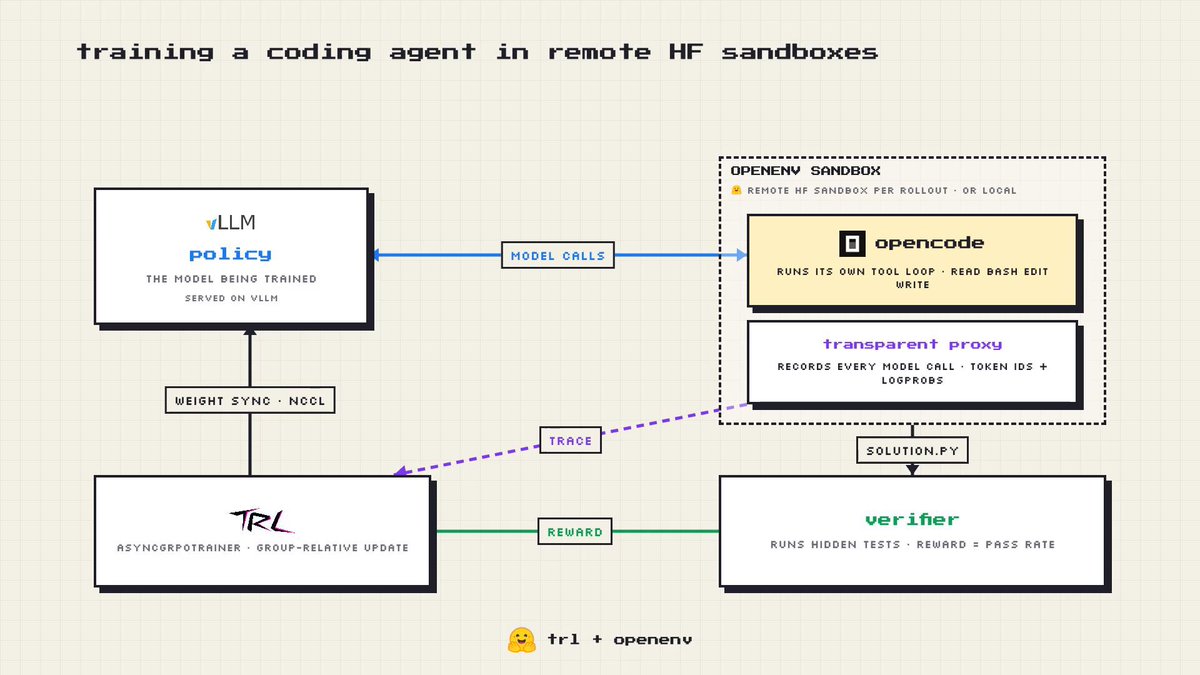
TL;DR - Hugging Face released a blog and runnable example for training OpenCode coding agents with reinforcement learning in scalable remote sandboxes. The setup captures actual agent trajectories and rewards solutions using hidden tests.
- OpenCode runs its tool loop inside isolated OpenEnv sandboxes.
- A proxy records generated token IDs and log probabilities for each turn.
- Hidden-test verification supplies the reward signal.
- TRL uses AsyncGRPO, with trained weights synchronized to vLLM over NCCL.