From RLVR to RLSVR Task Transformation Induces Self-Verifiable Rewards for Open-Ended LLM…
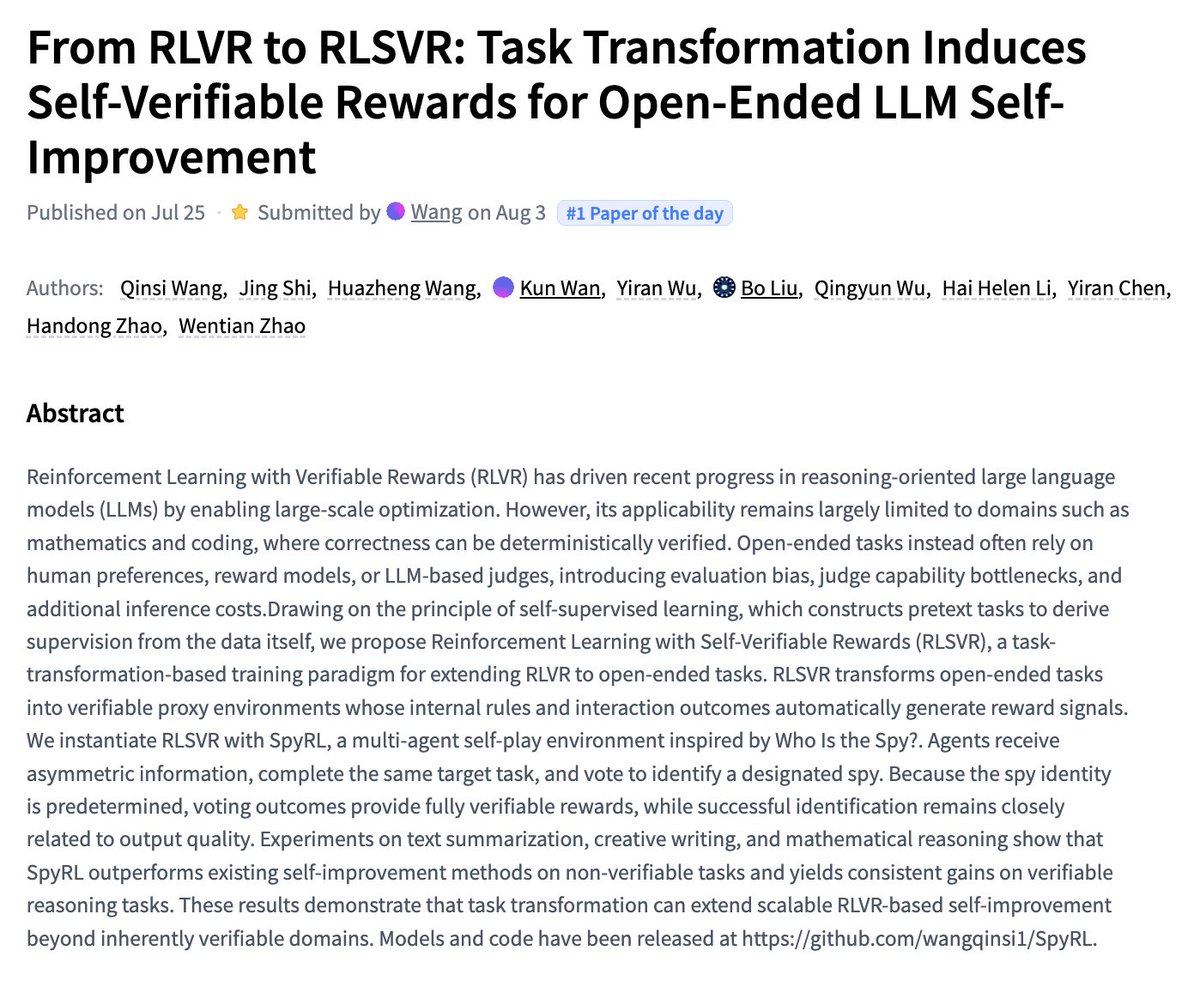
TL;DR - This paper proposes transforming open-ended LLM tasks to produce self-verifiable rewards for reinforcement learning. Only the title is provided, so its methods and results cannot be assessed.
- Extends reinforcement learning with verifiable rewards (RLVR) toward “RLSVR,” centered on self-verification.
- Targets self-improvement on tasks that lack straightforward externally verifiable answers.
- The post links to a paper, but provides no experimental details, benchmarks, or quantitative findings.