RT by @huggingface: Introducing NVIDIA Nemotron 3.5 Lightning⚡ An open 30B MoE model with 3B active…
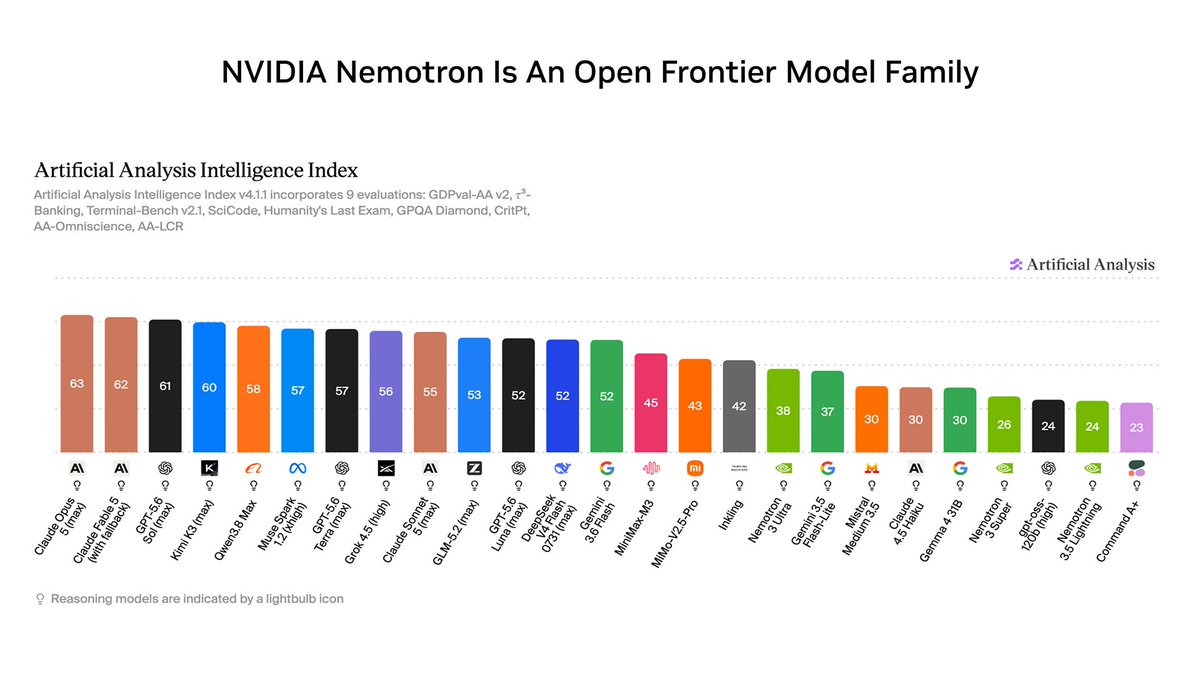
TL;DR - NVIDIA has released Nemotron 3.5 Lightning, an open-weight 30B mixture-of-experts model activating only 3B parameters per token, positioned for always-on agentic workloads. It matters because it targets high-throughput, latency-sensitive agent deployments rather than frontier benchmark scores.
- Sparse MoE design: 30B total parameters with ~3B active, keeping inference cost near that of a small dense model while retaining a larger knowledge capacity.
- Claimed up to 4x output speed versus similarly sized models — the headline pitch is tokens/sec throughput, not raw capability.
- Explicitly framed for "always-on agents" running high-volume, specialized tasks, where per-call latency and cost dominate.
- Content is a short announcement post; no benchmarks, training details, license terms, or evaluation methodology are given, so the 4x claim is unverified here.