至知研究院提出大模型可解释性新路线:拆权重,数据成本不到1%
TL;DR - Sparse Weight Decomposition (SWD) extracts causally testable LLM circuits directly from pretrained weights, avoiding separately trained surrogate networks. It matches baseline fidelity with under 1% of the data while scaling from GPT-2 to Qwen3.5-27B.
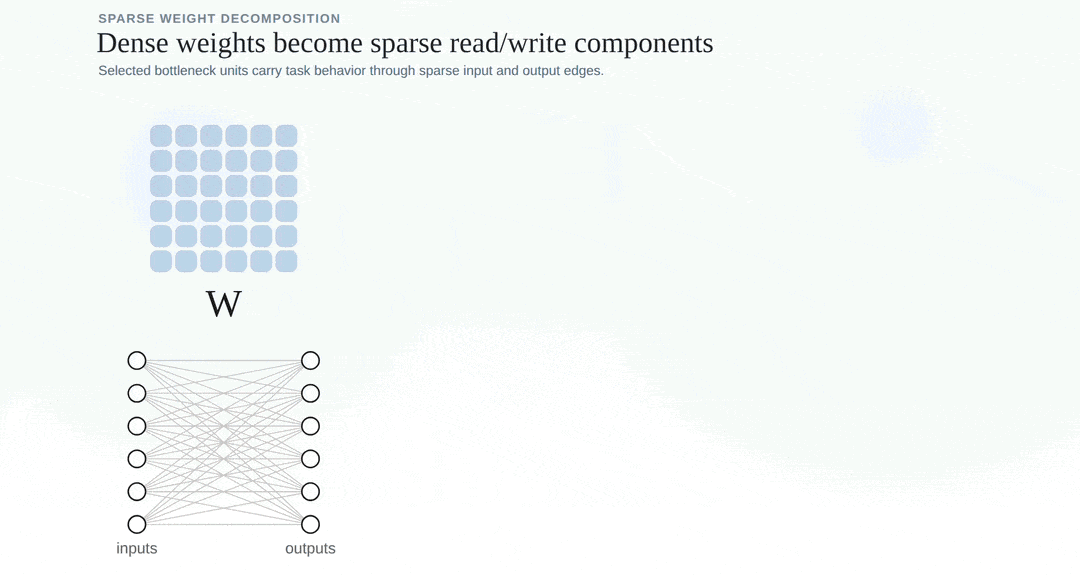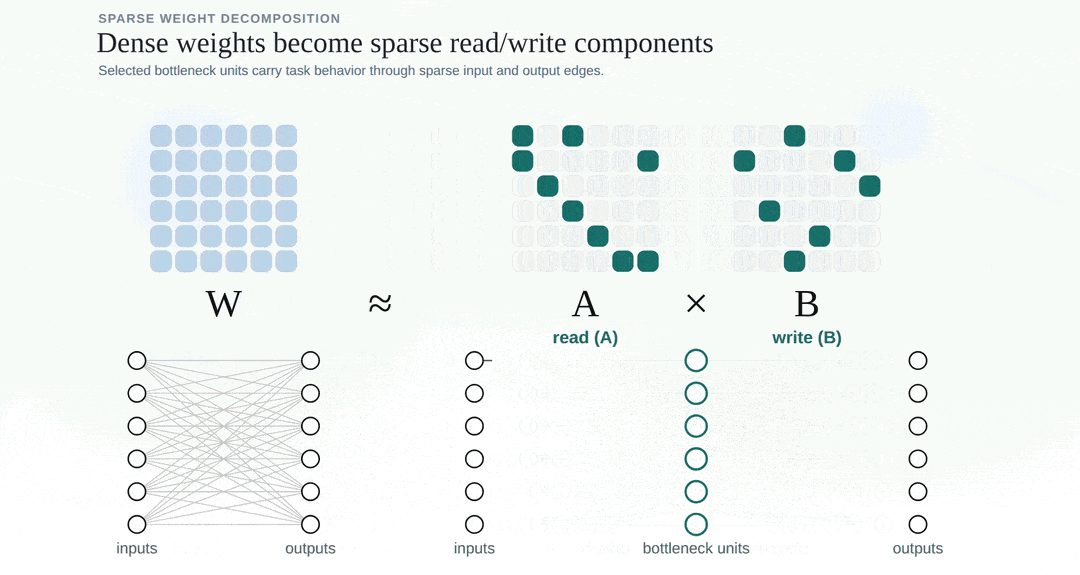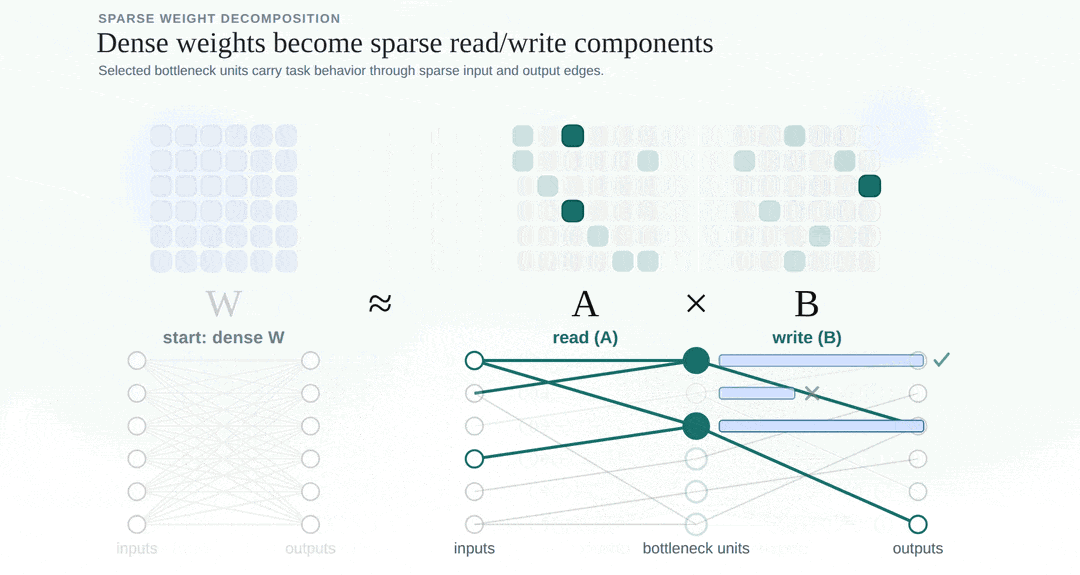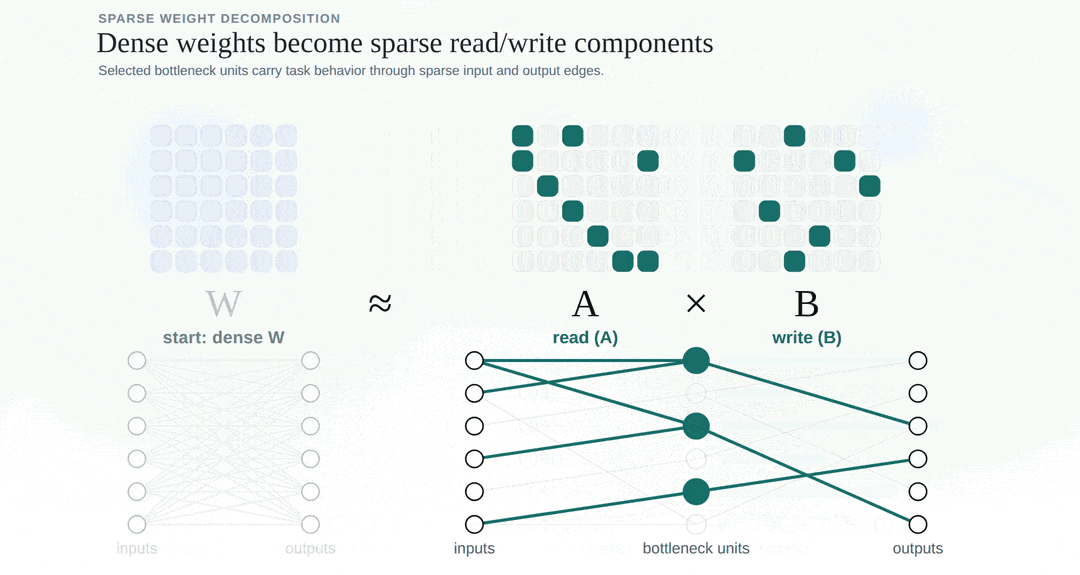
- SWD factors dense weights into two sparse matrices whose shared dimensions act as independently rankable and ablatable bottleneck units.
- It generally achieves comparable circuit sufficiency and necessity with fewer units and active connections than Transcoder and VPD-Recon-CI baselines.
- The method covers all 48 attention and MLP matrices in GPT-2 Small and includes a zero-data variant requiring no calibration text.
- Identified units exhibited task-relevant activation patterns and enabled targeted model editing with limited measured side effects.