对话 COBRA-Skills 一作卢平琛:仅用 50 个样本,重构 Agent 技能降本路线
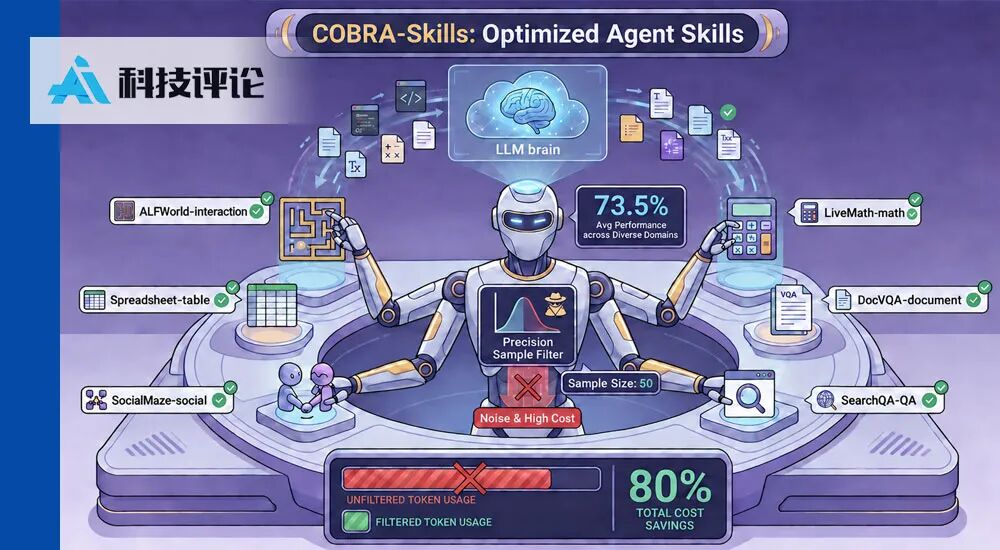
TL;DR - An interview profiles COBRA-Skills, a contextual-bandit-guided framework that selectively evaluates and evolves agent skills instead of relying on costly LLM trial and error. Using 50 optimization samples, it reportedly cut optimization costs by 55%–58% while achieving the highest average performance across six heterogeneous agent benchmarks.
- COBRA-Skills combines a two-layer MLP for reward prediction with LinearUCB for exploration, prioritizing skills with either high expected performance or high information value.
- Three evidence-driven operators—regeneration, rollout mutation, and crossover—update the skill pool conservatively, while logarithmically scheduled evolution reduces expensive teaching-model calls.
- Across Qwen, GPT-Nano, and Gemma target models, skills improved average performance over no-skill baselines by 13.1, 26.9, and 22.5 percentage points, respectively.
- Compared with SkillOpt, the method reduced teaching-model token usage by 67%–80%; ablations showed that removing either bandit selection or evolution lowered average performance by more than two points.