Teaching LLMs to Update Beliefs for Efficient Long-Horizon Interaction
Ranking
Overall
78
Content
90
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
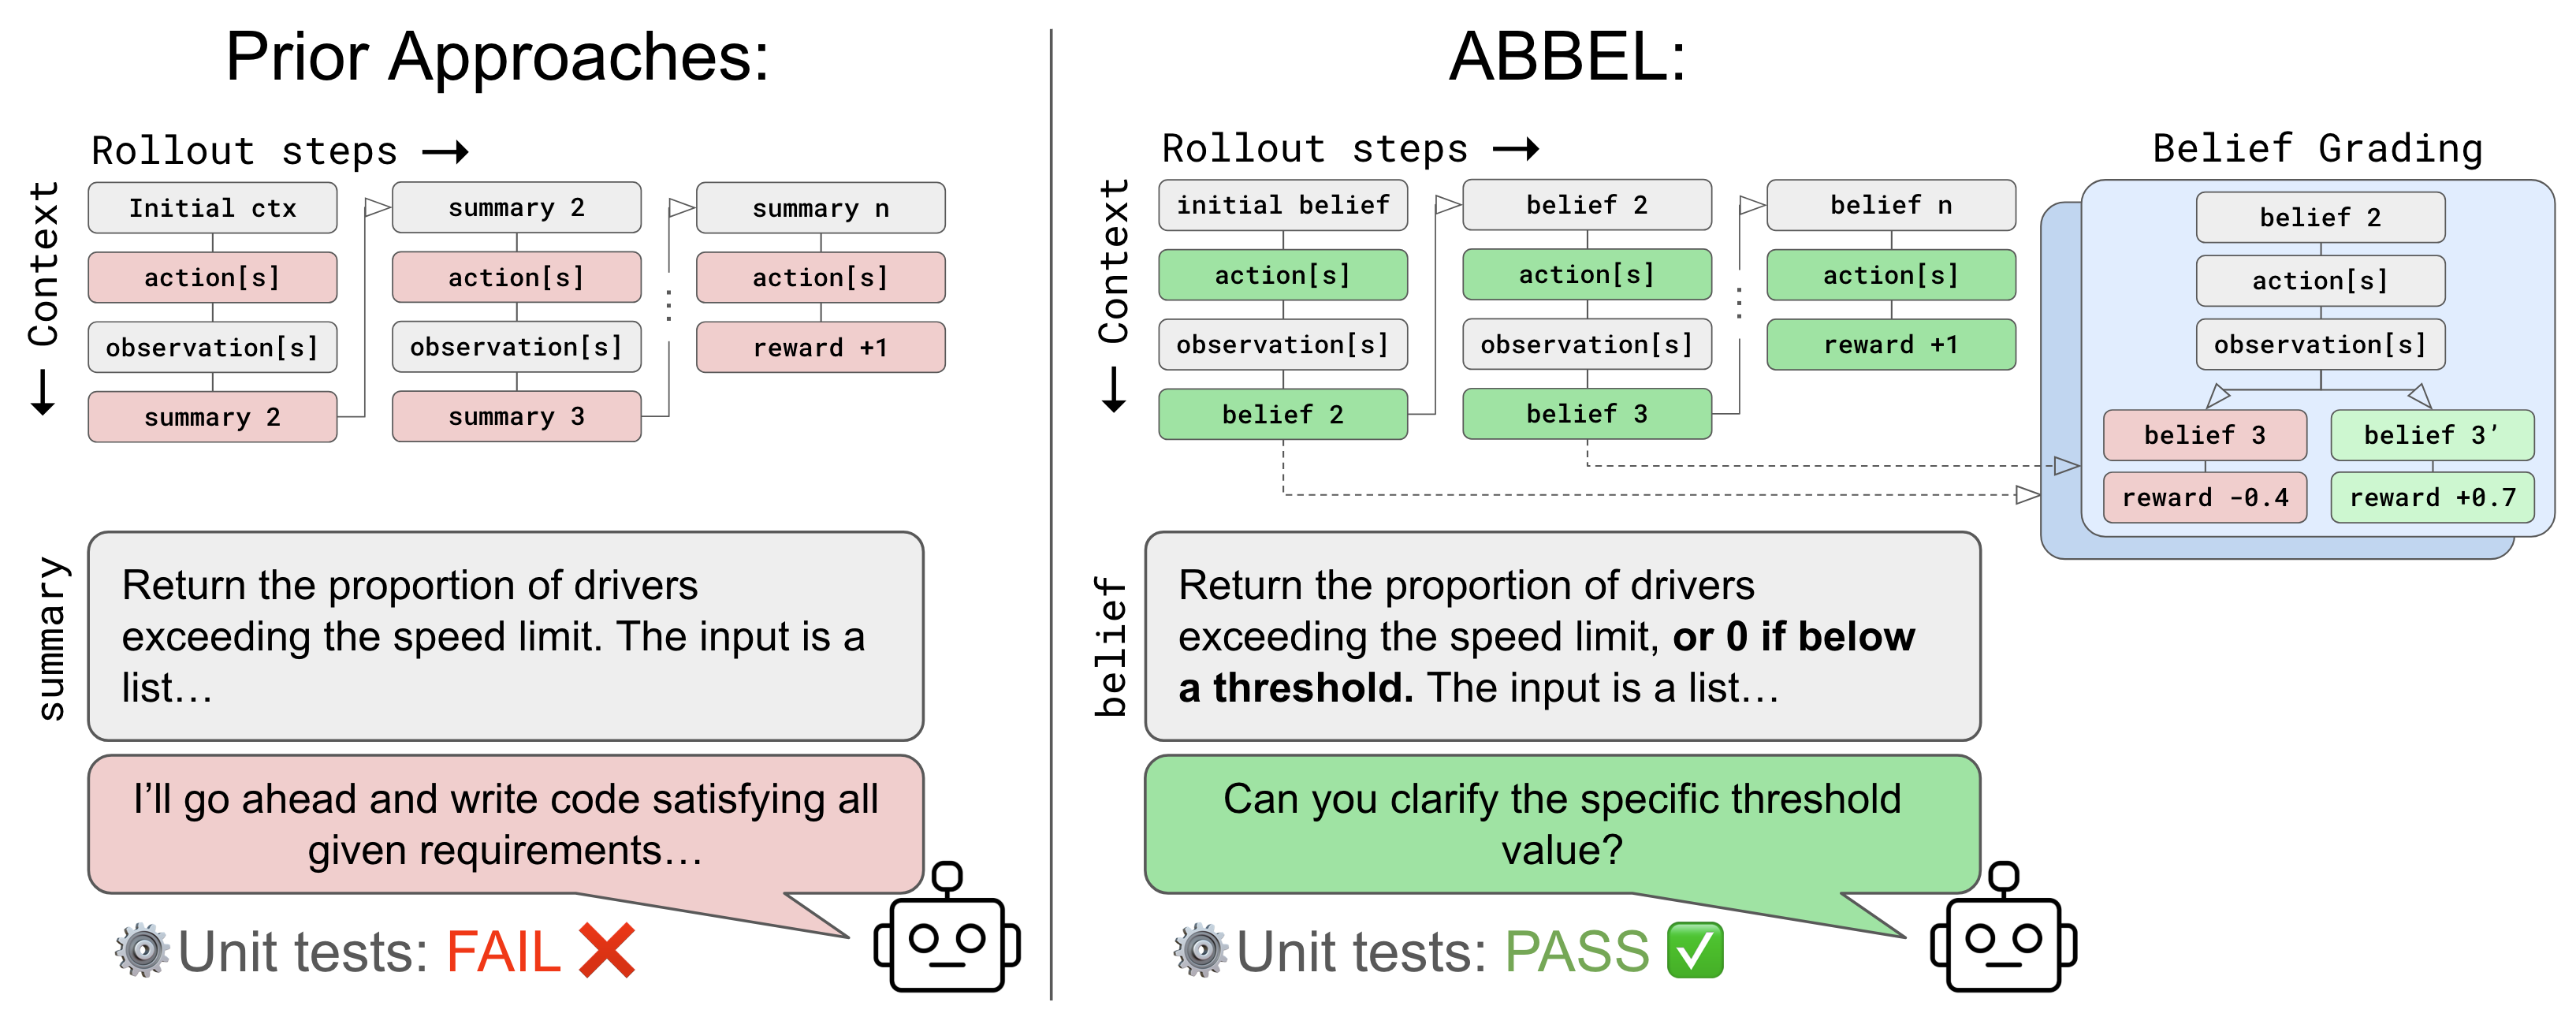
TL;DR - ABBEL trains long-horizon LLM agents to replace full interaction histories with supervised natural-language belief states. It narrows the performance gap from context compaction while reducing memory use and training requirements.
- Belief grading rewards states that retain enough information to reconstruct recent observations.
- On CollabBench, ABBEL recovered roughly half the gap to full-context models and trained in 50% fewer steps than ungraded summarization.
- Domain-specific grading approached or exceeded full-context learning efficiency on Combination Lock.
- Penalizing peak belief length reduced memory use in multi-objective QA with minimal performance loss.
Sources (1)
Teaching LLMs to Update Beliefs for Efficient Long-Horizon Interaction
Public signals
N/A
TL;DR - ABBEL trains long-horizon LLM agents to replace full interaction histories with supervised natural-language belief states. It narrows the performance gap from context compaction while reducing memory use and training requirements.
- Belief grading rewards states that retain enough information to reconstruct recent observations.
- On CollabBench, ABBEL recovered roughly half the gap to full-context models and trained in 50% fewer steps than ungraded summarization.
- Domain-specific grading approached or exceeded full-context learning efficiency on Combination Lock.
- Penalizing peak belief length reduced memory use in multi-objective QA with minimal performance loss.