我们让 vivago R1 拍了一部土耳其山寨「星战」,结果出乎意料
Ranking
Overall
43
Content
40
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
TL;DR - A hands-on review of vivago R1, the "unlimited-duration" multimodal video-creation agent launched by HiDream.ai (智象未来) at WAIC 2026, arguing that the real moat in AI video has shifted from base models to agent orchestration of long-form content.
- Architecture is aggregation + orchestration, not one giant model: vivago's own llms.txt lists Sora 2, Kling v2.6 Pro, Veo 3/3.1 plus in-house Vivago 2.0; all model calls happen server-side behind a vivago gateway, and users pick "skills" (17 of them, e.g.
cinematic-story-director,text-to-video) rather than model names. Skill params cap a single clip at 4–15s (default 5s; observed 10s), so "unlimited length" is engineered as multi-segment stitching. - Consistency comes from pipeline design, not model memory: the flagship skill runs Node0→Node9 — task understanding, story draft, A/V script, scene splitting, art direction, generating locked reference images for characters/scenes/props (N5), storyboards, prompts, per-scene video generation (N8), and final concatenation (N9). Every shot is generated against the same locked reference sheet.
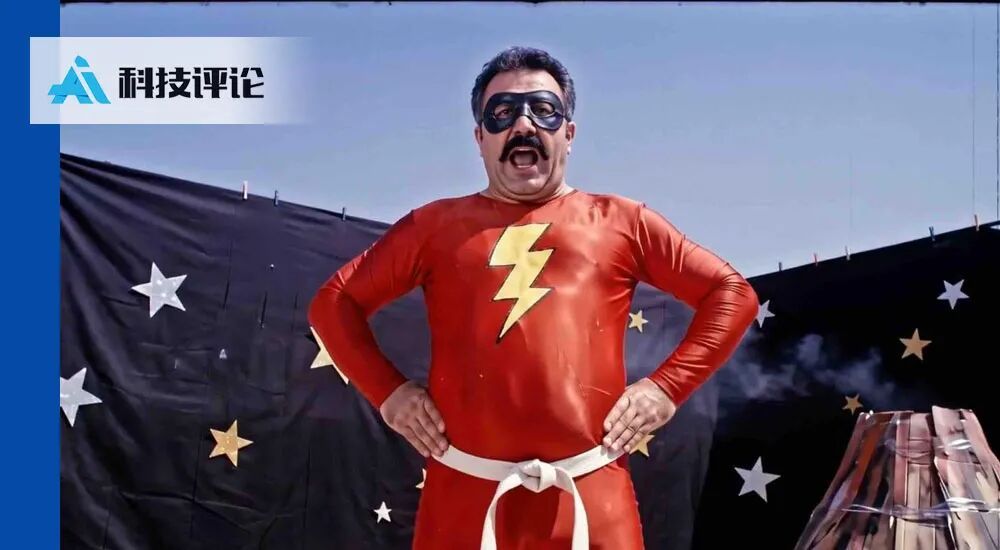
- Test results: a 1:11 Turkish-Yeşilçam-style sci-fi parody held character, prop, and deliberately cheap-looking style consistency end-to-end (only a ~3–4s quality dip near 0:41 and a subtle background drift at ~1:00); a 12-zodiac batch prompt auto-enumerated all signs into the pipeline without manual stitching. A fictional-product demo video was weakest, with spatially implausible usage — a world-model limitation.
- Vendor claims and context: HiDream cites ~85% "usable output" rate via its AgentOS scheduling layer, versus industry norms of 8–60s single clips (Veo 3.1 ~8s, Sora 2 ~60s, Kling 3.0 ~2min). The company reported over ¥2B raised in three months, including a ¥1.5B Series C.
Sources (1)
我们让 vivago R1 拍了一部土耳其山寨「星战」,结果出乎意料
Public signals
N/A
TL;DR - A hands-on review of vivago R1, the "unlimited-duration" multimodal video-creation agent launched by HiDream.ai (智象未来) at WAIC 2026, arguing that the real moat in AI video has shifted from base models to agent orchestration of long-form content.
- Architecture is aggregation + orchestration, not one giant model: vivago's own llms.txt lists Sora 2, Kling v2.6 Pro, Veo 3/3.1 plus in-house Vivago 2.0; all model calls happen server-side behind a vivago gateway, and users pick "skills" (17 of them, e.g.
cinematic-story-director,text-to-video) rather than model names. Skill params cap a single clip at 4–15s (default 5s; observed 10s), so "unlimited length" is engineered as multi-segment stitching. - Consistency comes from pipeline design, not model memory: the flagship skill runs Node0→Node9 — task understanding, story draft, A/V script, scene splitting, art direction, generating locked reference images for characters/scenes/props (N5), storyboards, prompts, per-scene video generation (N8), and final concatenation (N9). Every shot is generated against the same locked reference sheet.
- Test results: a 1:11 Turkish-Yeşilçam-style sci-fi parody held character, prop, and deliberately cheap-looking style consistency end-to-end (only a ~3–4s quality dip near 0:41 and a subtle background drift at ~1:00); a 12-zodiac batch prompt auto-enumerated all signs into the pipeline without manual stitching. A fictional-product demo video was weakest, with spatially implausible usage — a world-model limitation.
- Vendor claims and context: HiDream cites ~85% "usable output" rate via its AgentOS scheduling layer, versus industry norms of 8–60s single clips (Veo 3.1 ~8s, Sora 2 ~60s, Kling 3.0 ~2min). The company reported over ¥2B raised in three months, including a ¥1.5B Series C.