RT by @_akhaliq: NVIDIA just released the Nemotron VoiceChat model on Hugging Face First open…
Ranking
Overall
68
Content
75
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
TL;DR - NVIDIA has released Nemotron VoiceChat, described as the first open full-duplex speech model, on Hugging Face. It matters because full-duplex speech with tool calling pushes open-weight voice assistants closer to natural, interruptible conversation rather than rigid turn-based pipelines.
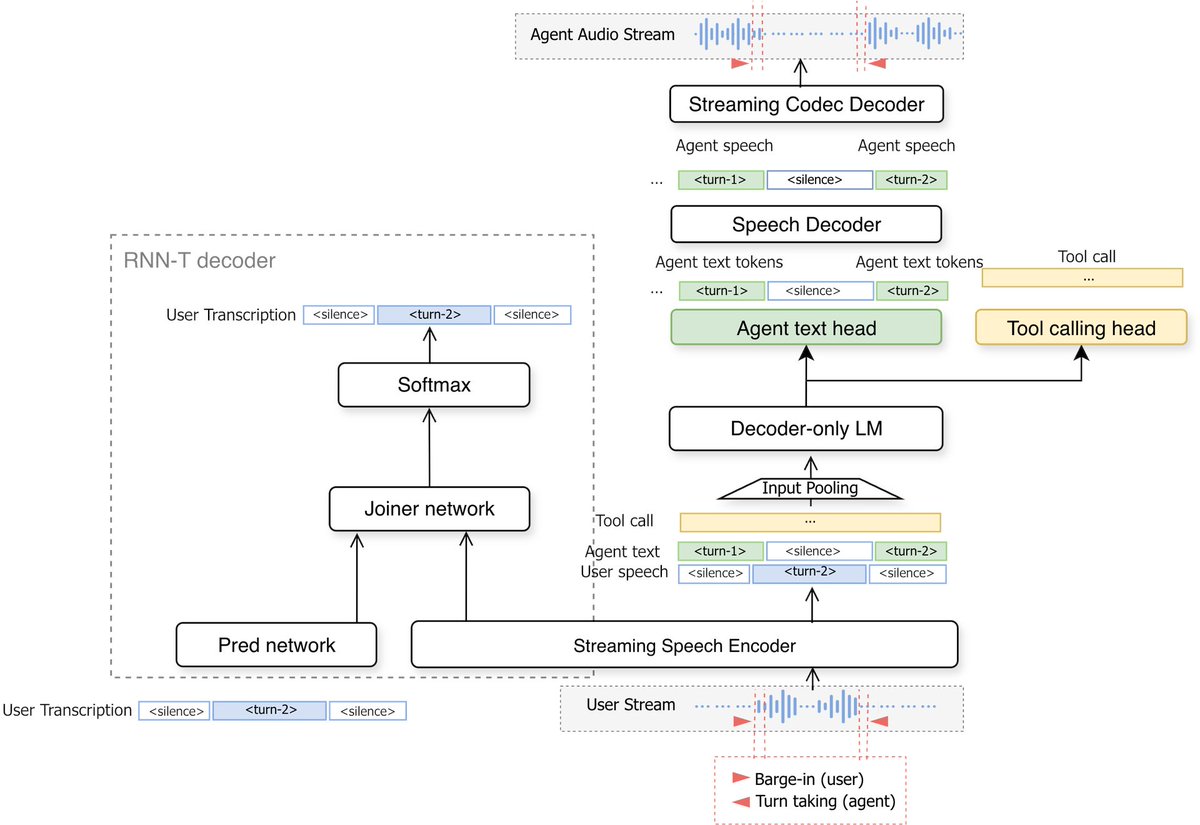
- Full-duplex operation: the model can listen and speak simultaneously, rather than alternating in strict request/response turns.
- Supports barge-in, so a user can interrupt mid-utterance and the model adapts — a key gap in most open speech stacks.
- Includes tool/function calling, letting the voice model trigger external actions directly instead of relying on a separate text-agent layer.
- Distributed on Hugging Face as an open release; content is thin (announcement post only), so no benchmarks, latency figures, model size, or license details are provided here.
Sources (1)
RT by @_akhaliq: NVIDIA just released the Nemotron VoiceChat model on Hugging Face First open…
Public signals
N/A
TL;DR - NVIDIA has released Nemotron VoiceChat, described as the first open full-duplex speech model, on Hugging Face. It matters because full-duplex speech with tool calling pushes open-weight voice assistants closer to natural, interruptible conversation rather than rigid turn-based pipelines.
- Full-duplex operation: the model can listen and speak simultaneously, rather than alternating in strict request/response turns.
- Supports barge-in, so a user can interrupt mid-utterance and the model adapts — a key gap in most open speech stacks.
- Includes tool/function calling, letting the voice model trigger external actions directly instead of relying on a separate text-agent layer.
- Distributed on Hugging Face as an open release; content is thin (announcement post only), so no benchmarks, latency figures, model size, or license details are provided here.