RT by @NVIDIAAI: ⚡ If you have or want a DGX Spark, this post might be the most important one you…
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
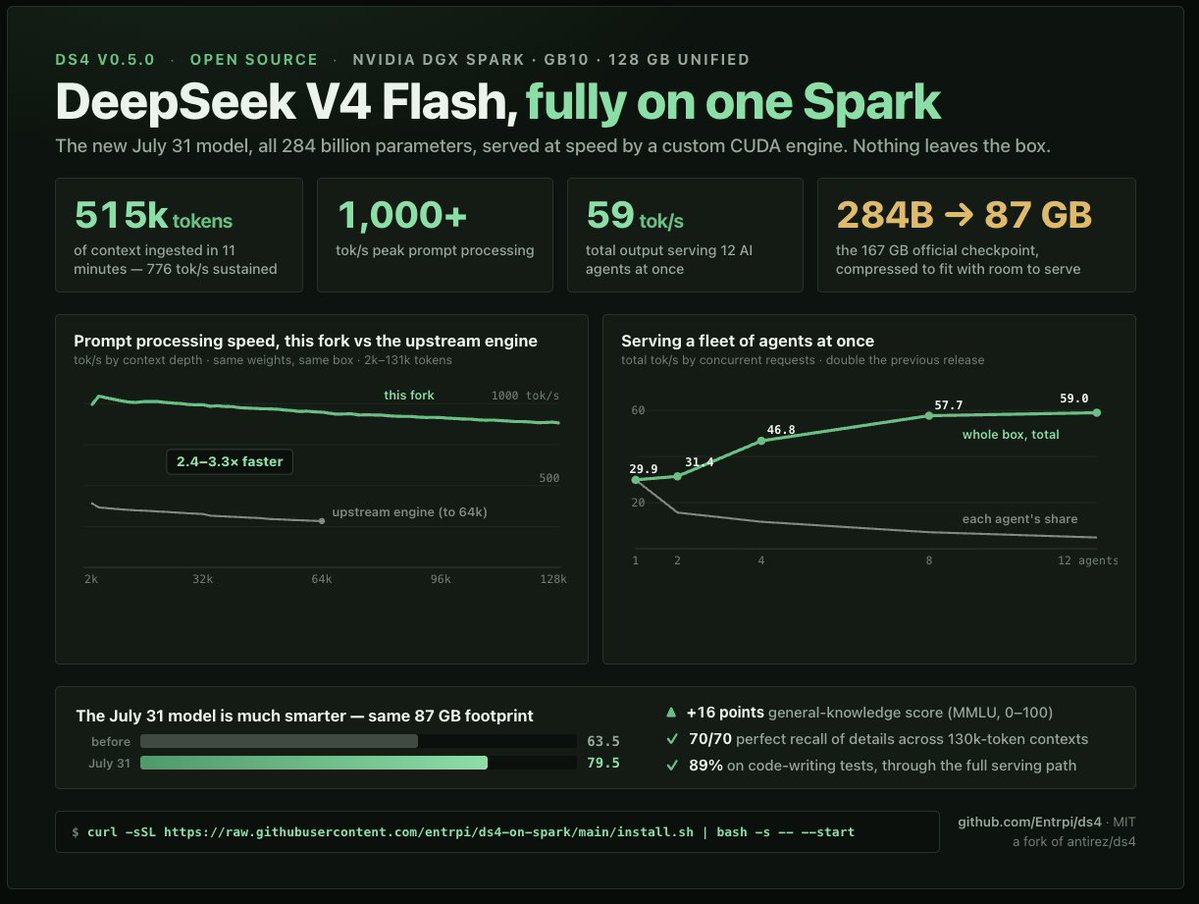
TL;DR - NVIDIA's AI account is promoting a one-command setup for serving DeepSeek V4 Flash (07-31, 284B parameters) on a single DGX Spark desktop system, claiming ~1,000 tok/s prefill and 59 tok/s in multi-agent serving. It matters because it positions a desktop-class box as viable for locally hosting a frontier-scale MoE-sized model for agentic workloads.
- Claims a 284B-parameter model runs on one DGX Spark unit, implying heavy reliance on quantization and/or sparse (MoE) activation plus unified memory — though the post itself gives no method details.
- Two throughput figures are cited: ~1,000 tok/s prefill (prompt ingestion) and 59 tok/s during multi-agent serving (concurrent decode), suggesting the target use case is local agent stacks rather than single-stream chat.
- Distribution angle is the selling point: "one command to install," i.e., a packaged serving stack aimed at lowering setup friction for Spark owners.
- Content is thin — it is the opening tweet of a thread (🧵) from a vendor account, so the numbers are unverified marketing claims with no stated benchmark harness, precision, context length, or batch size.
Sources (1)
RT by @NVIDIAAI: ⚡ If you have or want a DGX Spark, this post might be the most important one you…
TL;DR - NVIDIA's AI account is promoting a one-command setup for serving DeepSeek V4 Flash (07-31, 284B parameters) on a single DGX Spark desktop system, claiming ~1,000 tok/s prefill and 59 tok/s in multi-agent serving. It matters because it positions a desktop-class box as viable for locally hosting a frontier-scale MoE-sized model for agentic workloads.
- Claims a 284B-parameter model runs on one DGX Spark unit, implying heavy reliance on quantization and/or sparse (MoE) activation plus unified memory — though the post itself gives no method details.
- Two throughput figures are cited: ~1,000 tok/s prefill (prompt ingestion) and 59 tok/s during multi-agent serving (concurrent decode), suggesting the target use case is local agent stacks rather than single-stream chat.
- Distribution angle is the selling point: "one command to install," i.e., a packaged serving stack aimed at lowering setup friction for Spark owners.
- Content is thin — it is the opening tweet of a thread (🧵) from a vendor account, so the numbers are unverified marketing claims with no stated benchmark harness, precision, context length, or batch size.