R to @OpenAI: The new GPT-5.6 Sol powers all chats for paid users, including Instant, creating one…
Ranking
Overall
57
Content
60
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
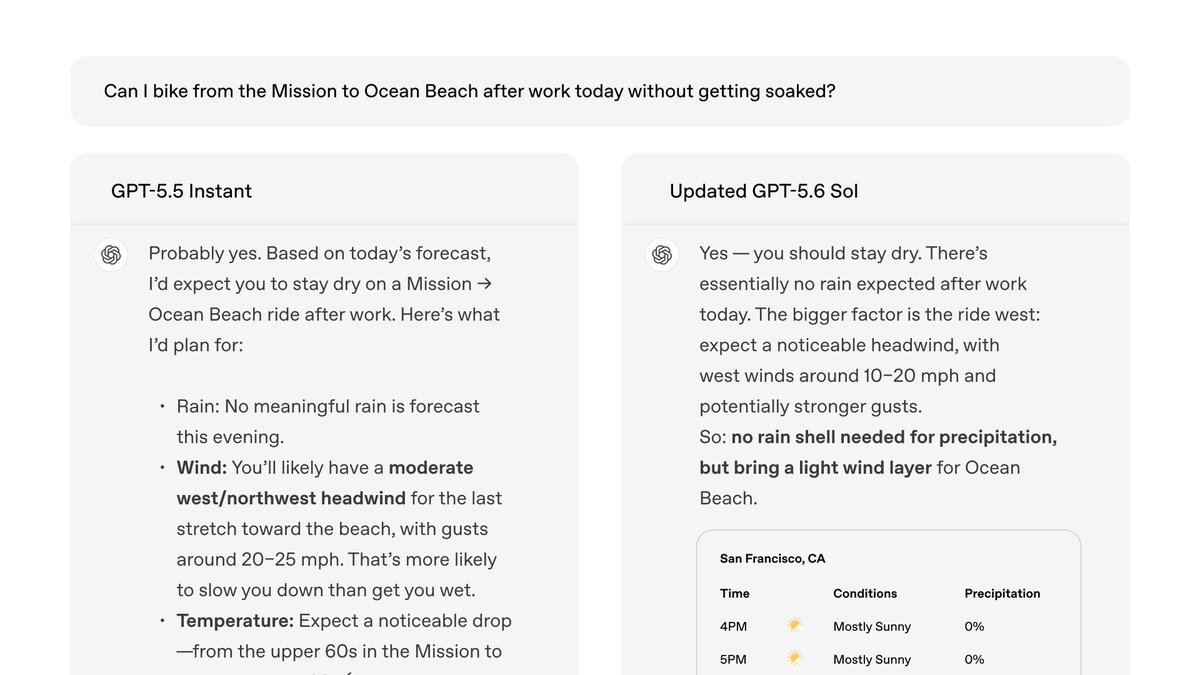
Merged summary
TL;DR - OpenAI announced that GPT-5.6 Sol now backs all chat modes for paid users, including the fast "Instant" tier, unifying model behavior across the product. The headline claim is a large factuality gain on high-stakes domains versus the prior GPT-5.5 Instant model.
- Rollout is product-wide for paid tiers: Instant and other chat modes are consolidated onto a single model (GPT-5.6 Sol) for a consistent experience, rather than routing to a weaker fast model.
- On an internal "high-stakes factuality" evaluation spanning finance, medicine, and law, GPT-5.6 Sol produced 68% fewer responses containing factual errors than GPT-5.5 Instant.
- The metric is a relative reduction in error-containing responses, not an absolute accuracy figure; no baseline rate, eval size, or methodology is disclosed in the post.
- Content is a short vendor announcement thread, so the claim is self-reported and unverified externally — treat the improvement as directional pending independent benchmarking.
Sources (1)
R to @OpenAI: The new GPT-5.6 Sol powers all chats for paid users, including Instant, creating one…
Public signals
N/A
TL;DR - OpenAI announced that GPT-5.6 Sol now backs all chat modes for paid users, including the fast "Instant" tier, unifying model behavior across the product. The headline claim is a large factuality gain on high-stakes domains versus the prior GPT-5.5 Instant model.
- Rollout is product-wide for paid tiers: Instant and other chat modes are consolidated onto a single model (GPT-5.6 Sol) for a consistent experience, rather than routing to a weaker fast model.
- On an internal "high-stakes factuality" evaluation spanning finance, medicine, and law, GPT-5.6 Sol produced 68% fewer responses containing factual errors than GPT-5.5 Instant.
- The metric is a relative reduction in error-containing responses, not an absolute accuracy figure; no baseline rate, eval size, or methodology is disclosed in the post.
- Content is a short vendor announcement thread, so the claim is self-reported and unverified externally — treat the improvement as directional pending independent benchmarking.