RT by @huggingface: A new foundation model that reads and generates DNA sequences was just released…
Ranking
Overall
71
Content
80
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
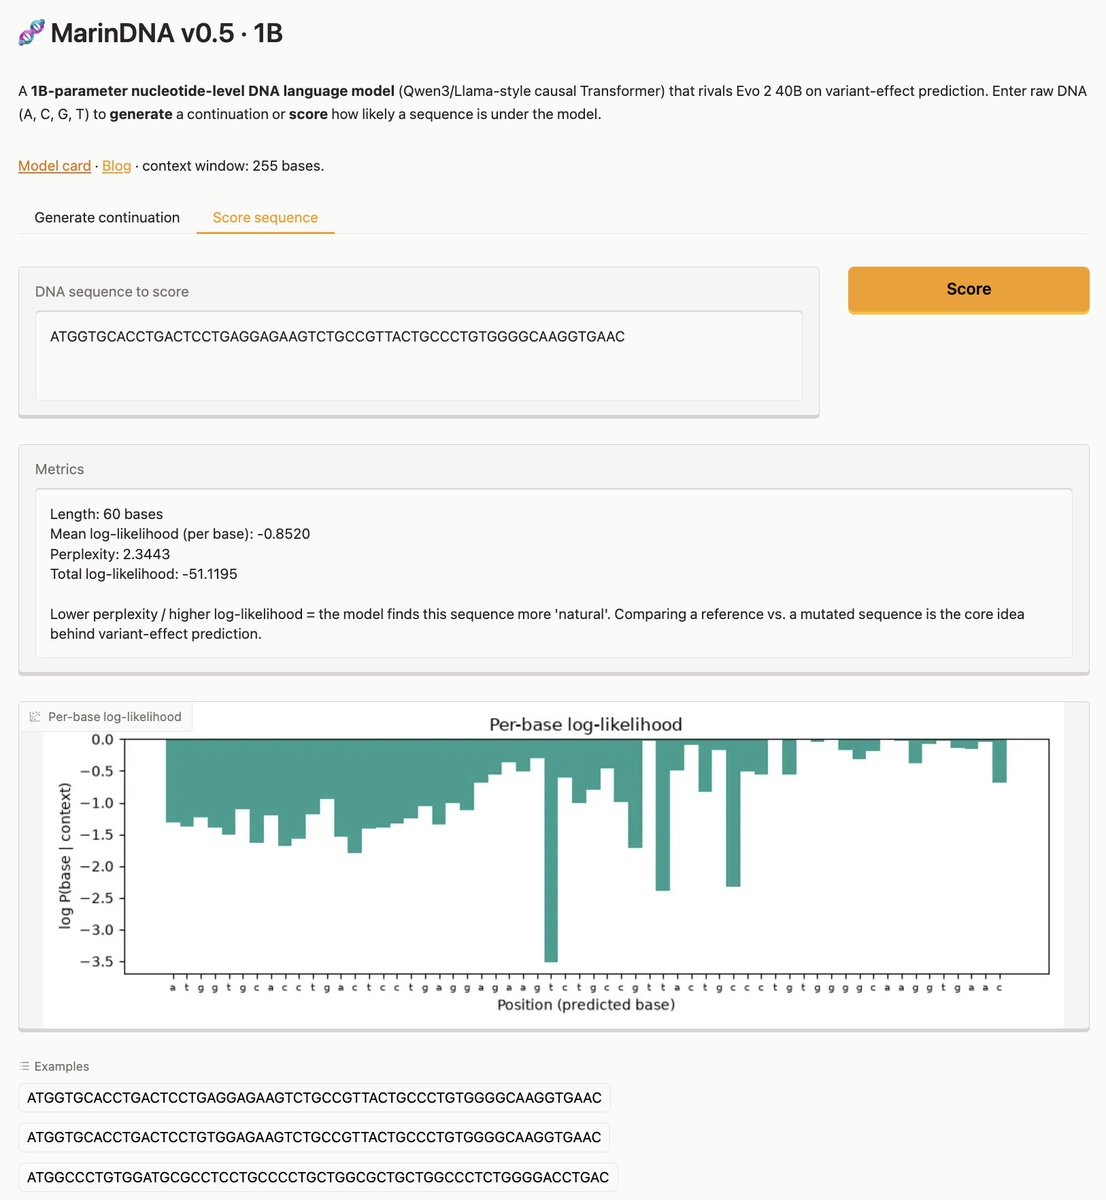
TL;DR - MarinDNA, a 1B-parameter genomic language model that reads and generates DNA sequences, was released on Hugging Face with a demo space. It matters because it reportedly matches Evo 2 40B on variant effect prediction while being ~2,330x faster, making genomic foundation models far cheaper to run.
- 1B-parameter gLM claimed to rival the 40B Evo 2 on variant effect prediction at roughly 1/2,330th the compute cost.
- Built on a standard Transformer architecture specifically so existing LLM infrastructure, tooling, and training methods could be reused directly.
- The team (Gonzalo Benegas, with @eczech0) attributes gains to data curation and scaling rather than novel architecture.
- Released openly on Hugging Face (
marin-dna) with an interactive demo space; detailed writeup on the OpenAthena blog. Benchmark numbers are from the authors' announcement and are not independently verified here.
Sources (1)
RT by @huggingface: A new foundation model that reads and generates DNA sequences was just released…
Public signals
N/A
TL;DR - MarinDNA, a 1B-parameter genomic language model that reads and generates DNA sequences, was released on Hugging Face with a demo space. It matters because it reportedly matches Evo 2 40B on variant effect prediction while being ~2,330x faster, making genomic foundation models far cheaper to run.
- 1B-parameter gLM claimed to rival the 40B Evo 2 on variant effect prediction at roughly 1/2,330th the compute cost.
- Built on a standard Transformer architecture specifically so existing LLM infrastructure, tooling, and training methods could be reused directly.
- The team (Gonzalo Benegas, with @eczech0) attributes gains to data curation and scaling rather than novel architecture.
- Released openly on Hugging Face (
marin-dna) with an interactive demo space; detailed writeup on the OpenAthena blog. Benchmark numbers are from the authors' announcement and are not independently verified here.