RT by @NVIDIAAI: As we prepare for Qwen 3.8 drop, @NVIDIAAI team led the optimizations in vLLM for…
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
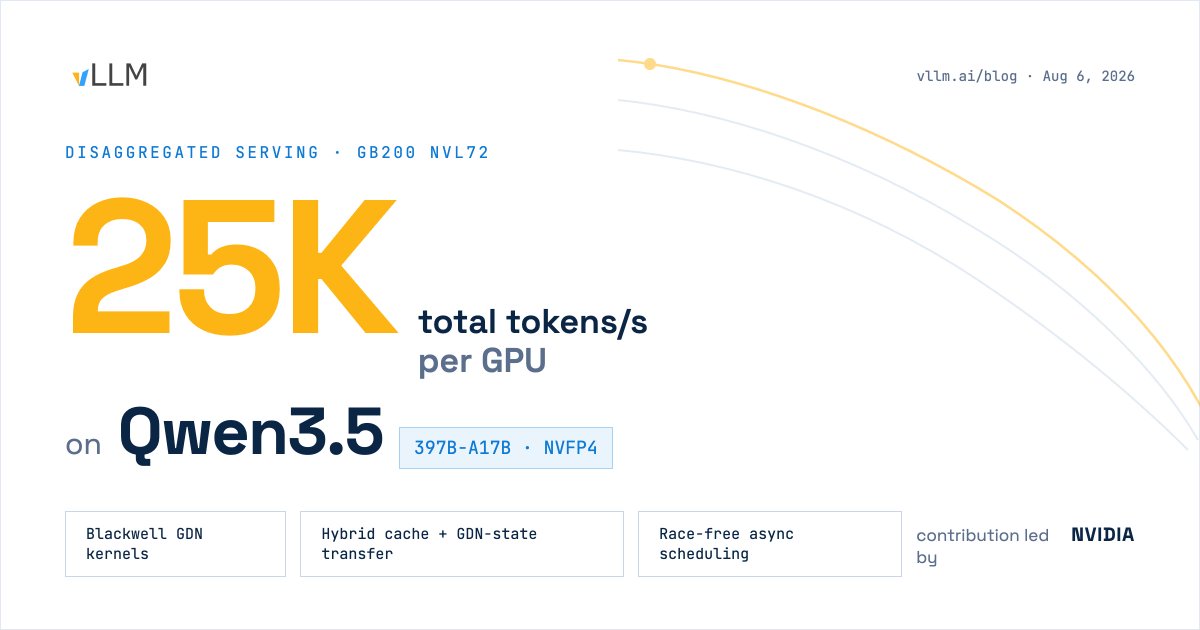
TL;DR - NVIDIA's AI team announced it led inference optimizations for Qwen 3.5 in vLLM, reporting 25K total tokens/s/GPU on a GB200 system, with a linked vLLM blog deep dive. It matters as a concrete datapoint on how vendor-led serving optimizations translate open-weight models into production-grade throughput ahead of the next Qwen release.
- Claimed headline result: ~25K total tokens/s/GPU (combined prefill+decode, per the "total" framing) for Qwen 3.5 served on NVIDIA GB200 (Grace-Blackwell) hardware.
- Optimization work was contributed upstream into vLLM rather than a proprietary stack, so the gains land in a widely used open-source serving engine.
- Framed as groundwork for an upcoming "Qwen 3.8" release — i.e., the serving-path optimizations are expected to carry forward to the next model drop.
- Content is a short promotional post; specific techniques (kernels, quantization, attention/MoE handling, batching, disaggregation) are not stated here and would require the referenced vLLM blog post (vllm.ai/blog/2026-08-06-qwen…) to verify.
Sources (1)
RT by @NVIDIAAI: As we prepare for Qwen 3.8 drop, @NVIDIAAI team led the optimizations in vLLM for…
TL;DR - NVIDIA's AI team announced it led inference optimizations for Qwen 3.5 in vLLM, reporting 25K total tokens/s/GPU on a GB200 system, with a linked vLLM blog deep dive. It matters as a concrete datapoint on how vendor-led serving optimizations translate open-weight models into production-grade throughput ahead of the next Qwen release.
- Claimed headline result: ~25K total tokens/s/GPU (combined prefill+decode, per the "total" framing) for Qwen 3.5 served on NVIDIA GB200 (Grace-Blackwell) hardware.
- Optimization work was contributed upstream into vLLM rather than a proprietary stack, so the gains land in a widely used open-source serving engine.
- Framed as groundwork for an upcoming "Qwen 3.8" release — i.e., the serving-path optimizations are expected to carry forward to the next model drop.
- Content is a short promotional post; specific techniques (kernels, quantization, attention/MoE handling, batching, disaggregation) are not stated here and would require the referenced vLLM blog post (vllm.ai/blog/2026-08-06-qwen…) to verify.