Toward Skill-Native LLMs Skill Entropy for Benchmarking and Training Long-Horizon Reasoning paper…
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
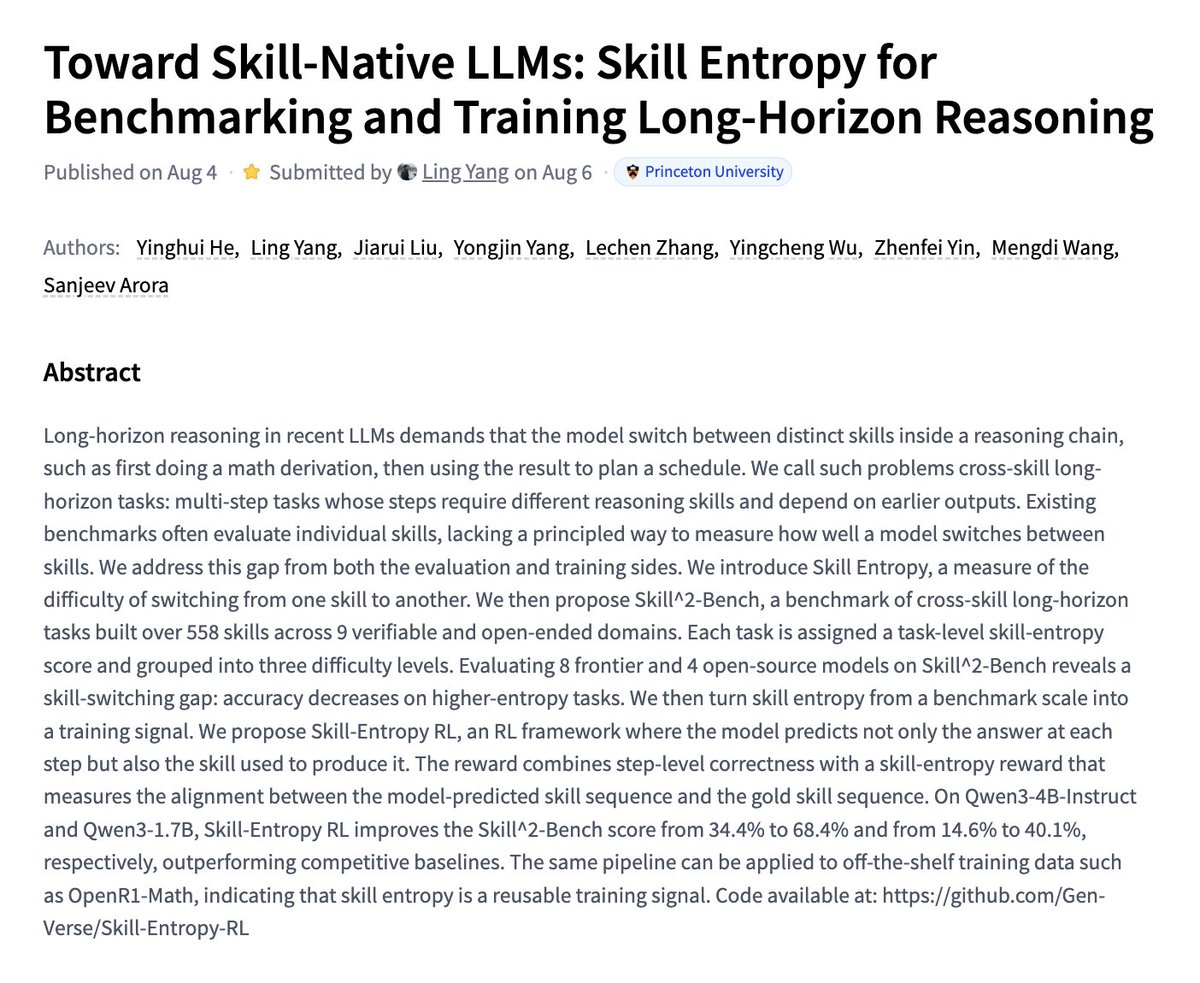
TL;DR - A shared paper announcement for "Toward Skill-Native LLMs: Skill Entropy for Benchmarking and Training Long-Horizon Reasoning," which proposes a skill-entropy metric for evaluating and training LLMs on long-horizon reasoning. Content is limited to the title and a Hugging Face papers link, so the details below are inferred from the title.
- Frames LLM capability in terms of "skills" as native units, arguing models should be skill-native rather than only token- or task-level optimized.
- Introduces "skill entropy" as a measurable quantity, positioned for dual use: benchmarking existing models and serving as a training signal.
- Targets long-horizon reasoning — multi-step tasks where single-shot accuracy metrics poorly capture the diversity or distribution of skills a model applies.
- No results, datasets, or baselines are available in the provided content; the post is a link-share with no reported numbers.
Sources (1)
Toward Skill-Native LLMs Skill Entropy for Benchmarking and Training Long-Horizon Reasoning paper…
TL;DR - A shared paper announcement for "Toward Skill-Native LLMs: Skill Entropy for Benchmarking and Training Long-Horizon Reasoning," which proposes a skill-entropy metric for evaluating and training LLMs on long-horizon reasoning. Content is limited to the title and a Hugging Face papers link, so the details below are inferred from the title.
- Frames LLM capability in terms of "skills" as native units, arguing models should be skill-native rather than only token- or task-level optimized.
- Introduces "skill entropy" as a measurable quantity, positioned for dual use: benchmarking existing models and serving as a training signal.
- Targets long-horizon reasoning — multi-step tasks where single-shot accuracy metrics poorly capture the diversity or distribution of skills a model applies.
- No results, datasets, or baselines are available in the provided content; the post is a link-share with no reported numbers.