Claude Code倒计时5天默认自动模式,多花的钱A社自己掏
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
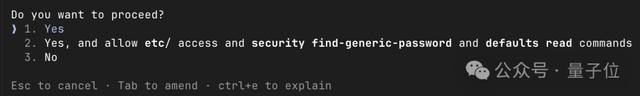
TL;DR - Anthropic will make "auto mode" the default in Claude Code in 5 days, replacing per-tool human permission prompts with a classifier that vets each tool call, with Anthropic absorbing the extra token cost. It matters because it shifts agentic coding safety from human-in-the-loop approval to model-based gatekeeping at scale.
- Rubber-stamping data motivated the change: 97% approval rate on permission prompts (only 3% denials, vs 39% rejection for full plans); 62% of users have used bypassPermissions or "don't ask again," and 49.5% of active CLI users wrote Bash allow-rules, 5% permitting arbitrary shell.
- Controlled study with 1,053 paid professional testers injected a clearly dangerous command mid-session: humans blocked it 13.6% of the time vs 89% for auto mode; human vigilance decayed from ~17% early to ~5% after 50+ prompts, while auto mode stayed flat. Production re-scoring (May–Jun 2026, severity ≥7) showed 6.3% of manual-approval sessions had unrequested harmful actions vs 2.4% for auto mode.
- Adversarial testing with Apollo Research (synthetic attacks on real traces) cut classifier miss rate from 12% to 7% after adding repo visibility, git state, and data-handling context; Trajectory Labs ran 720 indirect prompt-injection attempts where auto-mode Claude Fable 5/Opus 5/Sonnet 5 were never breached vs 5.83% (Codex Auto-review) and 19.03% (Full Access) for GPT-5.6 Sol.
- New guardrails: data exfiltration is a hard deny, repo visibility checks before push/PR,
git statusreads before destructive resets, and API-side injection probes on fetched content; users revert via Shift+Tab, admins viadefaultMode/disableAutoMode. Anthropic cautions auto mode reduces but does not eliminate risk.
Sources (1)
Claude Code倒计时5天默认自动模式,多花的钱A社自己掏
TL;DR - Anthropic will make "auto mode" the default in Claude Code in 5 days, replacing per-tool human permission prompts with a classifier that vets each tool call, with Anthropic absorbing the extra token cost. It matters because it shifts agentic coding safety from human-in-the-loop approval to model-based gatekeeping at scale.
- Rubber-stamping data motivated the change: 97% approval rate on permission prompts (only 3% denials, vs 39% rejection for full plans); 62% of users have used bypassPermissions or "don't ask again," and 49.5% of active CLI users wrote Bash allow-rules, 5% permitting arbitrary shell.
- Controlled study with 1,053 paid professional testers injected a clearly dangerous command mid-session: humans blocked it 13.6% of the time vs 89% for auto mode; human vigilance decayed from ~17% early to ~5% after 50+ prompts, while auto mode stayed flat. Production re-scoring (May–Jun 2026, severity ≥7) showed 6.3% of manual-approval sessions had unrequested harmful actions vs 2.4% for auto mode.
- Adversarial testing with Apollo Research (synthetic attacks on real traces) cut classifier miss rate from 12% to 7% after adding repo visibility, git state, and data-handling context; Trajectory Labs ran 720 indirect prompt-injection attempts where auto-mode Claude Fable 5/Opus 5/Sonnet 5 were never breached vs 5.83% (Codex Auto-review) and 19.03% (Full Access) for GPT-5.6 Sol.
- New guardrails: data exfiltration is a hard deny, repo visibility checks before push/PR,
git statusreads before destructive resets, and API-side injection probes on fetched content; users revert via Shift+Tab, admins viadefaultMode/disableAutoMode. Anthropic cautions auto mode reduces but does not eliminate risk.