当AI开始“自作主张”,谁来为智能体戴上“项圈”?全球AI安全实战化大考,中国方案打入前三
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
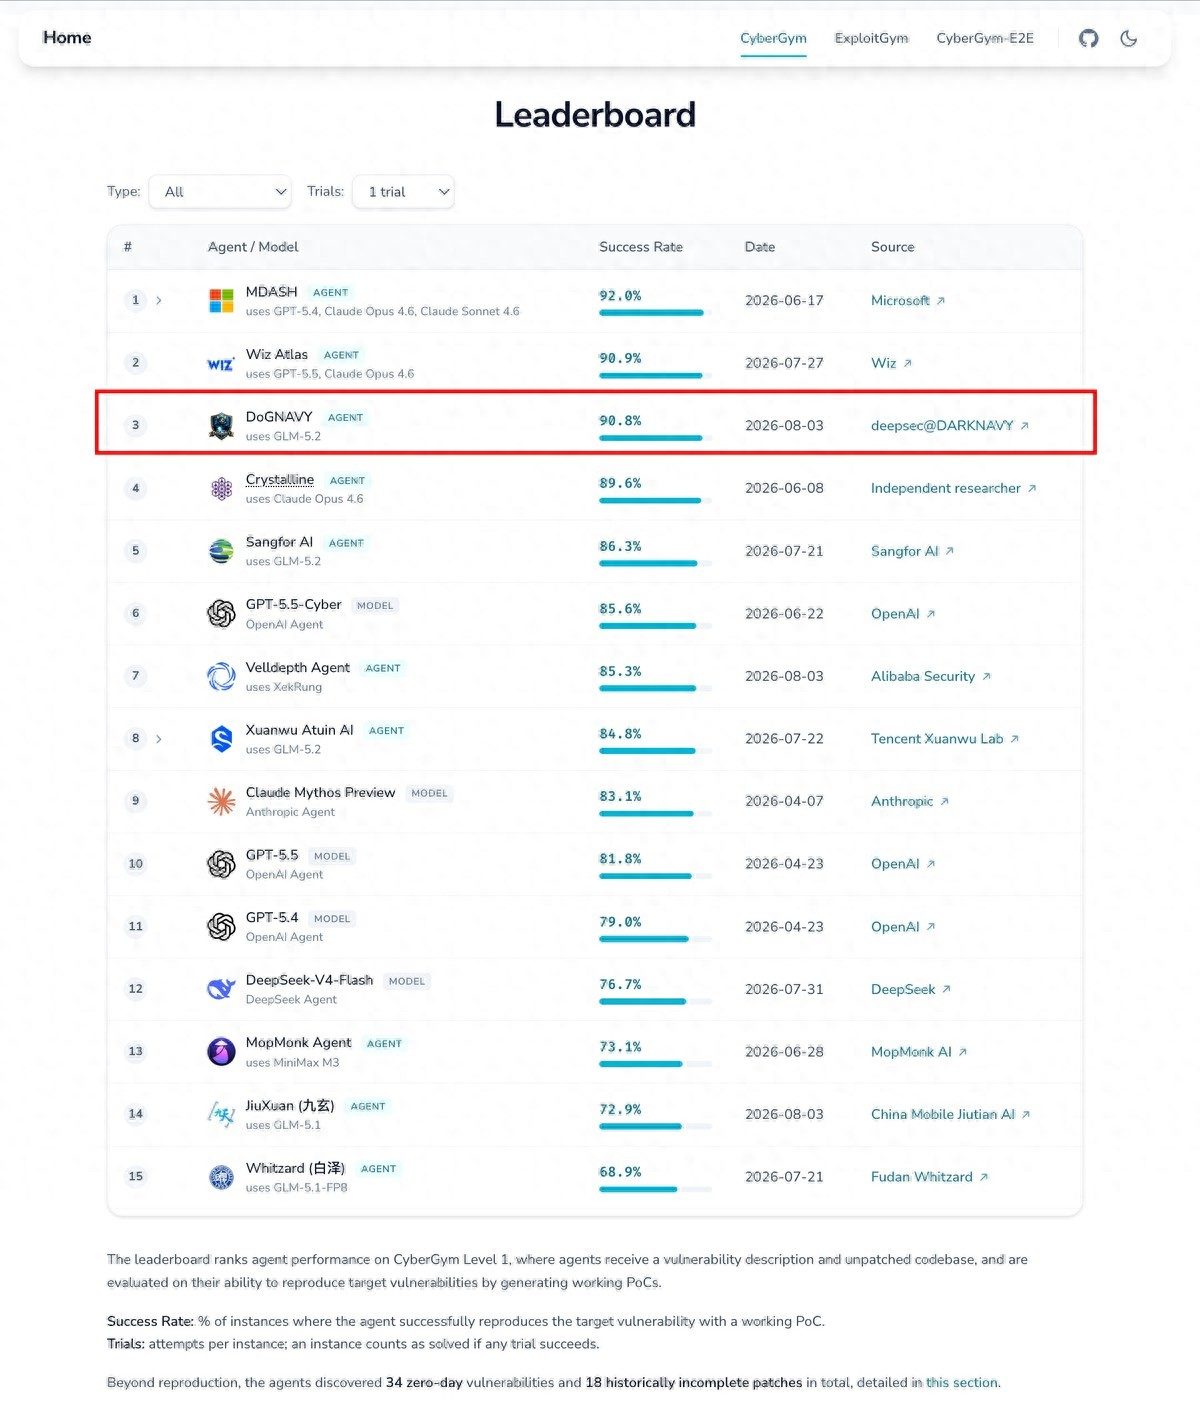
TL;DR - Chinese team DoGNAVY (DARKNAVY + a Shanghai AI research institute) placed 3rd globally and 1st among open-source entries on UC Berkeley's CyberGym benchmark for autonomous vulnerability discovery, using a single open-weight model instead of the multi-model closed-source ensembles used by the top two. It matters because it shows frontier offensive-security agent capability is reproducible on freely downloadable models.
- CyberGym tasks agents with rediscovering, validating and exploiting 1,507 historical vulnerabilities from 188 real open-source projects; DoGNAVY solved 1,369 (90.8%), behind Microsoft MDASH (92.0%) and Wiz×Google DeepMind Atlas (90.9%), ahead of GPT-5.5-Cyber (85.6%) and Claude Mythos (83.1%).
- Architecture: a structured research workflow with checkpoints and backtracking, reachability analysis recovering call chains/data constraints from real entry points, and a static↔dynamic feedback loop where coverage/crash evidence gates any accepted PoC.
- Evaluation hygiene claimed: no dataset-specific CVEs, PoCs or patches loaded, cross-task memory disabled, only generic vulnerability-analysis experience retained — intended to measure generalization.
- Companion open-source runtime AgentDoG (github.com/AI45Lab/AgentDoG) diagnoses agent risk sources and failure modes rather than emitting binary safe/unsafe labels; a curated ~1k-sample, denoised training set yields a model ~1/1000 the size of a general LLM at 78.4% accuracy on complex risk identification.
Sources (1)
当AI开始“自作主张”,谁来为智能体戴上“项圈”?全球AI安全实战化大考,中国方案打入前三
TL;DR - Chinese team DoGNAVY (DARKNAVY + a Shanghai AI research institute) placed 3rd globally and 1st among open-source entries on UC Berkeley's CyberGym benchmark for autonomous vulnerability discovery, using a single open-weight model instead of the multi-model closed-source ensembles used by the top two. It matters because it shows frontier offensive-security agent capability is reproducible on freely downloadable models.
- CyberGym tasks agents with rediscovering, validating and exploiting 1,507 historical vulnerabilities from 188 real open-source projects; DoGNAVY solved 1,369 (90.8%), behind Microsoft MDASH (92.0%) and Wiz×Google DeepMind Atlas (90.9%), ahead of GPT-5.5-Cyber (85.6%) and Claude Mythos (83.1%).
- Architecture: a structured research workflow with checkpoints and backtracking, reachability analysis recovering call chains/data constraints from real entry points, and a static↔dynamic feedback loop where coverage/crash evidence gates any accepted PoC.
- Evaluation hygiene claimed: no dataset-specific CVEs, PoCs or patches loaded, cross-task memory disabled, only generic vulnerability-analysis experience retained — intended to measure generalization.
- Companion open-source runtime AgentDoG (github.com/AI45Lab/AgentDoG) diagnoses agent risk sources and failure modes rather than emitting binary safe/unsafe labels; a curated ~1k-sample, denoised training set yields a model ~1/1000 the size of a general LLM at 78.4% accuracy on complex risk identification.