Introducing NVIDIA Nemotron 3.5 Lightning⚡ An open 30B MoE model with 3B active parameters, built…
Ranking
Overall
57
Content
60
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
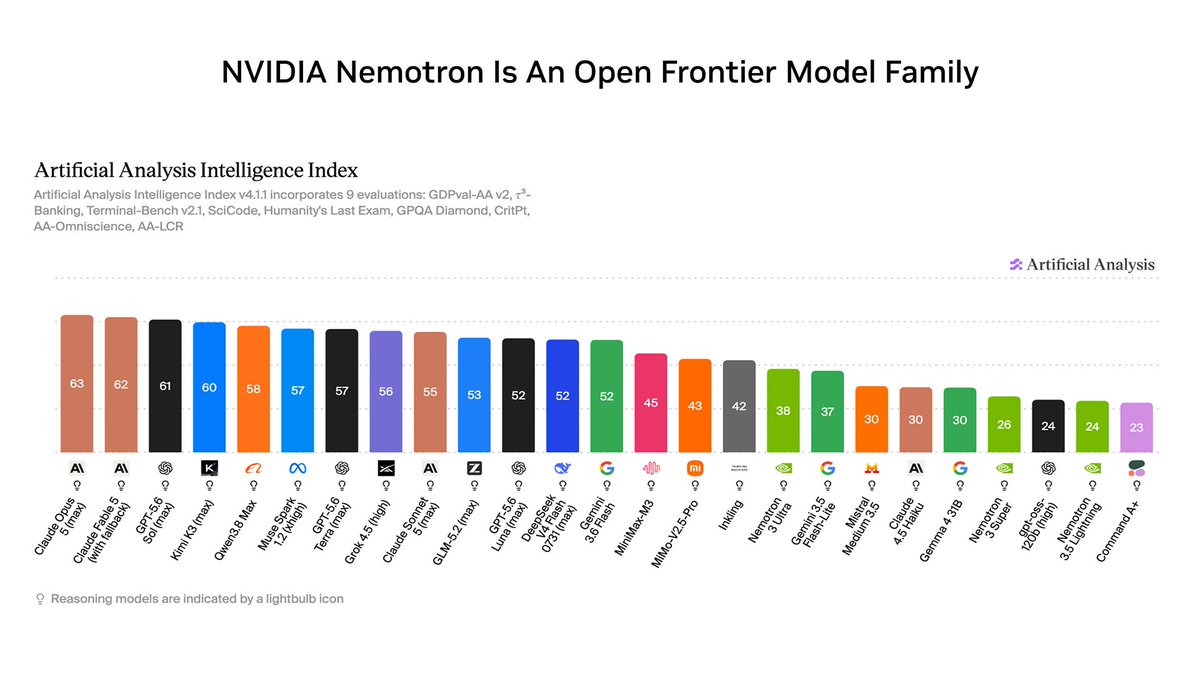
Merged summary
TL;DR - NVIDIA announced Nemotron 3.5 Lightning, an open 30B mixture-of-experts model activating only 3B parameters per token, targeted at always-on agentic workloads. It matters because it pushes the sparse-MoE efficiency frontier for high-volume, latency-sensitive agent deployments rather than raw frontier capability.
- Architecture: 30B total parameters with ~3B active per token (MoE sparsity ~10:1), trading capacity for cheap per-token inference.
- Claimed performance: up to 4x the output (token generation) speed of comparably sized models; no benchmark quality numbers are given in the post.
- Positioning: explicitly built for "always-on agents" running high-volume, specialized tasks — i.e., throughput/cost-per-task optimization over general-purpose reasoning.
- Openness: released as an open model, continuing NVIDIA's Nemotron open-weights line; details are thin since this is a launch announcement only.
Sources (1)
Introducing NVIDIA Nemotron 3.5 Lightning⚡ An open 30B MoE model with 3B active parameters, built…
Public signals
N/A
TL;DR - NVIDIA announced Nemotron 3.5 Lightning, an open 30B mixture-of-experts model activating only 3B parameters per token, targeted at always-on agentic workloads. It matters because it pushes the sparse-MoE efficiency frontier for high-volume, latency-sensitive agent deployments rather than raw frontier capability.
- Architecture: 30B total parameters with ~3B active per token (MoE sparsity ~10:1), trading capacity for cheap per-token inference.
- Claimed performance: up to 4x the output (token generation) speed of comparably sized models; no benchmark quality numbers are given in the post.
- Positioning: explicitly built for "always-on agents" running high-volume, specialized tasks — i.e., throughput/cost-per-task optimization over general-purpose reasoning.
- Openness: released as an open model, continuing NVIDIA's Nemotron open-weights line; details are thin since this is a launch announcement only.