RT by @huggingface: 24GB VRAM is enough to run MOSS-VL locally.@Open_MOSS We’ve released FP8 and…
Ranking
Overall
71
Content
80
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
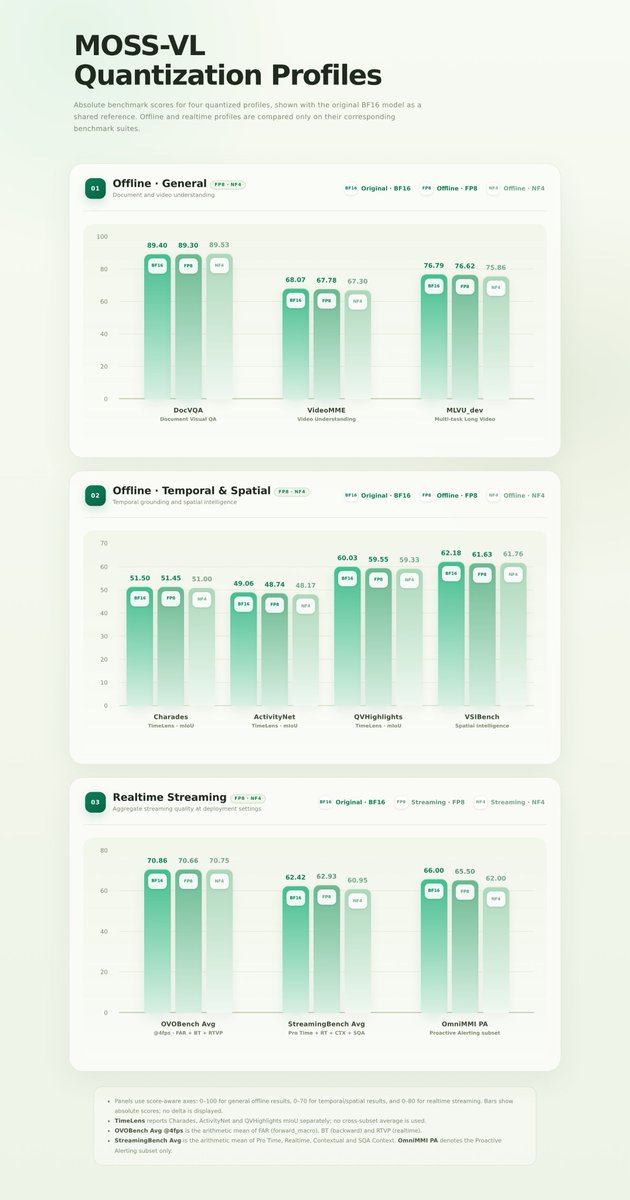
TL;DR - OpenMOSS released FP8 and NF4 quantized versions of its MOSS-VL image and video models, enabling local deployment on 24GB consumer GPUs. The releases substantially reduce VRAM usage while reportedly retaining performance close to BF16 on selected benchmarks.
- MOSS-VL-Instruct supports local image and video inference, batch processing, and serving.
- MOSS-VL-Realtime provides timestamp-aware understanding of cameras, livestreams, and continuous video.
- NF4 offers lower memory use and more headroom for long-context streaming; FP8 balances capability and inference performance.
- All four quantized checkpoints are available through Hugging Face and ModelScope.
Sources (1)
RT by @huggingface: 24GB VRAM is enough to run MOSS-VL locally.@Open_MOSS We’ve released FP8 and…
Public signals
N/A
TL;DR - OpenMOSS released FP8 and NF4 quantized versions of its MOSS-VL image and video models, enabling local deployment on 24GB consumer GPUs. The releases substantially reduce VRAM usage while reportedly retaining performance close to BF16 on selected benchmarks.
- MOSS-VL-Instruct supports local image and video inference, batch processing, and serving.
- MOSS-VL-Realtime provides timestamp-aware understanding of cameras, livestreams, and continuous video.
- NF4 offers lower memory use and more headroom for long-context streaming; FP8 balances capability and inference performance.
- All four quantized checkpoints are available through Hugging Face and ModelScope.