RT by @_akhaliq: HarnessEval-W: Agentifying the Evaluation of Visual Worlds A new benchmark that…
Ranking
Overall
57
Content
60
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
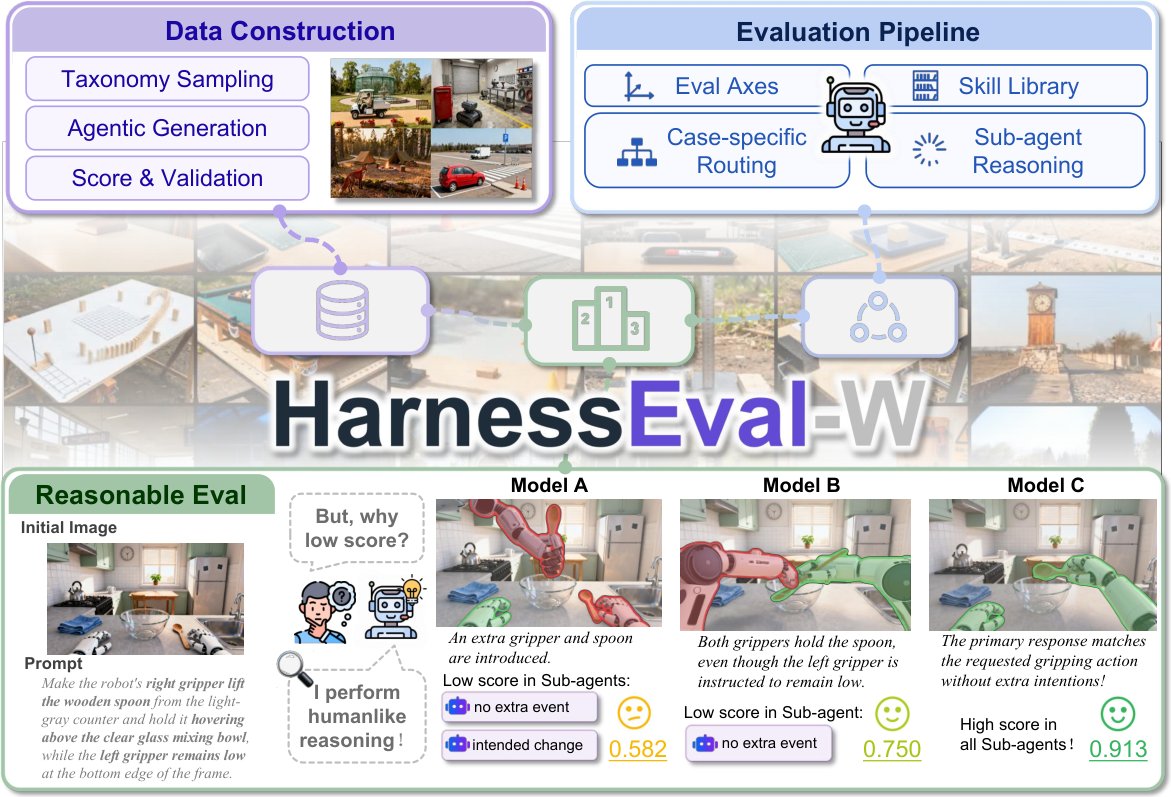
TL;DR - HarnessEval-W is a benchmark for evaluating visual world models through specialized sub-agents. It aims to make scoring more transparent and auditable by providing a reasoning chain for each score.
- Applies the harness evaluation paradigm to visual world models.
- Uses specialized sub-agents to assess model outputs.
- Produces traceable reasoning for individual scores.
- No benchmark results or implementation details are provided in the item.
Sources (1)
RT by @_akhaliq: HarnessEval-W: Agentifying the Evaluation of Visual Worlds A new benchmark that…
Public signals
N/A
TL;DR - HarnessEval-W is a benchmark for evaluating visual world models through specialized sub-agents. It aims to make scoring more transparent and auditable by providing a reasoning chain for each score.
- Applies the harness evaluation paradigm to visual world models.
- Uses specialized sub-agents to assess model outputs.
- Produces traceable reasoning for individual scores.
- No benchmark results or implementation details are provided in the item.