菲尔兹奖得主入局大模型!4B手机Qwen+云端GLM刷爆ARC-AGI 3
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
TL;DR - Startup Mostik unveiled a trained “bridge” that transfers hidden states directly between frozen models, letting a cloud-based 753B GLM-5.2 guide a phone-scale 4B Qwen-3.5 without generating text. The approach reportedly improves small-model accuracy while sharply reducing large-model inference costs, though full technical details remain undisclosed.
- The large model performs only lower-cost prompt prefill; the 4B model handles all token-by-token decoding and final text generation.
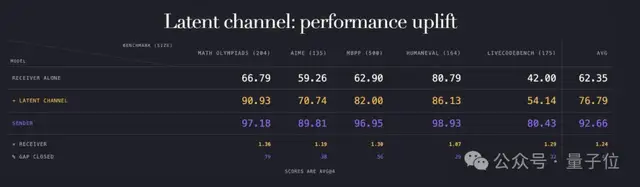
- Mostik reports that the bridge closes about 50% of the performance gap between the models, raises the 4B model’s accuracy by 25%, and doubles performance on harder subsets.
- Reported large-model reasoning cost falls to roughly one-twentieth of conventional use, with a better performance-compute tradeoff than text-based model handoffs.
- Only the bridge is trained; both independently developed models remain frozen, suggesting useful internal representations can transfer across model families.
Sources (1)
菲尔兹奖得主入局大模型!4B手机Qwen+云端GLM刷爆ARC-AGI 3
TL;DR - Startup Mostik unveiled a trained “bridge” that transfers hidden states directly between frozen models, letting a cloud-based 753B GLM-5.2 guide a phone-scale 4B Qwen-3.5 without generating text. The approach reportedly improves small-model accuracy while sharply reducing large-model inference costs, though full technical details remain undisclosed.
- The large model performs only lower-cost prompt prefill; the 4B model handles all token-by-token decoding and final text generation.
- Mostik reports that the bridge closes about 50% of the performance gap between the models, raises the 4B model’s accuracy by 25%, and doubles performance on harder subsets.
- Reported large-model reasoning cost falls to roughly one-twentieth of conventional use, with a better performance-compute tradeoff than text-based model handoffs.
- Only the bridge is trained; both independently developed models remain frozen, suggesting useful internal representations can transfer across model families.