原生全模态技术战略闭环,智象(HiDream.ai)发布具身世界模型HiDream-O1-Embodied
Ranking
Overall
68
Content
75
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
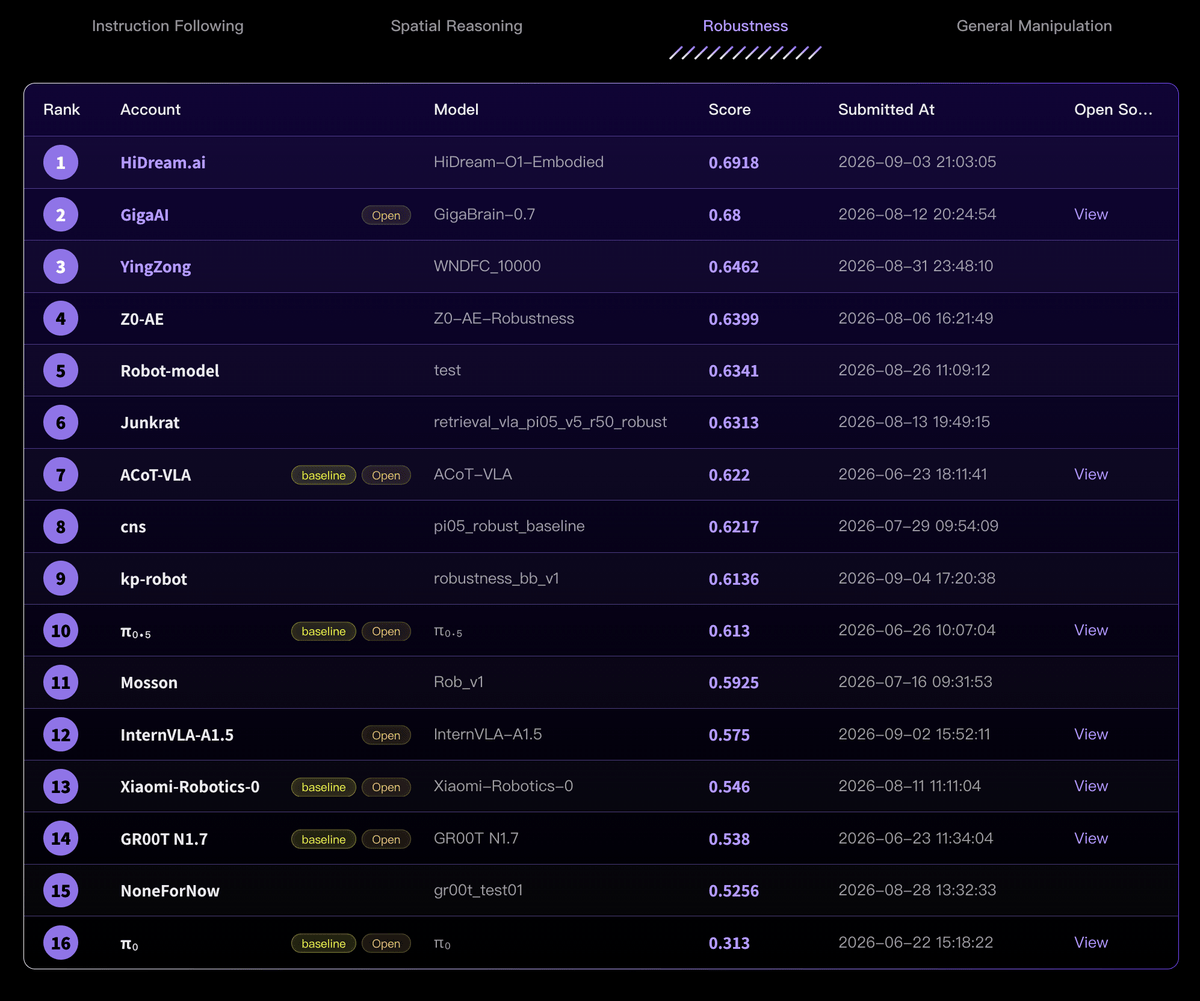
TL;DR - HiDream.ai launched HiDream-O1-Embodied, a multimodal embodied world model designed to connect language and visual understanding with robotic prediction and execution. It scored 0.692 and ranked first on RoboColiseum’s robustness benchmark, according to the company-provided announcement.
- The model unifies image, video, 3D, and action representations to support an end-to-end understanding–simulation–execution workflow.
- It combines varied language-command understanding, multi-view visual perception, and training under degraded or incomplete conditions to improve robustness.
- HiDream.ai uses a “real-data foundation plus generative augmentation” strategy, expanding motion-capture samples by varying environments, lighting, and objects while preserving physical constraints.
- The release complements HiDream-O1-World: the earlier model targets interactive world understanding and simulation, while HiDream-O1-Embodied focuses on physical-world operation.
Sources (1)
原生全模态技术战略闭环,智象(HiDream.ai)发布具身世界模型HiDream-O1-Embodied
Public signals
N/A
TL;DR - HiDream.ai launched HiDream-O1-Embodied, a multimodal embodied world model designed to connect language and visual understanding with robotic prediction and execution. It scored 0.692 and ranked first on RoboColiseum’s robustness benchmark, according to the company-provided announcement.
- The model unifies image, video, 3D, and action representations to support an end-to-end understanding–simulation–execution workflow.
- It combines varied language-command understanding, multi-view visual perception, and training under degraded or incomplete conditions to improve robustness.
- HiDream.ai uses a “real-data foundation plus generative augmentation” strategy, expanding motion-capture samples by varying environments, lighting, and objects while preserving physical constraints.
- The release complements HiDream-O1-World: the earlier model targets interactive world understanding and simulation, while HiDream-O1-Embodied focuses on physical-world operation.