开源Top2!实测阶跃Step 5 Preview,真有点猛啊…
Ranking
Overall
64
Content
70
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
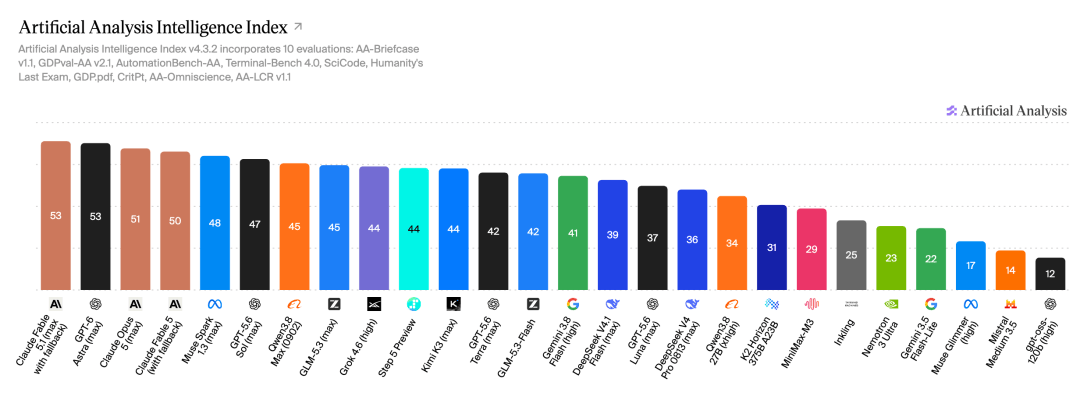
TL;DR - StepFun’s Step 5 Preview is a 600B-parameter sparse MoE model designed for long-horizon agent tasks while activating only 27B parameters per token. It reportedly ranks second among open models on Artificial Analysis and targets a strong cost-performance tradeoff.
- The model combines a 92-layer “narrow but deep” Transformer architecture with a 1M-token context window to support multi-step reasoning and tool use.
- Sparse MoE, Hybrid Sparse, Sparse GQA, and low-level hardware optimizations aim to reduce the compute and memory costs of long contexts.
- Long-horizon reinforcement learning and context compaction help the model retain task goals across dozens of tool calls and iterative correction loops.
- Hands-on tests produced Blender scenes, 3D and 2D games, and a writing website; outputs were usable after several refinement rounds but still showed occasional layout and detail errors.
Sources (1)
开源Top2!实测阶跃Step 5 Preview,真有点猛啊…
Public signals
N/A
TL;DR - StepFun’s Step 5 Preview is a 600B-parameter sparse MoE model designed for long-horizon agent tasks while activating only 27B parameters per token. It reportedly ranks second among open models on Artificial Analysis and targets a strong cost-performance tradeoff.
- The model combines a 92-layer “narrow but deep” Transformer architecture with a 1M-token context window to support multi-step reasoning and tool use.
- Sparse MoE, Hybrid Sparse, Sparse GQA, and low-level hardware optimizations aim to reduce the compute and memory costs of long contexts.
- Long-horizon reinforcement learning and context compaction help the model retain task goals across dozens of tool calls and iterative correction loops.
- Hands-on tests produced Blender scenes, 3D and 2D games, and a writing website; outputs were usable after several refinement rounds but still showed occasional layout and detail errors.