6天烧光2000多万,拿下开源第一!小米史无前例「炼丹直播」收官
Ranking
Overall
71
Content
80
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
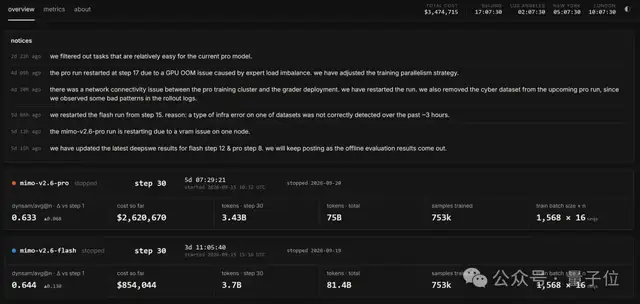
TL;DR - Xiaomi released MiMo-V2.6-Pro and Flash after livestreaming a six-day, $3.5 million reinforcement-learning run, alongside model weights, training infrastructure, and over 7,000 RL environments. Pro reportedly leads the Artificial Analysis open-model ranking and approaches closed frontier models on some agent benchmarks.
- MiMo-V2.6-Pro is a 1.02-trillion-parameter MoE model with 42 billion active parameters; 30 RL steps raised its DeepSWE v1.1 score from 58.4 to 72.57, while Flash improved from 48.7 to 65.68.
- The asynchronous RL pipeline scaled generation, execution, grading, and training across coding, general-agent, vision, and cybersecurity environments; graders consumed 12.7% of Pro’s $2.6 million training cost.
- Xiaomi mitigated reward hacking by stripping answer leakage, disabling network access, deploying an adversarial Hack Agent, and auditing trajectories, keeping identified cheating below 2%.
- Freezing the MoE router addressed severe expert-load imbalance during RL, while distributed storage and dynamic sample mixing handled large, variable-length agent trajectories.
Sources (1)
6天烧光2000多万,拿下开源第一!小米史无前例「炼丹直播」收官
Public signals
N/A
TL;DR - Xiaomi released MiMo-V2.6-Pro and Flash after livestreaming a six-day, $3.5 million reinforcement-learning run, alongside model weights, training infrastructure, and over 7,000 RL environments. Pro reportedly leads the Artificial Analysis open-model ranking and approaches closed frontier models on some agent benchmarks.
- MiMo-V2.6-Pro is a 1.02-trillion-parameter MoE model with 42 billion active parameters; 30 RL steps raised its DeepSWE v1.1 score from 58.4 to 72.57, while Flash improved from 48.7 to 65.68.
- The asynchronous RL pipeline scaled generation, execution, grading, and training across coding, general-agent, vision, and cybersecurity environments; graders consumed 12.7% of Pro’s $2.6 million training cost.
- Xiaomi mitigated reward hacking by stripping answer leakage, disabling network access, deploying an adversarial Hack Agent, and auditing trajectories, keeping identified cheating below 2%.
- Freezing the MoE router addressed severe expert-load imbalance during RL, while distributed storage and dynamic sample mixing handled large, variable-length agent trajectories.