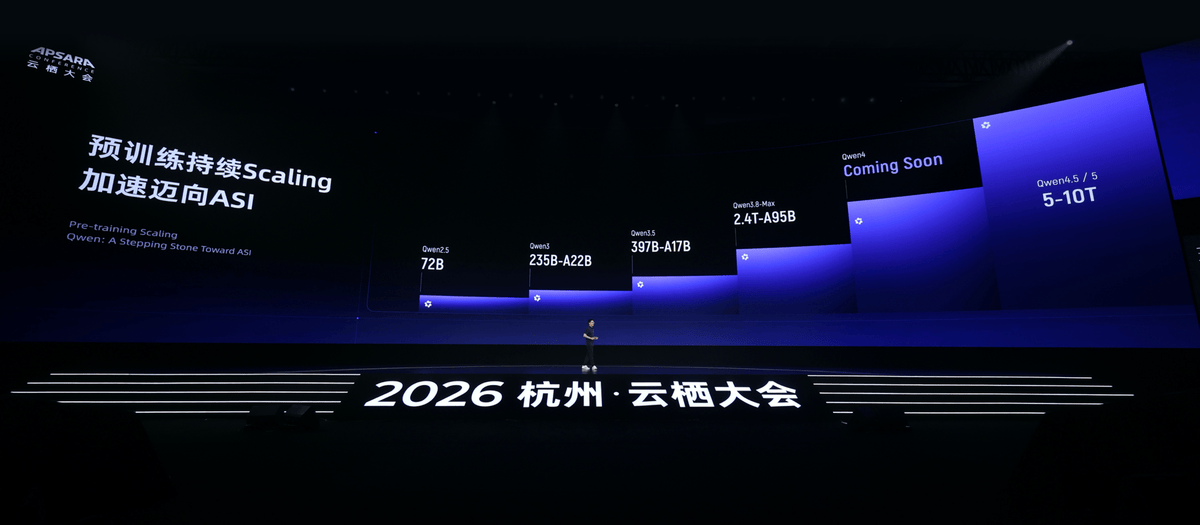
阿里研究员透露Qwen4.5后模型将扩展至5-10T参数
Ranking
Overall
68
Content
75
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
TL;DR - Alibaba outlined its Qwen roadmap, saying Qwen4 is in training and future Qwen4.5/Qwen5 models are planned to scale to 5–10 trillion total parameters. The announcement also highlights recursive self-improvement, a lower-cost next-generation architecture, and broad multimodal model upgrades.
- Qwen3.8-Max reportedly completed 33 autonomous training iterations over more than a month, building workflows and data and diagnosing defects without human participation; its Artificial Analysis score rose from 40 to 45.
- The model autonomously adapted Qwen3.8-Flash inference to a previously unseen T-Head GPU, improving single-instance throughput by 96%.
- Alibaba says Qwen3.8-Flash’s architecture cuts training cost by nearly 90% while activating relatively few parameters for efficient inference.
- New or upcoming releases span unified multimodal, image, music, world, video, and speech models, alongside an agent platform for cross-application tasks on smartphones.
Sources (1)
阿里研究员透露Qwen4.5后模型将扩展至5-10T参数
Public signals
N/A
TL;DR - Alibaba outlined its Qwen roadmap, saying Qwen4 is in training and future Qwen4.5/Qwen5 models are planned to scale to 5–10 trillion total parameters. The announcement also highlights recursive self-improvement, a lower-cost next-generation architecture, and broad multimodal model upgrades.
- Qwen3.8-Max reportedly completed 33 autonomous training iterations over more than a month, building workflows and data and diagnosing defects without human participation; its Artificial Analysis score rose from 40 to 45.
- The model autonomously adapted Qwen3.8-Flash inference to a previously unseen T-Head GPU, improving single-instance throughput by 96%.
- Alibaba says Qwen3.8-Flash’s architecture cuts training cost by nearly 90% while activating relatively few parameters for efficient inference.
- New or upcoming releases span unified multimodal, image, music, world, video, and speech models, alongside an agent platform for cross-application tasks on smartphones.