阿里公布全模态模型新进展,Qwen4和下代视频模型均在训练中
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
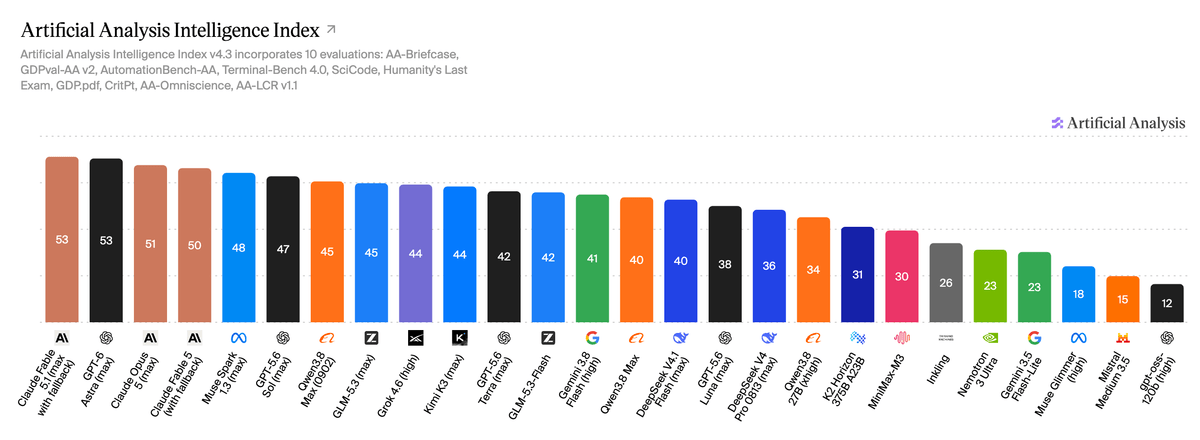
TL;DR - Alibaba announced broad updates across its Qwen and Wan model families, including Qwen4 training, a next-generation video model due in November, and new image, audio, translation, and world models. The roadmap emphasizes unified multimodal intelligence, lower compute costs, larger models, and partially autonomous model improvement.
- Qwen4 is training on a new architecture, while Qwen4.5 and Qwen5 are planned to scale toward 5–10 trillion total parameters.
- Qwen3.8-Max reportedly completed 33 effective self-improvement iterations over a month without human participation, autonomously constructing data, experiments, and training workflows.
- Qwen3.8-Flash cuts training costs by nearly 90%, while autonomous adaptation of its SGLang stack to a new GPU reportedly increased single-instance inference throughput by 96%.
- Alibaba also unveiled Qwen3.8-Omni-Flash, Qwen-Audio-3.1, Qwen-Image-3.1, and HappyOyster 2.0 Preview; its next video model targets longer, more controllable, narratively coherent generation.
Sources (1)
阿里公布全模态模型新进展,Qwen4和下代视频模型均在训练中
TL;DR - Alibaba announced broad updates across its Qwen and Wan model families, including Qwen4 training, a next-generation video model due in November, and new image, audio, translation, and world models. The roadmap emphasizes unified multimodal intelligence, lower compute costs, larger models, and partially autonomous model improvement.
- Qwen4 is training on a new architecture, while Qwen4.5 and Qwen5 are planned to scale toward 5–10 trillion total parameters.
- Qwen3.8-Max reportedly completed 33 effective self-improvement iterations over a month without human participation, autonomously constructing data, experiments, and training workflows.
- Qwen3.8-Flash cuts training costs by nearly 90%, while autonomous adaptation of its SGLang stack to a new GPU reportedly increased single-instance inference throughput by 96%.
- Alibaba also unveiled Qwen3.8-Omni-Flash, Qwen-Audio-3.1, Qwen-Image-3.1, and HappyOyster 2.0 Preview; its next video model targets longer, more controllable, narratively coherent generation.