基元律动韩凯:从多模型调度到反馈闭环,探索Agent持续进化
Ranking
Overall
57
Content
60
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
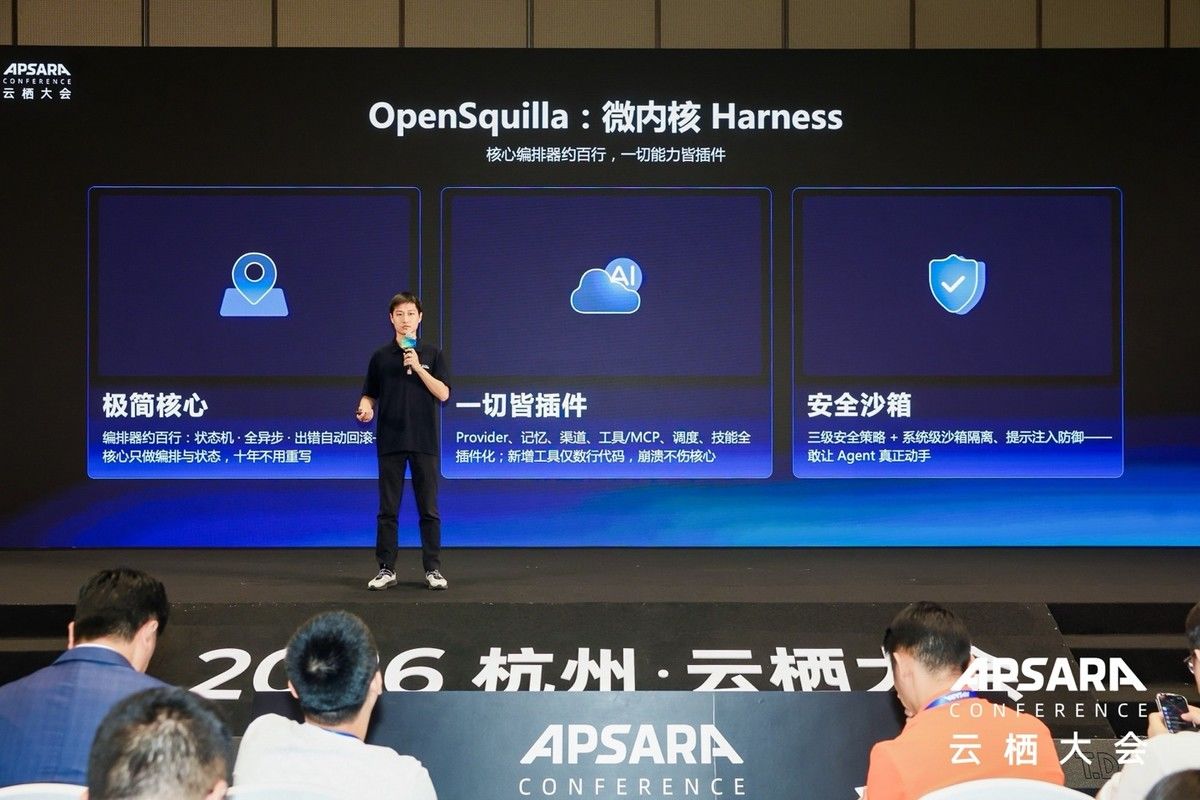
TL;DR - TokenRhythm presented an agent architecture that combines multi-model routing with a feedback loop for improving models from deployment experience. Its OpenSquilla and NeoHorse-1 results suggest this approach can reduce agent costs while preserving quality and turn operational feedback into measurable model gains.
- OpenSquilla reportedly retained 99.96% of a fixed flagship-model baseline’s task quality while cutting costs by 88.9% under a specific evaluation setup.
- In the DRACO deep-research benchmark, a multi-model configuration outscored the strongest single-model baseline in the experiment at roughly one-third the cost.
- The proposed RSI loop connects application requirements, evaluations, targeted optimization, and production validation to support continual agent improvement.
- Post-trained on Qwen3.5, NeoHorse-1 raised macro-average scores from 58.94 to 64.87 for the 4B model and from 65.60 to 69.04 for the 9B model across ten benchmarks.
Sources (1)
基元律动韩凯:从多模型调度到反馈闭环,探索Agent持续进化
Public signals
N/A
TL;DR - TokenRhythm presented an agent architecture that combines multi-model routing with a feedback loop for improving models from deployment experience. Its OpenSquilla and NeoHorse-1 results suggest this approach can reduce agent costs while preserving quality and turn operational feedback into measurable model gains.
- OpenSquilla reportedly retained 99.96% of a fixed flagship-model baseline’s task quality while cutting costs by 88.9% under a specific evaluation setup.
- In the DRACO deep-research benchmark, a multi-model configuration outscored the strongest single-model baseline in the experiment at roughly one-third the cost.
- The proposed RSI loop connects application requirements, evaluations, targeted optimization, and production validation to support continual agent improvement.
- Post-trained on Qwen3.5, NeoHorse-1 raised macro-average scores from 58.94 to 64.87 for the 4B model and from 65.60 to 69.04 for the 9B model across ten benchmarks.