PCIe显卡被低估了!内核补齐+通信重构,DeepSeek推理吞吐翻近7倍
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
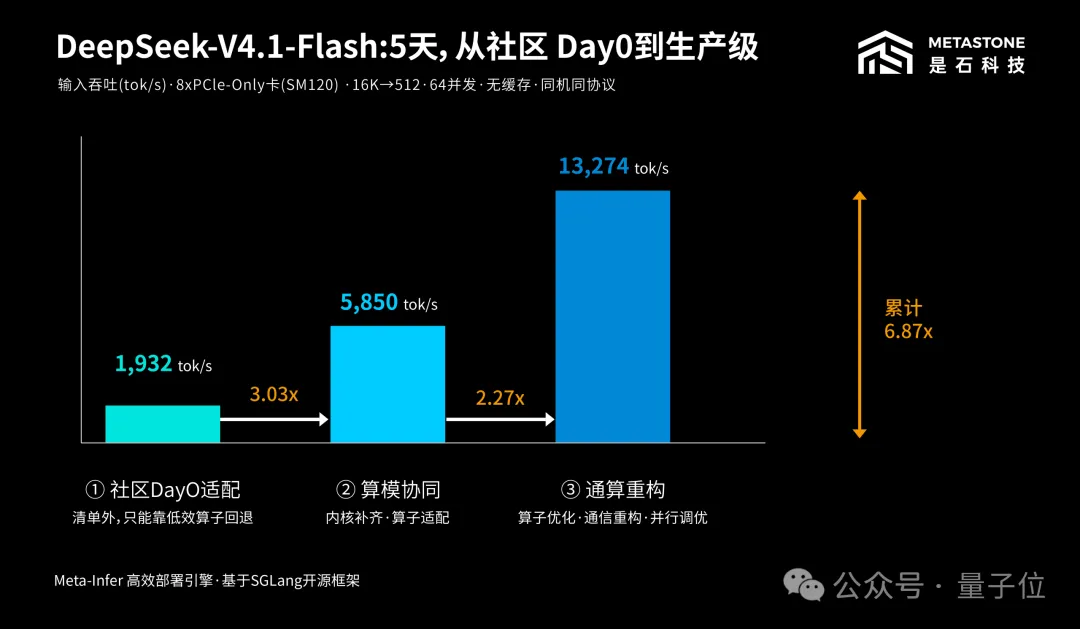
TL;DR - MetaStone says its Meta-Infer engine increased DeepSeek-V4.1-Flash input throughput on eight PCIe-only GPUs from 1,932 to 13,274 tokens/s—a 6.87× gain—through software optimization rather than model or hardware changes. The results suggest lower-cost and non-mainstream accelerators can become substantially more competitive when inference stacks are tuned for their architectures.
- Meta-Infer unlocks optimized kernels, replaces poorly matched implementations, and broadens PCIe communication fast paths; this first stage raised throughput to 5,850 tokens/s.
- Operator fusion, computation-communication overlap, PCIe-specific collectives, and separate Prefill/Decode parallel strategies delivered the remaining gains while supporting contexts up to 1 million tokens.
- Reported improvements also include 1.55× throughput for DeepSeek-V4-Flash and 1.92× for GLM5.3, whose P95 time-to-first-token fell from 141.6 to 46.6 seconds.
- The same approach was applied to video generation and domestic GPUs using sparse attention, cache reuse, platform-specific feature selection, and phase-specific communication modes.
Sources (1)
PCIe显卡被低估了!内核补齐+通信重构,DeepSeek推理吞吐翻近7倍
TL;DR - MetaStone says its Meta-Infer engine increased DeepSeek-V4.1-Flash input throughput on eight PCIe-only GPUs from 1,932 to 13,274 tokens/s—a 6.87× gain—through software optimization rather than model or hardware changes. The results suggest lower-cost and non-mainstream accelerators can become substantially more competitive when inference stacks are tuned for their architectures.
- Meta-Infer unlocks optimized kernels, replaces poorly matched implementations, and broadens PCIe communication fast paths; this first stage raised throughput to 5,850 tokens/s.
- Operator fusion, computation-communication overlap, PCIe-specific collectives, and separate Prefill/Decode parallel strategies delivered the remaining gains while supporting contexts up to 1 million tokens.
- Reported improvements also include 1.55× throughput for DeepSeek-V4-Flash and 1.92× for GLM5.3, whose P95 time-to-first-token fell from 141.6 to 46.6 seconds.
- The same approach was applied to video generation and domestic GPUs using sparse attention, cache reuse, platform-specific feature selection, and phase-specific communication modes.