笔记本跑7000亿参数GLM!无GPU也行? SSD当显存用火爆GitHub
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
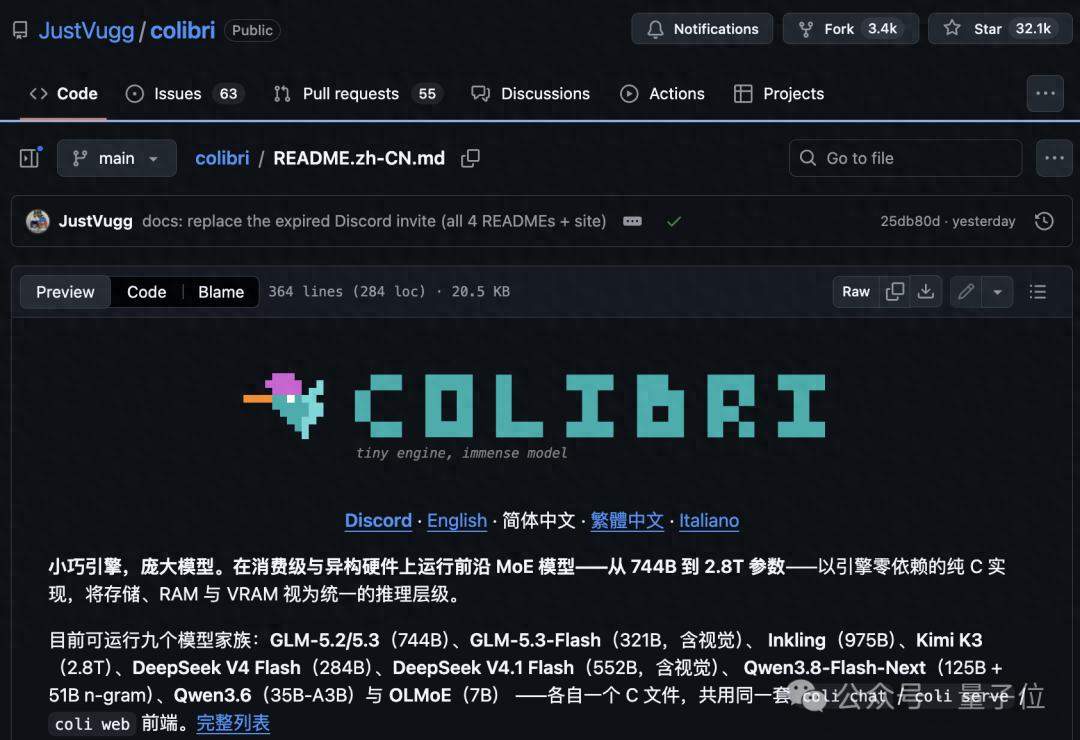
TL;DR - Colibrì is an open-source, dependency-free C inference framework that runs extremely large mixture-of-experts models on consumer computers by dynamically moving weights among NVMe SSD, RAM, and VRAM. This makes models as large as 744B—and reportedly 2.8T parameters—runnable without a GPU, though performance depends heavily on available memory and storage bandwidth.
- For GLM-5.2, roughly 17B dense parameters occupy about 9.9GB of RAM in INT4, while approximately 370GB of routed expert weights remain on SSD and are loaded only when selected.
- Colibrì reduces SSD traffic through LRU caching, expert-frequency tracking, and one-layer-ahead prefetching; the project reports 71.6% predictability for expert routing between adjacent layers.
- Reported GLM-5.2 throughput ranges from 0.05–0.1 tokens/s on a 12-core CPU with 25GB RAM under cold-cache conditions to about 1.8 tokens/s on a 128GB CPU system.
- The framework supports nine model configurations, including a 2.8T-parameter Kimi K3 setup requiring about 1.6TB of storage and at least 32GB RAM, with GPU acceleration optional.
Sources (1)
笔记本跑7000亿参数GLM!无GPU也行? SSD当显存用火爆GitHub
TL;DR - Colibrì is an open-source, dependency-free C inference framework that runs extremely large mixture-of-experts models on consumer computers by dynamically moving weights among NVMe SSD, RAM, and VRAM. This makes models as large as 744B—and reportedly 2.8T parameters—runnable without a GPU, though performance depends heavily on available memory and storage bandwidth.
- For GLM-5.2, roughly 17B dense parameters occupy about 9.9GB of RAM in INT4, while approximately 370GB of routed expert weights remain on SSD and are loaded only when selected.
- Colibrì reduces SSD traffic through LRU caching, expert-frequency tracking, and one-layer-ahead prefetching; the project reports 71.6% predictability for expert routing between adjacent layers.
- Reported GLM-5.2 throughput ranges from 0.05–0.1 tokens/s on a 12-core CPU with 25GB RAM under cold-cache conditions to about 1.8 tokens/s on a 128GB CPU system.
- The framework supports nine model configurations, including a 2.8T-parameter Kimi K3 setup requiring about 1.6TB of storage and at least 32GB RAM, with GPU acceleration optional.