LongHorizon-Harness Advancing Long-Horizon Agents for Real-World Tasks paper…
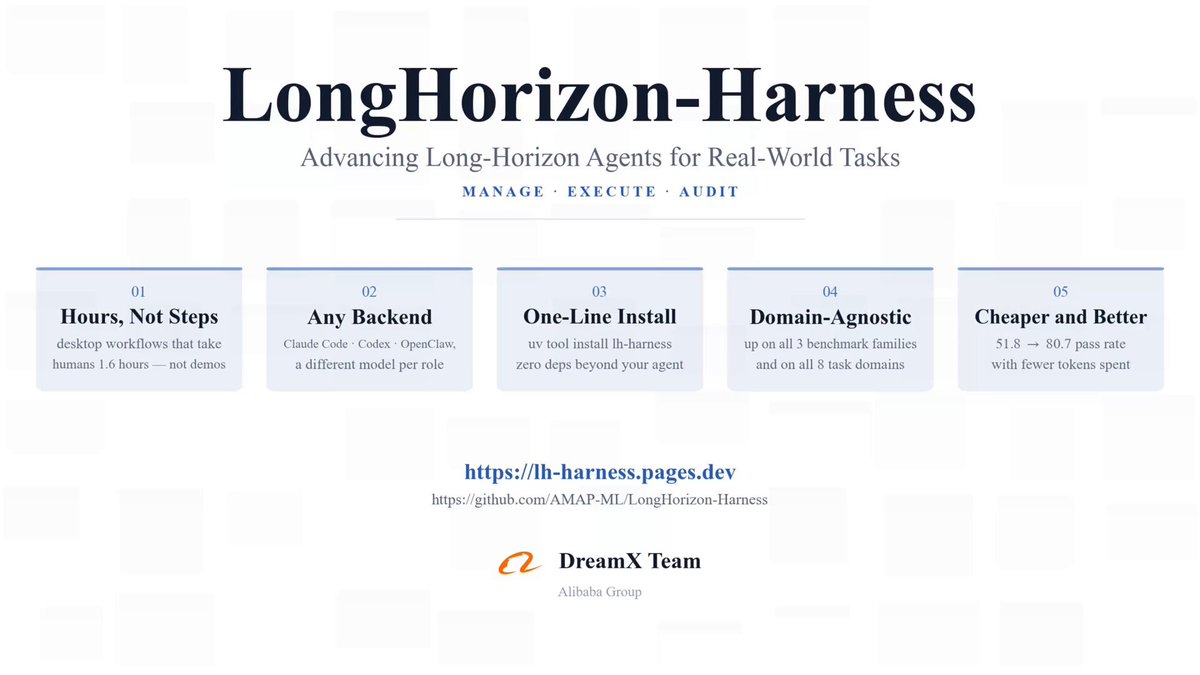
TL;DR - A shared paper titled "LongHorizon-Harness: Advancing Long-Horizon Agents for Real-World Tasks," surfaced via @_akhaliq's Hugging Face papers feed, targeting the persistent weak spot of LLM agents: sustaining coherent, multi-step execution over long task horizons rather than short tool-call bursts. Note: only the title and a link were available, so the points below are inferred from the title, not verified results.
- The name "Harness" signals an evaluation/execution scaffold — an environment plus runner for exercising agents on extended, real-world task trajectories, not a new base model.
- "Long-Horizon" frames the core problem as error accumulation, context/memory management, and goal drift across many sequential tool and environment interactions.
- "Real-World Tasks" implies benchmarks drawn from practical workflows (e.g., software, web, or operational tasks) rather than synthetic puzzle suites, which typically means noisier, partially observable settings and outcome-based grading.
- Accompanied by a video demo; no metrics, model comparisons, or ablations were included in the shared content.