SWE-Bench ProMax Benchmarking Agents on Large-Scale Multilingual Code Refactoring paper…
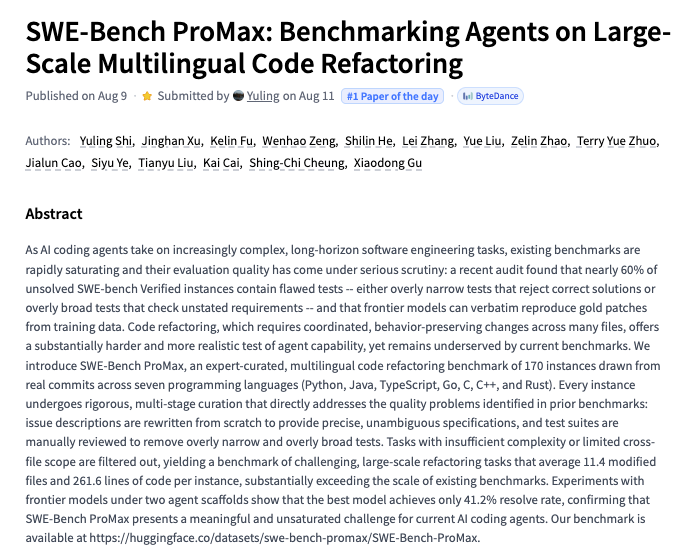
TL;DR - A shared announcement of "SWE-Bench ProMax," a paper introducing a benchmark that evaluates coding agents on large-scale, multilingual code refactoring tasks. It matters because it pushes agent evaluation beyond single-repo, Python-centric bug fixing toward broader, more realistic software maintenance work.
- Positions itself as an extension of the SWE-Bench lineage, which evaluates LLM agents on resolving real repository issues; "ProMax" signals a harder/expanded tier.
- Two stated axes of difficulty: large-scale changes (edits spanning many files/modules rather than small patches) and multilingual coverage (beyond SWE-Bench's original Python focus).
- Targets refactoring rather than bug-fixing, which stresses cross-file reasoning, API/call-site consistency, and behavior-preserving edits — capabilities poorly measured by existing agent benchmarks.
- Content is thin: the item is only a paper title plus a truncated Hugging Face Papers link (arXiv ID 2608.0…), so no methodology, task counts, or model results are available; the above is inferred from the title alone.