星动纪元陈建宇:VLA 非终局,具身大脑已进入世界模型时代 | WRC 2026
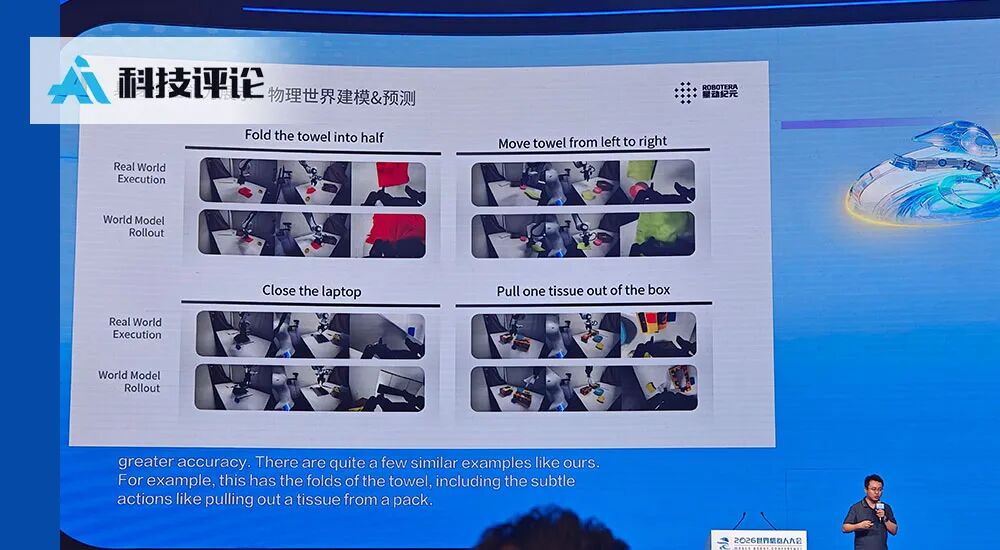
TL;DR - Robot maker Robot Era argues that video-based world-action models—not imitation-centric vision-language-action (VLA) models—could become the core architecture for general-purpose robots. Such models jointly predict actions and future world states, aiming to improve physical reasoning and zero-shot task generalization.
- Its world-action model combines video prediction with action prediction, incorporating robot demonstrations and first-person human interaction data.
- The company reports early zero-shot performance on unseen instructions and environments, plus fine manipulation and transfer across robot embodiments, though the article provides no benchmarks.
- Robot Era couples its models with in-house humanoid hardware, dexterous hands, and real-world feedback to create a data-and-deployment improvement loop.
- Commercial deployments reportedly span logistics and industrial projects in more than ten cities, alongside open hardware, APIs, and development tools.