OpenAI「辣椒芯」干翻英伟达!老黄股价不跌反涨
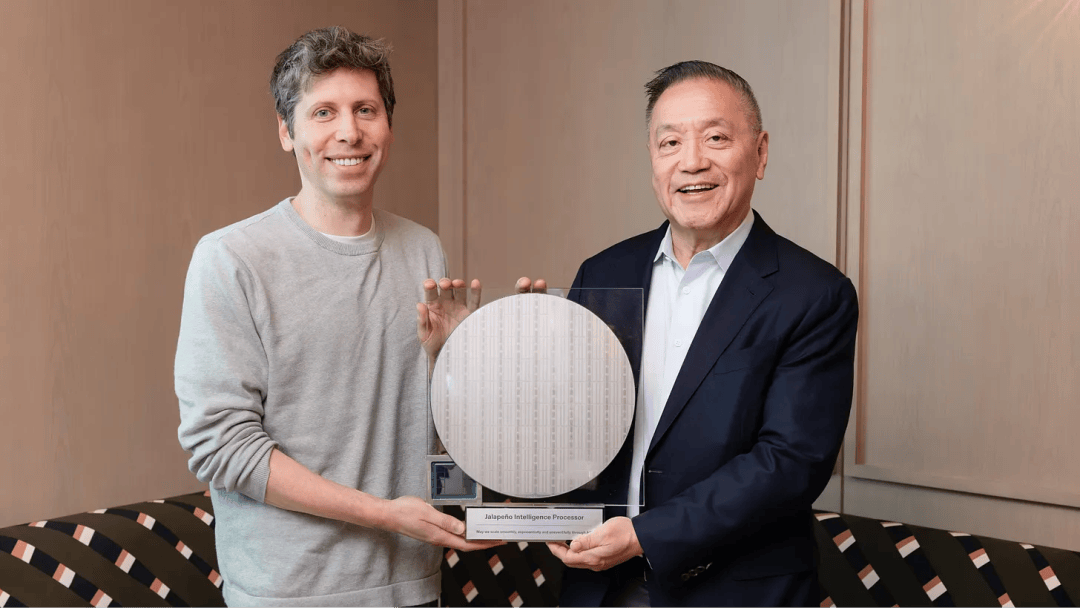
TL;DR - OpenAI unveiled “Jalapeño,” its first custom inference accelerator, which SemiAnalysis observed outperforming Nvidia Blackwell systems on selected single-token prediction benchmarks. The results suggest strong efficiency and latency gains, but are based on engineering samples and limited tests rather than complete production workloads.
- At 700W TDP, Jalapeño reportedly delivered 1.5–1.9× higher inference throughput per kilowatt and 1.7–3.6× lower end-to-end latency than tested GB200/GB300 configurations.
- The benchmark covered GPT-OSS 120B, DeepSeek R1 670B, and Kimi K2.5; it excluded prefill/decode disaggregation, speculative decoding, and the more production-oriented AgentX suite.
- The B0 revision uses TSMC N3P/N3E dies, six HBM4 stacks providing 216GB and 15.4TB/s bandwidth, and is projected to improve performance per watt by about 25%.
- Codex and GPT-Astra assisted chip and kernel optimization, with some AI-generated kernels reportedly running 1.5–1.8× faster than expert-written versions; volume production is planned to ramp during 2027.