🛰️ Daily AI Frontier
51 works · 3 categories · 20 topics · blog 12 journal 10 arxiv 15 wechat 15 generated 2026-08-26 14:47:05 UTC
Top highlights — Research

LLM Agents 9

Representative image for StarHarness: Evolving Harnesses with Stratified Search for Enterprise Environments

StarHarness: Evolving Harnesses with Stratified Search for Enterprise Environments

Rank 91 · Content 100 · Popularity 71

TL;DR - StarHarness evolves environment-specific agent scaffolding—such as prompts, tools, skills, subagents, and loop settings—without changing model weights. It improves enterprise benchmark performance by 20–35 percentage points and generalizes across held-out tasks and model families.

  • Uses stratified task sampling based on baseline failures, with separate search, selection, and held-out evaluation sets.
  • Achieves full-benchmark gains after only 4–12 accepted harness changes per environment.
  • Transfers without re-evolution across GPT and Qwen model families.
  • Improvements stem from repaired interfaces, encoded environment conventions, and operational knowledge that reduces false diagnoses and shortens some trajectories.
Representative image for The Handoff Tax: Continuing Non-Native Trajectories in LLM Agents

The Handoff Tax: Continuing Non-Native Trajectories in LLM Agents

Rank 89 · Content 100 · Popularity 63

TL;DR - This paper identifies a “handoff tax” when one coding-agent model inherits another model’s trajectory. Escalating from a weaker model to a stronger one recovers less than half the quality gap at substantial added cost, while downshifting offers a better cost-quality trade-off.

  • Experiments span Claude and GPT model pairs, varying handoff direction, timing, and inherited context.
  • Transfer interfaces include full trajectories, compacted trajectories, and no trajectory beyond the preserved repository state.
  • Escalation improves when less of the weaker model’s trajectory is retained.
  • Downshifting behaves oppositely: removing the stronger model’s trajectory reduces quality.

SPO++: Stream-Aligned Policy Optimization for Asynchronous Agentic RL

Rank 88 · Content 100 · Popularity 59

TL;DR - SPO++ improves asynchronous reinforcement learning for tool-using agents by aligning advantage normalization with the token-level actor objective and organizing experience by the policy version that generated it. It learns more efficiently than SPO in matched ALFWorld and Math-TIR experiments.

  • Standardizes terminal-outcome advantages under the action-token measure, correcting a mismatch between trajectory-level centering and token-mean optimization.
  • Groups prompt evidence by its generating policy event rather than by learner receipt order.
  • Avoids waiting for sibling rollouts of the same prompt, supporting long, variable-duration agent trajectories.
  • Paired ablations identify action-token-measure normalization as the strongest tested component.

Life-inspired interoceptive artificial intelligence for autonomous and adaptive agents

Rank 84 · Content 90 · Popularity 71

TL;DR - Lee, Oh et al. propose interoception—the biological capacity to sense and respond to internal states—as a framework for developing more autonomous and adaptive AI agents. The work matters as a life-inspired direction for agents that regulate and adjust their own behavior.

  • Draws design principles from how living organisms monitor internal conditions.
  • Frames interoception as a foundation for agent autonomy and adaptation.
  • Proposes a conceptual framework; no specific experimental results are provided in the excerpt.
Representative image for Recursive Experiential-Working Memory Evolution for Long-Horizon Agent Harnesses

Recursive Experiential-Working Memory Evolution for Long-Horizon Agent Harnesses

Rank 84 · Content 90 · Popularity 69

TL;DR - Recuris is a recursive memory architecture that helps long-horizon agents track task progress, select relevant skills, and improve those skills through validation-gated updates. It increased task success across nearly all completed model-benchmark evaluations, with larger gains on longer tasks.

  • Working Memory represents current progress and guides skill retrieval from Experiential Memory instead of relying on the full interaction history.
  • Execution evidence localizes failures to memory components, enabling a fixed Meta-Agent to make bounded, validated updates to Skill Memory.
  • Recuris improved 35 of 37 completed model-benchmark pairs across four benchmarks and ten models.
  • Reported gains include +17.8 points for GPT-5.6 Sol and +15.6 for Claude Opus 5 on tau-bench, with improvements reaching +32.2 points on the longest tasks.
Representative image for AI Agent的下一站:Graph Engineering|一文读懂

AI Agent的下一站:Graph Engineering|一文读懂

Rank 83 · Content 90 · Popularity 68

TL;DR - A multi-institution research survey proposes Graph Engineering as a foundation for next-generation LLM agent systems, explicitly representing tasks, agent coordination, and runtime state as evolving graphs. This could help complex multi-agent systems become more scalable, auditable, and recoverable.

  • Task graphs encode goal decomposition, dependencies, parallel branches, executable workflows, and validation steps.
  • Agent graphs model capabilities, permissions, delegation, communication, resource access, and human oversight.
  • Runtime-state graphs track versioned changes and dependencies to support diagnosis, replay, rollback, and recovery from failures.
  • Open challenges include unified capability graphs, validated self-evolution, graph-native agent operating systems, and privacy-preserving governance.
Representative image for CAFE: Self-Improving Search Agents Need Co-Evolving Feedback

CAFE: Self-Improving Search Agents Need Co-Evolving Feedback

Rank 83 · Content 95 · Popularity 56

TL;DR - CAFE jointly improves an agentic search policy and its feedback critic by training them in alternating, coupled roles. Across seven in-domain and six out-of-domain benchmarks, this approach outperformed evaluated RL-based search agents on average and reduced answer-level hallucinations.

  • A shared-parameter model alternates between acting as the search agent and providing corrective, in-trajectory feedback.
  • Online RL rewards useful feedback requests using a call-versus-skip success gap and reshapes token-level advantages around feedback.
  • Offline preference optimization trains feedback from matched successful and unsuccessful rollout trajectories.
  • Ablations found that improving only the agent or critic eventually plateaued, while alternating updates continued to improve performance.
Representative image for PeakBench: Benchmarking Resource-Aware Tool Invocation in LLM Agents

PeakBench: Benchmarking Resource-Aware Tool Invocation in LLM Agents

Rank 80 · Content 100 · Popularity 34

TL;DR - PeakBench evaluates whether LLM agents can correctly parallelize multi-tool workflows while respecting resource limits. It matters because sound dependency planning alone does not ensure safe, low-latency execution.

  • Provides executable workflows with execution-grounded dependencies and measured resource profiles.
  • Separately evaluates logical dependency planning and physical resource-constrained scheduling.
  • Finds that strong planners can still execute inefficiently or trigger avoidable resource overflows.
  • Shows that exposing resource information can reduce overflows and improve utilization.
Representative image for SkillForge: Evolving Verifiable Skills for Reinforcement Learning Agents

SkillForge: Evolving Verifiable Skills for Reinforcement Learning Agents

Rank 77 · Content 95 · Popularity 34

TL;DR - SkillForge is a reinforcement-learning framework that lets LLM agents accumulate reusable skills while continuously verifying and refining them through environment interaction. It improves over append-only skill banks by maintaining skill quality as agents learn across episodes.

  • Makes skill invocation explicit so RL jointly optimizes environment actions and decisions about when to use skills.
  • Uses interaction evidence to verify and refine stored skills rather than assuming they remain effective.
  • Supports multiple skill-induction pathways, enabling the skill bank to grow while controlling quality.
  • Consistently outperforms SkillRL in experiments on ALFWorld, WebShop, and AppWorld.

Medical/Healthcare AI 9

Right Diagnoses, Decorative Reasoning:A Perturbation Audit of Medical Chain-of-Thought

Rank 80 · Content 100 · Popularity 34

TL;DR - A perturbation audit of 14 LLMs finds that medical chain-of-thought rationales are often disconnected from the models’ diagnoses. This challenges the use of visible reasoning as evidence that a model reached an answer through clinically faithful reasoning.

  • The audit uses 30 clinically motivated operators, including severity reversals, negation flips, demographic swaps, and evidence ablations, across four medical QA benchmarks.
  • On clinically meaningful destructive edits, the panel-wide Chain-Decoupling Rate was 72.9%: models often neither updated the rationale nor changed the answer.
  • Corrupting the chain did not affect accuracy, and removing chain-of-thought prompting did not reduce accuracy.
  • Two board-certified clinicians reviewed 197 perturbed questions and found that 98.5% retained defensible gold answers, supporting the validity of the perturbation analysis.
Representative image for A Multimodal Foundation Model for Longitudinal Patient Representation and Scalable Insight Generation in Oncology

A Multimodal Foundation Model for Longitudinal Patient Representation and Scalable Insight Generation in Oncology

Rank 80 · Content 100 · Popularity 34

TL;DR - oFM is a multimodal foundation model trained on longitudinal records from more than one million oncology patients, integrating clinical history, genomics, transcriptomics, and pathology images. Its frozen patient embeddings substantially improved prognostic and treatment-benefit predictions over expert-curated baseline features.

  • The model encodes daily clinical and molecular episodes, combines them with H&E pathology images, and integrates observations over time into patient-state embeddings.
  • Training used patient-level partitions from a real-world cohort of 1.67 million cancer patients.
  • oFM improved overall-survival AUC from 0.563 to 0.774 and also improved treatment-response and progression-free-survival prediction.
  • Across 11 comparative-treatment cohorts, its embeddings achieved three-fold higher pooled, scale-normalized treatment-benefit AUTOC and improved benefit ranking in 9 cohorts.
Representative image for B-MIM: Biased Masked Image Modeling for Generalizable Segmentation of Fine-Grained Anatomical Structures

B-MIM: Biased Masked Image Modeling for Generalizable Segmentation of Fine-Grained Anatomical Structures

Rank 80 · Content 100 · Popularity 34

TL;DR - B-MIM is a self-supervised pretraining method that reduces global semantic alignment to make 3D CT encoders more sensitive to fine anatomical details. It improves cross-dataset segmentation of intricate structures while requiring only partial parameter updates during downstream training.

  • Modifies the iBOT objective to prioritize local patch reconstruction and high-frequency morphology.
  • Pretrains a 3D Swin Transformer on 9,955 abdominal CT studies curated from 17 public sources.
  • Improves topological fidelity (clDice) for liver vessel segmentation across datasets.
  • Achieves competitive tumor-segmentation Dice scores versus fully fine-tuned baselines while updating fewer parameters.
Representative image for Nature | 是卫士,还是内应?抑癌蛋白Rb的“双面人生”

Nature | 是卫士,还是内应?抑癌蛋白Rb的“双面人生”

Rank 67 · Content 70 · Popularity 60

TL;DR - A Nature study shows that the Rb tumor suppressor has a dual role in HR+ breast cancer: CDK4/6 inhibition activates Rb to suppress cell-cycle genes but also drives estrogen-responsive, pro-proliferative transcription. This mechanism explains both the benefit of combining CDK4/6 inhibitors with anti-estrogen therapy and reduced efficacy in ESR1-mutant tumors.

  • CUT&RUN mapping revealed that activated, hypophosphorylated Rb relocates to promoters and enhancers, joining ER-enriched 3D transcriptional hubs that activate genes such as CCND1.
  • CRISPR disruption of Rb-bound enhancers and RB1 knockout eliminated drug-induced estrogen-response gene activation, supporting a direct regulatory role.
  • Rb interacts with ER and KDM5A, counteracting KDM5A-mediated repression and expanding H3K4me3 across ER target genes.
  • Fulvestrant blocked this proliferative feedback in endocrine-sensitive models; in ESR1-mutant models, degrading mutant ER restored stronger cell-cycle suppression.

The brain struggles to make new neurons in people with depression

Rank 66 · Content 75 · Popularity 46

TL;DR - A high-resolution, wide-coverage map of the human hippocampus examines impaired formation of new neurons in people with depression and highlights possible therapeutic pathways. The provided summary does not specify the mapping methods, quantitative findings, or candidate interventions.

  • Focuses on adult neurogenesis in the hippocampus, a brain region implicated in depression.
  • Reports that new-neuron formation appears impaired in people with depression.
  • Uses detailed hippocampal mapping to identify possible routes for future therapies.
  • Technical and clinical details cannot be determined from the limited content provided.
Representative image for Nat Cell Biol | 宋彦龄团队解析肿瘤囊泡分泌昼夜节律,赋能时辰治疗新策略

Nat Cell Biol | 宋彦龄团队解析肿瘤囊泡分泌昼夜节律,赋能时辰治疗新策略

Rank 64 · Content 70 · Popularity N/A

TL;DR - A Nature Cell Biology study introduces ctEV-CLOCK, a method for time-resolved isolation of circulating tumor-derived extracellular vesicles, and shows that their secretion and tumor-promoting activity follow circadian rhythms. Synchronizing targeted therapies with peak vesicle-protein abundance substantially improved efficacy in mouse tumor models.

  • ctEV-CLOCK combines metabolic glycan labeling with tumor-marker-targeted aptamer click chemistry to isolate newly secreted ctEVs at 12-hour resolution.
  • Across several mouse tumor models, ctEV abundance and pro-migratory, pro-invasive activity peaked during the nocturnal active phase; host-clock disruption largely abolished this rhythm.
  • Nighttime ctEVs were enriched in actionable proteins, including HPSE and CD47, linking vesicle rhythms to angiogenesis, invasion, and immune evasion.
  • Administering an HPSE inhibitor or anti-CD47 antibody near the corresponding ctEV protein peaks improved antitumor responses; suppressing extracellular-vesicle release eliminated the time-of-day advantage.

Asthma in some boys stops at puberty: mouse results hint at why

Rank 59 · Content 65 · Popularity 46

TL;DR - A mouse study offers a possible explanation for why asthma resolves in some boys during puberty, pointing to an effect of male hormones on lung nerve endings. The limited summary does not specify the mechanism or whether it has been confirmed in humans.

  • The research examines puberty-associated asthma changes using mice.
  • Results implicate male hormones in altering nerve endings in the lungs.
  • The findings could help explain sex- and age-related differences in asthma.
  • Translational relevance to human asthma cannot be determined from the provided content.
Representative image for Protein & Cell | 解锁运动员骨骼肌“优质脂滴”之谜:锚定线粒体的脂滴--“油和发动机”

Protein & Cell | 解锁运动员骨骼肌“优质脂滴”之谜:锚定线粒体的脂滴--“油和发动机”

Rank 58 · Content 65 · Popularity 42

TL;DR - A Protein & Cell study established a method to isolate human skeletal-muscle lipid droplets and mapped their proteome, revealing features that may explain why endurance athletes remain insulin-sensitive despite high muscular lipid stores. The findings offer molecular targets for studying diabetes and other metabolic diseases.

  • PLIN4, rather than PLIN2 or PLIN5, was the most enriched perilipin coating protein on athletes’ skeletal-muscle lipid droplets.
  • The study identified lipid droplet–anchored mitochondria enriched in respiratory-chain complex IV subunits COX6B1 and COX7C, suggesting enhanced fatty-acid oxidation.
  • TPD52L2 was newly identified on lipid droplets; knockdown reduced triglycerides and droplet size and number, while overexpression promoted cell proliferation.
  • Researchers plan to compare these “healthy” athlete lipid droplets with those from people with diabetes to investigate insulin resistance.

The baffling science of SSRIs: how do they really work?

Rank 56 · Content 60 · Popularity 46

TL;DR - A Nature article examines uncertainty around how selective serotonin reuptake inhibitors (SSRIs) work and the controversy over antidepressant withdrawal. The provided excerpt is too limited to establish the article’s conclusions or supporting evidence.

  • Focuses on the still-debated mechanisms behind widely used SSRI antidepressants.
  • Highlights criticism concerning withdrawal and the difficulty of discontinuing treatment.
  • Questions comparisons between SSRI withdrawal and heroin addiction without resolving their validity in the supplied text.

Bioinformatics AI 3

A knowledge-driven framework for predicting single-cell responses for unprofiled drugs

Rank 84 · Content 100 · Popularity 46

TL;DR - Feng et al. introduce MAP, a knowledge-driven AI framework for predicting single-cell responses to previously unprofiled drugs. Integrating biological mechanism knowledge improves generalization to untested compounds and supports virtual screening for cancer drug candidates.

  • Predicts cellular responses to chemical perturbations at single-cell resolution.
  • Incorporates biological mechanism knowledge rather than relying solely on observed perturbation data.
  • Targets out-of-distribution generalization to drugs not profiled during training.
  • Demonstrates potential for prioritizing cancer drug candidates through virtual screening.
Representative image for 机器学习重塑疾病生物标志物的发现;Bonsai用树状地图重绘单细胞高维世界;RNA速率分析方向校正;单细胞让AML风险分层和用药决策更精准等

机器学习重塑疾病生物标志物的发现;Bonsai用树状地图重绘单细胞高维世界;RNA速率分析方向校正;单细胞让AML风险分层和用药决策更精准等

Rank 75 · Content 80 · Popularity 64

TL;DR - This research roundup covers new computational and single-cell methods for biomarker discovery, high-dimensional visualization, RNA-velocity quantification, and disease profiling. Together, they improve the reliability and clinical relevance of analyses across complex cellular datasets.

  • Machine-learning models can identify multigene disease biomarkers from scRNA-seq data, but require patient-level validation, biological interpretation, and standardized workflows.
  • Bonsai represents high-dimensional single-cell relationships as trees, preserving distances and developmental hierarchies more faithfully than conventional 2D embeddings such as UMAP or t-SNE.
  • The tidesurf tool corrects strand-orientation errors in 10x 5′ RNA-velocity analysis that can misassign reads and reverse inferred cell-state transitions.
  • Large multi-omic atlases—including a four-million-cell pancreas map—reveal disease-associated cell states, regulatory programs, and potential cellular plasticity relevant to diabetes, regeneration, and cancer.
Representative image for Adv Sci | 顾臻/肖庆全/魏迎辉/李国玲团队合作开发紧凑型Cas9d碱基编辑器

Adv Sci | 顾臻/肖庆全/魏迎辉/李国玲团队合作开发紧凑型Cas9d碱基编辑器

Rank 64 · Content 75 · Popularity 37

TL;DR - Researchers used AlphaFold3-guided engineering to create Cas9d Ultra, a compact and highly specific genome-editing system suitable for single-AAV delivery. Its derived base editors achieved in vivo Pcsk9 editing and lowered LDL cholesterol in mice, supporting potential single-vector gene therapies.

  • Cas9d Ultra combines a shortened, stabilized gRNA scaffold with protein mutations that strengthen interactions with gRNA and target DNA.
  • The engineered system exceeded 60% cutting efficiency in mammalian cells—a 3.1-fold improvement over wild-type Cas9d—and showed high specificity in GUIDE-seq testing.
  • Cas9d-derived adenine and cytosine base editors enabled embryo editing, including Tyr knockout and generation of albino mice.
  • Single-AAV delivery produced 3.5%–11.9% liver editing with 9dABE and an average 15.7% with 9dCBE, reaching 28.9% and significantly reducing serum LDL-C.

LLMs & Foundation Models 2

Effective Learning Rate Governs Loss Dynamics in Language Model Pretraining

Rank 89 · Content 100 · Popularity 64

TL;DR - This paper finds that language-model pretraining loss dynamics are governed mainly by the effective learning rate (ELR), defined as the learning rate relative to parameter norm. Using ELR as a shared coordinate could make scaling laws and training schedules more transferable across optimization and norm-control methods.

  • Matching ELR produces nearly identical loss trajectories despite substantially different raw learning rates and parameter norms.
  • The effect holds across optimizers, architectures, datasets, and model scales, with typical mean collapse errors of a few × 10^-3.
  • Normalization design and the timescale of learning-rate and norm variation determine how precisely trajectories collapse.
  • ELR explains how weight decay and Hyperball shape loss dynamics and enables a fitted scaling law to transfer across norm-control methods, including delayed acceleration.
Representative image for On-policy Distillation with Verifiable Reward

On-policy Distillation with Verifiable Reward

Rank 83 · Content 90 · Popularity 67

TL;DR - OPDVR combines on-policy distillation’s dense token-level guidance with verifiable task-level rewards for LLM post-training, without introducing new hyperparameters. It aims to preserve teacher guidance while preventing incorrect trajectories from receiving positively aligned distillation signals.

  • Reformulates sampled-token distillation rewards according to trajectory correctness.
  • Uses ReLU gating so correct trajectories receive non-negative rewards and incorrect ones receive non-positive rewards.
  • Converts sampled-token distillation into an RLVR-compatible objective that can be used with policy-gradient methods such as GRPO.
  • Consistently outperforms standard on-policy distillation across six reasoning benchmarks.

Multimodal & Generative 2

LAION-BVD: A 10-Million-Hour Open Video Dataset for Multimodal Pre-training

Rank 86 · Content 95 · Popularity 65

TL;DR - LAION-BVD is an open multimodal pre-training dataset comprising 80 million downloaded videos totaling 10 million hours, sourced from 1.3 billion CommonCrawl-discovered URLs. It substantially expands publicly accessible data for training video, audio, and image models.

  • Content-aware scene detection produces clips with synthetically generated video and audio captions.
  • Models trained on the data show competitive video-text and audio-text benchmark performance, improving consistently with training and model scale.
  • Scene-changing video frames provide image-text data with a different visual distribution from conventional web-image corpora.
  • Models trained on the extracted frames achieve strong image-text retrieval performance.
Representative image for 仅 0.787M 参数!哈工深&清华等提出 TTTIR,刷新图像恢复 12 项 SOTA

仅 0.787M 参数!哈工深&清华等提出 TTTIR,刷新图像恢复 12 项 SOTA

Rank 62 · Content 70 · Popularity 42

TL;DR - TTTIR reframes image restoration as test-time state evolution, dynamically adapting lightweight operators to each degraded image. With 0.787M parameters, it reports state-of-the-art results across 12 low-light enhancement, deraining, raindrop removal, and dehazing benchmarks.

  • A progressive state sequence generator builds coarse-to-fine restoration targets by combining spatial features with wavelet-based frequency states.
  • A state transition evolution module performs a single-step fast-weight update during inference, creating an instance-specific restoration operator.
  • On cross-dataset LOL-v2-Real evaluation, TTTIR reaches 30.78 dB PSNR and 0.9070 SSIM after training only on LOL-v1.
  • Its depthwise-convolution inner loop keeps memory and latency growth roughly linear with image resolution; the implementation is open source.

Efficiency & Systems 1

Representative image for IJCAI 2026 专访:动作指挥计算,VLA 加速不降准 | GAIR Paper 125

IJCAI 2026 专访:动作指挥计算,VLA 加速不降准 | GAIR Paper 125

Rank 77 · Content 85 · Popularity 59

TL;DR - The IJCAI 2026 paper introduces AC²-VLA, an action-context-aware framework that accelerates vision-language-action models by dynamically routing computation based on robot action state. On the SIMPLER benchmark, it reduced FLOPs to 29.4% of the CogACT baseline and achieved 1.79× faster inference without lowering task success.

  • A unified learned router coordinates cognition-cache reuse, visual-token pruning, and Transformer-layer skipping according to action context rather than visual complexity alone.
  • Self-distillation trains the sparse model to match the dense model’s actions and internal features, avoiding reliance on sparse task-success signals.
  • AC²-VLA averaged 76.8% success on four Google Robot Visual Matching tasks, compared with 74.8% for dense CogACT.
  • Cache reuse can improve temporal consistency by suppressing frame-to-frame visual noise, though routing, memory movement, and cache lookup overhead limit realized speedups relative to FLOP reductions.

3D Reconstruction 1

Representative image for 顶刊IJCV 2026!TEPR:热边缘提示引导的多视图 3D 重建几何学习

顶刊IJCV 2026!TEPR:热边缘提示引导的多视图 3D 重建几何学习

Rank 62 · Content 70 · Popularity 42

TL;DR - The IJCV paper introduces TEPR, an edge-prompted geometry-learning framework for multi-view 3D reconstruction from thermal imagery. It improves reconstruction in darkness, smoke, and low-light environments where RGB methods struggle and thermal images lack reliable texture.

  • TEPR combines thermal appearance with learned edge prompts, modality-adaptive layers, and top-k sparse attention to improve cross-view matching and suppress noisy associations.
  • Edge-enhanced prediction uses global multimodal features for camera parameters and dense edge features for depth boundaries, while hierarchical depth alignment enforces local-to-multiview geometric consistency.
  • The authors built TI-FRD with 38,840 thermal frames across 30 scenes, including daytime, nighttime, and smoke sequences with multimodal sensor data and ground truth.
  • Against VGGT on TI-FRD, TEPR reduced average reconstruction accuracy and completeness errors by about 38% and 33%, respectively, and trajectory error by about 44%, while running at 19.5 FPS.

AI Epistemology 1

The epistemic debt of generative AI

Rank 70 · Content 80 · Popularity 46

TL;DR - This Nature Machine Intelligence article introduces “epistemic debt”: the widening gap between AI-assisted claims authors present and what they personally understand and can defend. The concept matters because downstream work can compound this hidden deficit.

  • Generative AI can enable authors to complete cognitive tasks without deeply understanding the generated output.
  • Epistemic debt arises when presented work exceeds an author’s ability to explain or defend it.
  • Building further conclusions on insufficiently understood outputs can increase the debt over time.
  • The article highlights the importance of investing effort in critically understanding AI-generated material.

DNA Repair 1

Representative image for Mol Cell | 薛毅博等揭示DDIAS介导有丝分裂期单链DNA的修复

Mol Cell | 薛毅博等揭示DDIAS介导有丝分裂期单链DNA的修复

Rank 62 · Content 65 · Popularity 56

TL;DR - A Molecular Cell study identifies DDIAS as the ssDNA-binding effector of the CIP2A–TOPBP1 complex, revealing a DNA synthesis-dependent pathway that repairs single-stranded DNA during mitosis. This mechanism helps preserve chromosome integrity and influences PARP-inhibitor sensitivity in BRCA1/2-deficient cells.

  • DDIAS binds phosphorylated TOPBP1 through its BRCT7/8 domains and is recruited to mitotic DNA-damage sites.
  • DDIAS’s ssDNA-binding activity is required for CIP2A–TOPBP1 function and mitotic genome stability.
  • ssDNA accumulated in BRCA1/2-deficient cells during G2—especially after PARP inhibition—is largely removed by prometaphase through a DDIAS- and DNA synthesis-dependent process.
  • The findings establish the CIP2A–TOPBP1–DDIAS axis as a mitotic ssDNA-repair system distinct from canonical DNA-damage responses.

Graph Machine Learning 1

Representative image for WWW 2026 | 南开×北航提出UniGOOD,首次统一图分布外泛化与检测

WWW 2026 | 南开×北航提出UniGOOD,首次统一图分布外泛化与检测

Rank 62 · Content 70 · Popularity 42

TL;DR - UniGOOD is a unified framework for graph out-of-distribution generalization and detection under simultaneous covariate and semantic shifts. It matters because existing graph-learning methods typically address these two real-world distribution shifts separately.

  • UniGOOD jointly optimizes a variational invariant-subgraph generator, cross-subgraph spectral contrastive learning, and a three-population invariance regularizer.
  • Its contrastive objective clusters positive pairs to support generalization while separating negative pairs to improve semantic-shift detection.
  • The framework uses invariant representations for label prediction and KNN distance for parameter-free out-of-distribution detection.
  • It achieved the best reported results across the evaluated synthetic and real-world datasets, including a 9.53% relative AUROC gain on GD-Tox21-SIDER and a 9.21% relative FPR reduction on GD-HIV-ZINC.

LLM Evaluation 1

A Judge Should Know What Changed:Construct Validity for LLM-as-a-Judge Evaluation

Rank 80 · Content 100 · Popularity 34

TL;DR - This paper introduces a two-dimensional construct-validity framework for LLM judges, measuring both invariance to irrelevant edits and sensitivity to meaningful ones. Across seven judges, high invariance coexisted with poor sensitivity, showing that agreement and robustness alone can overstate evaluator quality.

  • The framework separates invariance (S) under construct-preserving edits from sensitivity (R) under minimal construct-changing edits; the two are independent and cannot be faithfully collapsed into one score.
  • At matched invariance of at least 0.90, judges averaged S = 0.945 but only R = 0.319.
  • Judges were more sensitive to scope changes than strength changes: R_scope = 0.383 versus R_strength = 0.262, consistently across all seven judges.
  • Surface-only predictors reproduced 55%–67% of labels in five public datasets, including 67.4% of MT-Bench human votes, indicating potential validation-set artifacts.

Nuclear Energy 1

Five highlights from nuclear-power research

Rank 52 · Content 55 · Popularity 46

TL;DR - Nature highlights five recent nuclear-power research developments, spanning advanced materials, cancer-risk analysis, and related topics. The provided excerpt does not include the studies’ specific findings.

  • The item is a research roundup rather than a single study.
  • Advanced materials for nuclear-power applications are among the featured areas.
  • Cancer-risk analysis related to nuclear power is also covered.
  • Detailed methods, results, and implications cannot be determined from the supplied content.

Research Integrity 1

More than 18,000 questionable images found in antibody catalogues of 15 companies

Rank 70 · Content 70 · Popularity 69

TL;DR - A science sleuth reports finding more than 18,000 questionable images in commercial antibody catalogues from 15 companies. The findings raise concerns about antibody reliability and the reproducibility of research that depends on these products.

  • The investigation spans antibody catalogues from 15 companies.
  • More than 18,000 catalogue images were flagged as questionable.
  • Unreliable antibody documentation could undermine experimental validity and reproducibility.
  • The provided excerpt does not specify how the images were assessed or how many antibodies were affected.

Robotic World Models 1

Representative image for Do Robotic World Models Really Follow Actions? Diagnosing and Aligning Action-Conditioned Generation for Policy Learning

Do Robotic World Models Really Follow Actions? Diagnosing and Aligning Action-Conditioned Generation for Policy Learning

Rank 82 · Content 100 · Popularity 40

TL;DR - WorldEcho reveals that robotic world models often fail to follow valid off-expert actions, limiting their reliability as policy-learning simulators. The proposed WorldSync training framework improves action-conditioned generation and supports more successful iterative policy improvement.

  • WorldEcho evaluates action following beyond expert demonstrations using visual integrity and SE(3) trajectory alignment.
  • Existing models handle expert actions reasonably but may ignore diverse off-expert commands or generate visually invalid rollouts.
  • WorldSync targets distributional coverage, grounding video representations in robot dynamics, and alignment of predicted intervention effects with real futures.
  • Experiments on RoboTwin and real robots show improved diagnostic metrics and higher policy success rates.
Top highlights — Industry & News

LLM Agents 2

Representative image for Agent 走向具身世界:从语言智能到机器人「大脑指挥官」

Agent 走向具身世界:从语言智能到机器人「大脑指挥官」 🔗 2 sources

Rank 80 · Content 95 · Popularity 45

TL;DR — 这些来源共同展示了 Agent 从语言智能走向现实执行系统的趋势:通过任务分解、上下文理解、工具或策略调度与反馈闭环,Agent 正成为机器人和企业工作流的“指挥中枢”。RoboHarness 聚焦异构机器人策略的协同,Doubao Work 则聚焦飞书组织上下文中的自主办公。

  • 华为诺亚方舟实验室的 RoboHarness 使用编码 Agent 编排 VLA、世界-动作模型、强化学习及任务与运动规划等异构策略,无需重新训练或修改底层策略即可执行零样本、长时程机器人任务。
  • RoboHarness 根据场景量化信号、执行历史和在线反馈拆解任务并动态路由子任务;其 Memory Bridge 会检索成功轨迹,规划可靠的策略交接状态。移除该模块后,完整任务成功率从 86.0% 降至 60.4%。
  • 字节跳动的 Doubao Work 可自主拆解办公任务,并操作文件、浏览器、云电脑和内容生成工具,产出分析、仪表盘、图片、视频及网页等结果。
  • Doubao Work 通过飞书账号继承组织身份与权限,可在授权范围内调用聊天、文档、会议、任务、审批和多维表格,并将讨论或业务数据转化为可协作、可回流工作流的成果。
  • 两者都强调可靠执行:RoboHarness 通过历史轨迹与状态转换降低机器人策略交接风险;Doubao Work 则保留采购信息的不确定性,将无法核实的价格、库存和交期标记为估算或待询价。

注: 两个来源实际强调的是不同系统——雷峰网聚焦机器人策略编排,量子位聚焦企业办公 Agent;它们的共同点是以 Agent 作为复杂执行环境中的上层协调者。

Representative image for 独家丨王云鹤创业估值数亿美元,押注多模型 Harness和 Agent-Native Model

独家丨王云鹤创业估值数亿美元,押注多模型 Harness和 Agent-Native Model

Rank 64 · Content 70 · Popularity N/A

TL;DR - AI infrastructure startup TokenRhythm has raised tens of millions of dollars to develop a Routing Harness that dynamically selects and coordinates models for agent workflows. The company aims to use real-world routing data and feedback to advance toward agent-native models.

  • The Routing Harness optimizes model selection and switching by task stage, capability, price, and cost constraints.
  • Its open-source agent OpenSquilla has surpassed 6,600 GitHub stars and integrates the routing technology for lower-cost multi-model collaboration.
  • TokenRhythm reports that its domestic multi-model system beat “Fable 5” on the DRACO research benchmark at one-third the cost.
  • Its OpenAI- and Claude-compatible aggregation API reportedly has 54,000 users and processes more than 500 billion tokens daily.

Bioinformatics AI 1

Representative image for 从战略投资到联合研发:英矽智能携手元码智药前瞻布局下一代 mRNA 肿瘤疫苗

从战略投资到联合研发:英矽智能携手元码智药前瞻布局下一代 mRNA 肿瘤疫苗

Rank 68 · Content 75 · Popularity N/A

TL;DR - Insilico Medicine and Byterna Therapeutics have partnered to develop an AI-native platform for personalized circular-mRNA cancer vaccines. The collaboration aims to integrate computational design, targeted delivery, automated experimentation, and manufacturing into a closed-loop development process.

  • Insilico’s Pharma.AI will support neoantigen identification, immunogenicity prediction, mRNA sequence design, and multi-objective optimization.
  • Byterna will contribute circular-mRNA engineering, chemical modification, targeted lipid nanoparticle delivery, and CMC development capabilities.
  • The planned workflow connects patient omics data, AI design, automated synthesis, high-throughput validation, quality analysis, and iterative model updates.
  • Circular mRNA may offer greater stability and longer-lasting expression than linear mRNA, but the article notes that its technical and clinical advantages still require systematic experimental and clinical validation.

LLMs & Foundation Models 1

Training and Finetuning Multi-Vector Embedding Models with Sentence Transformers

Rank 68 · Content 75 · Popularity N/A

TL;DR - Hugging Face presents guidance for training and fine-tuning multi-vector embedding models with Sentence Transformers. Because only the title is provided, specific methods, benchmarks, and results cannot be verified.

  • Multi-vector encoders represent each input with multiple embeddings rather than a single pooled vector.
  • The material appears focused on practical model training and fine-tuning within the Sentence Transformers ecosystem.
  • No supported claims can be made about datasets, loss functions, retrieval quality, or efficiency gains from the supplied content.

Efficiency & Systems 6

Representative image for 英伟达Vera Rubin的Agent吞吐暴涨最高提升30倍,却不只靠GPU | Hot Chips 2026

英伟达Vera Rubin的Agent吞吐暴涨最高提升30倍,却不只靠GPU | Hot Chips 2026

Rank 82 · Content 95 · Popularity N/A

TL;DR - Nvidia says its Vera Rubin NVL72 platform delivers up to 30× higher agent-workload throughput per megawatt than GB300 NVL72 by optimizing the entire heterogeneous inference stack, not just the GPU. The design divides long-context processing, low-latency decoding, tool execution, and networking among specialized components.

  • The preliminary, SemiAnalysis-pending AgentX benchmark used realistic multi-turn traces with median input contexts above 140,000 tokens and measured DeepSeek V4-Pro at 160 tokens per second per user.
  • Rubin GPUs handle large-scale model computation, while Groq 3 LPX accelerators target low-latency token generation through prefill/decode partitioning, attention/FFN splitting, or speculative decoding.
  • Vera CPUs handle orchestration, code execution, data processing, and other work between model calls, extending optimization beyond inference kernels.
  • Spectrum-X, BlueField-4, and DOCA address infrastructure traffic, cluster scaling, and resilience as tool, storage, and data access increasingly affect end-to-end agent performance.
Representative image for OpenAI「辣椒芯」干翻英伟达!老黄股价不跌反涨

OpenAI「辣椒芯」干翻英伟达!老黄股价不跌反涨

Rank 78 · Content 90 · Popularity N/A

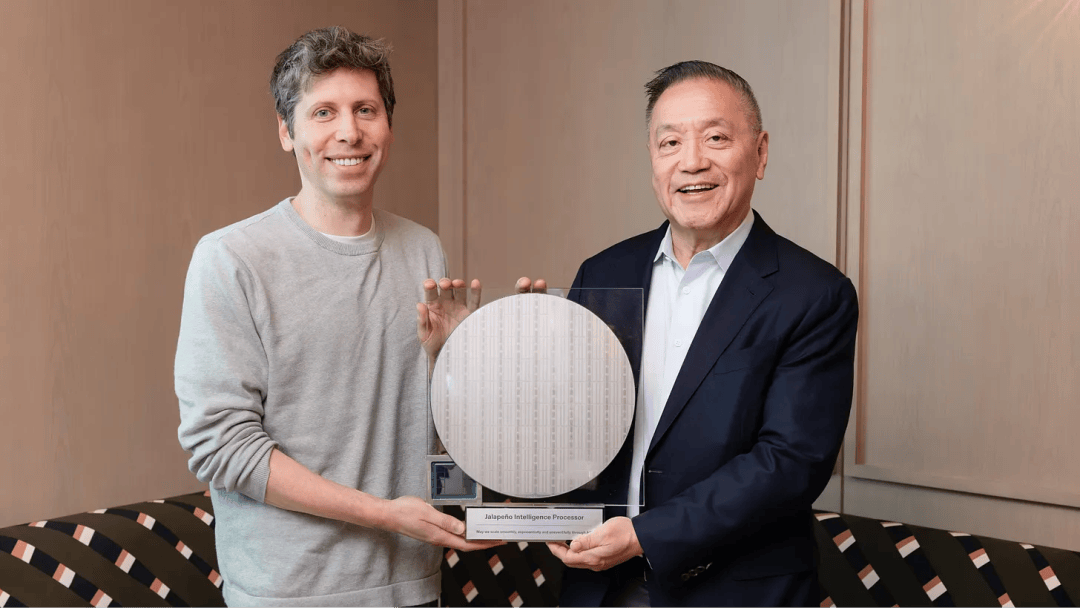
TL;DR - OpenAI unveiled “Jalapeño,” its first custom inference accelerator, which SemiAnalysis observed outperforming Nvidia Blackwell systems on selected single-token prediction benchmarks. The results suggest strong efficiency and latency gains, but are based on engineering samples and limited tests rather than complete production workloads.

  • At 700W TDP, Jalapeño reportedly delivered 1.5–1.9× higher inference throughput per kilowatt and 1.7–3.6× lower end-to-end latency than tested GB200/GB300 configurations.
  • The benchmark covered GPT-OSS 120B, DeepSeek R1 670B, and Kimi K2.5; it excluded prefill/decode disaggregation, speculative decoding, and the more production-oriented AgentX suite.
  • The B0 revision uses TSMC N3P/N3E dies, six HBM4 stacks providing 216GB and 15.4TB/s bandwidth, and is projected to improve performance per watt by about 25%.
  • Codex and GPT-Astra assisted chip and kernel optimization, with some AI-generated kernels reportedly running 1.5–1.8× faster than expert-written versions; volume production is planned to ramp during 2027.

Jalapeño’s first results show industry-leading speed and efficiency in AI inference

Rank 78 · Content 90 · Popularity N/A

TL;DR - OpenAI says Jalapeño, its custom AI inference chip, delivers industry-leading speed and power efficiency for modern models. The provided excerpt does not include benchmarks or detailed specifications supporting the claim.

  • Designed specifically for AI inference workloads.
  • Targets higher throughput and lower latency.
  • Aims to reduce inference power consumption.
  • No quantitative results, model comparisons, or hardware details are provided.
Representative image for 一台GPU用了三年,为什么租金反而更贵了?

一台GPU用了三年,为什么租金反而更贵了?

Rank 75 · Content 85 · Popularity N/A

TL;DR - Older GPUs such as Nvidia H100s can command higher rental prices years after deployment because AI compute value depends on cluster integration, utilization, and sustained demand—not chip age alone. This makes GPU cloud infrastructure a vertically integrated systems business rather than a standardized hardware commodity.

  • Multi-GPU performance depends heavily on high-speed interconnects, network topology, storage, memory, and orchestration; identical GPU counts can therefore deliver different effective compute.
  • Product-generation cycles, accounting depreciation, and revenue-producing economic life are distinct, allowing older GPUs to remain valuable as long as workloads and demand persist.
  • Low utilization sharply raises unit costs because equipment continues depreciating while idle; at 50% utilization, each active GPU-hour bears roughly twice the depreciation cost.
  • Scheduling software that jointly allocates compute, storage, and networking is crucial for converting large GPU clusters into reliable, on-demand training and inference capacity.
Representative image for 800亿港元!阿里宣布为AI再融资,传已超额认购

800亿港元!阿里宣布为AI再融资,传已超额认购

Rank 64 · Content 70 · Popularity N/A

TL;DR - Alibaba plans to raise about HK$80 billion ($10.2 billion) through a share placement and invest all net proceeds in full-stack AI capabilities. The financing underscores how AI competition is shifting toward capital-intensive chips, data centers, cloud infrastructure, and model deployment.

  • The funds will target AI chips, infrastructure, and the development and deployment of models such as Qwen.
  • Alibaba’s quarterly capital expenditure reached RMB 67.68 billion, up 75% year over year, as it advances a separate three-year RMB 380 billion cloud and AI infrastructure plan.
  • AI cloud and computing-service revenue reached RMB 48.44 billion, while AI-related product revenue recorded its 12th consecutive quarter of triple-digit year-over-year growth.
  • Strong demand reportedly produced an oversubscribed placement, including interest from sovereign wealth funds and other international investors.
Representative image for 为什么手机内存进入英伟达机柜后,贵过HBM?

为什么手机内存进入英伟达机柜后,贵过HBM?

Rank 61 · Content 65 · Popularity N/A

TL;DR - Nvidia’s adoption of modular LPDDR5X SOCAMM memory for Vera Rubin systems promises high bandwidth, large capacity, and lower power, but surging AI-server demand is making it scarce and potentially costlier per rack than HBM. Supply constraints could force Nvidia to halve planned CPU-memory configurations.

  • SOCAMM2 delivers over 2.5× the bandwidth of comparable RDIMMs while using roughly one-third the space and power, according to Micron estimates.
  • A projected Kyber rack pairs 216TB of LPDDR5X with 124.4TB of HBM4E; despite LPDDR5X’s lower unit price, its larger capacity raises estimated rack cost to $2.8 million versus $2.5 million for HBM.
  • TrendForce estimates Nvidia may secure only about 60% of its required LPDRAM supply, potentially reducing Vera CPU memory from 1.5TB to 768GB.
  • SOCAMM pricing is projected to rise from about $8/GB in early 2026 to more than $13/GB by year-end, with shortages possibly lasting into 2027.

AI Text Detection 1

AI-detection tools have made huge leaps forward — how good are they?

Rank 63 · Content 70 · Popularity 46

TL;DR - Scientists and publishers are evaluating a new generation of tools for detecting AI-written text. The reported accuracy improvements could affect research integrity and publishing, but the provided excerpt does not include performance figures or validation details.

  • The tools are designed to identify text generated by AI systems.
  • Developers claim substantial gains in detection accuracy.
  • Scientific and publishing organizations are testing the software.
  • Evidence about benchmarks, false positives, and robustness is not provided in the excerpt.

Embodied AI 2

Representative image for 硅谷今日最热具身模型!不用后训练,看一遍就学会

硅谷今日最热具身模型!不用后训练,看一遍就学会

Rank 75 · Content 85 · Popularity N/A

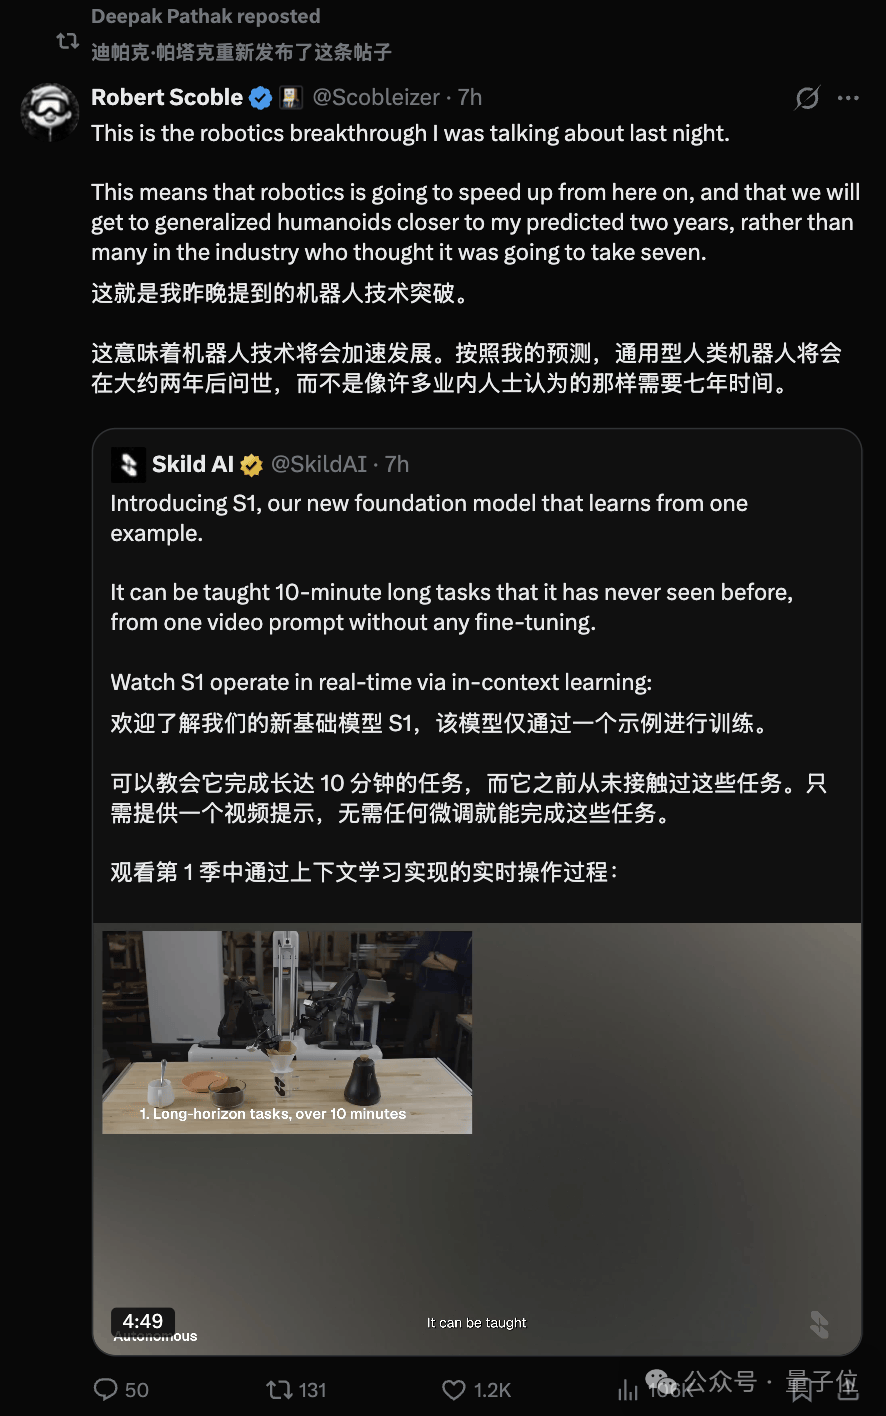
TL;DR - Skild AI released S1, a robot foundation model that learns new, long-horizon tasks from a single human demonstration video without fine-tuning or post-training. Its reported results suggest in-context learning could substantially reduce the real-world data cost of teaching robots new skills.

  • S1 uses video demonstrations as prompts while keeping model weights fixed, supporting previously unseen tasks lasting up to 10 minutes.
  • Demonstrations include making pancakes and coffee, repotting plants, and assembling equipment, with multi-step execution and recovery from errors.
  • On out-of-distribution tasks, S1 reportedly achieved 66% success versus 9% for a language-prompted vision-language-action model.
  • A conventionally post-trained model required about 380 demonstrations to match S1’s one-shot 66% result, though 2,000 demonstrations raised it to 86%.
Representative image for 宇树智元共用一个大脑!神秘模型Demo炸场,10分钟一镜到底

宇树智元共用一个大脑!神秘模型Demo炸场,10分钟一镜到底

Rank 64 · Content 70 · Popularity N/A

TL;DR - QbitAI reports an unedited 10-minute demo in which one unidentified embodied-AI model controls Unitree and AgiBot robots performing household tasks collaboratively. If independently verified, the cross-robot control, long-horizon task recovery, and physical adaptation would represent notable progress beyond hardware-specific VLA systems.

  • The robots reportedly navigate a cramped room, manipulate varied objects, clean, organize laundry, and resume interrupted tasks without external commands.
  • A shared model allegedly supports different robot bodies through unified action representations and embodiment adaptation, enabling cross-platform collaboration.
  • Demonstrated behaviors include force-sensitive manipulation, dynamic task scheduling, repeated action refinement, and using a box to address a height limitation.
  • The article attributes these capabilities to physics-constrained dynamics learning and robust closed-loop planning, but the model’s developer, architecture, training details, and independent validation remain undisclosed.

Financial Forecasting 1

Representative image for Falcon TST 2.0获世界权威测评第一名,推动时间序列基础模型从通用预测走向金融应用

Falcon TST 2.0获世界权威测评第一名,推动时间序列基础模型从通用预测走向金融应用

Rank 64 · Content 70 · Popularity N/A

TL;DR - Ant International released Falcon TST 2.0, a time-series foundation-model family that reports a 0.666 MASE on GIFT-Eval and targets production financial forecasting. Its significance lies in combining benchmark performance with deployments for cash-flow and foreign-exchange risk management at major banks and enterprises.

  • Falcon-2.0 uses an encoder-only architecture for efficient univariate forecasting, while Falcon-X models heterogeneous multivariate relationships through a shared latent space.
  • The models provide probabilistic forecasts across 21 quantiles and explicit missing-value masks, supporting scenario analysis and irregular financial data.
  • Reported forecasting accuracy exceeds 93%, with deployments involving Barclays, Citi, Deutsche Bank, and Standard Chartered; the technology is also being extended to aviation, logistics, and e-commerce.
  • The article cautions that benchmark leadership does not guarantee financial returns: domain adaptation, rolling backtests, tail-risk calibration, and leakage controls remain necessary.

Materials Discovery AI 1

Representative image for AI for Materials,10大核心玩家!

AI for Materials,10大核心玩家!

Rank 61 · Content 65 · Popularity N/A

TL;DR - An industry survey profiles 20 leading international and Chinese AI-for-materials companies developing foundation models, generative design tools, atomic simulations, and autonomous laboratories. Their work signals a shift from slow experimental trial-and-error toward computationally guided, closed-loop materials discovery.

  • DeepMind’s GNoME and Microsoft’s MatterGen exemplify large-scale crystal prediction and property-conditioned generation, with selected candidates progressing to experimental synthesis.
  • Platforms increasingly connect AI design, physics simulation, robotic experimentation, and feedback-driven model improvement into autonomous research loops.
  • Commercial applications span batteries, semiconductors, catalysts, carbon capture, cooling systems, alloys, and advanced manufacturing.
  • The competitive landscape includes model and cloud providers, materials-data platforms, simulation-software vendors, and vertically integrated companies pursuing discovery through industrialization.
Top highlights — Opinions

AI Governance 1

How to manage AI risks while reaping the benefits

Rank 52 · Content 55 · Popularity 46

TL;DR - This Nature commentary examines how AI risks can be managed without sacrificing the technology’s benefits, highlighting Europe’s leading role in regulation. The provided excerpt is too brief to identify specific policy recommendations.

  • Focuses on balancing AI risk mitigation with continued innovation and benefits.
  • Frames AI regulation as an active global policy debate.
  • Identifies European lawmakers as doing much of the regulatory work.
  • No technical findings or concrete regulatory mechanisms are included in the excerpt.

AI for Science 1

Representative image for 鄂维南院士:AI for Science,将走向“安卓模式”

鄂维南院士:AI for Science,将走向“安卓模式”

Rank 61 · Content 65 · Popularity N/A

TL;DR - Chinese mathematician E Weinan argues that AI for Science will evolve into an open, platform-based “Android model,” giving researchers low-barrier tools to test ideas. He sees this infrastructure as a major opportunity for China to accelerate scientific discovery and innovation.

  • AI-enabled research platforms could automate routine scientific work and provide shared infrastructure across disciplines.
  • Lower-cost, more efficient tools would let researchers validate ideas without mastering every underlying technical process.
  • E argues that automating conventional tasks could make original, high-impact discoveries more visible and valuable.
  • He criticizes publication-centered incentives for diluting the focus on open-ended exploration and genuine discovery.