让Token生产更高效:异构混推的关键技术演进与创新实践
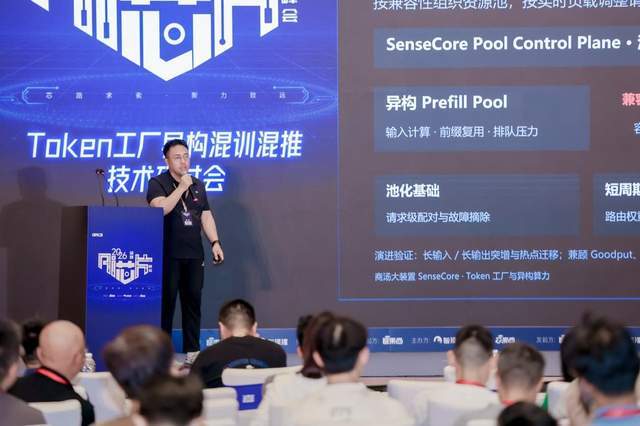
TL;DR - SenseTime describes an inference architecture that coordinates heterogeneous accelerators to increase token throughput and reduce unit costs under agent-era workloads. Its approach combines dynamic Prefill/Decode resource pools with model-, engine-, and chip-level optimization.
- A unified resource profile tracks each accelerator’s compute throughput, KV-cache capacity, bandwidth, and model compatibility for workload-aware scheduling.
- Prefill and Decode nodes can dynamically switch roles based on request lengths, traffic, KV-cache state, and node health instead of using fixed hardware assignments.
- Vertical optimization spans model quantization and memory budgets, parallelized Attention/GEMM operators, and chip-level compilation, memory scheduling, and management.
- The planned architecture extends pooling beyond Prefill/Decode to independently scalable Encoder, Attention, FFN, and vision-encoder modules for multimodal and MoE models.