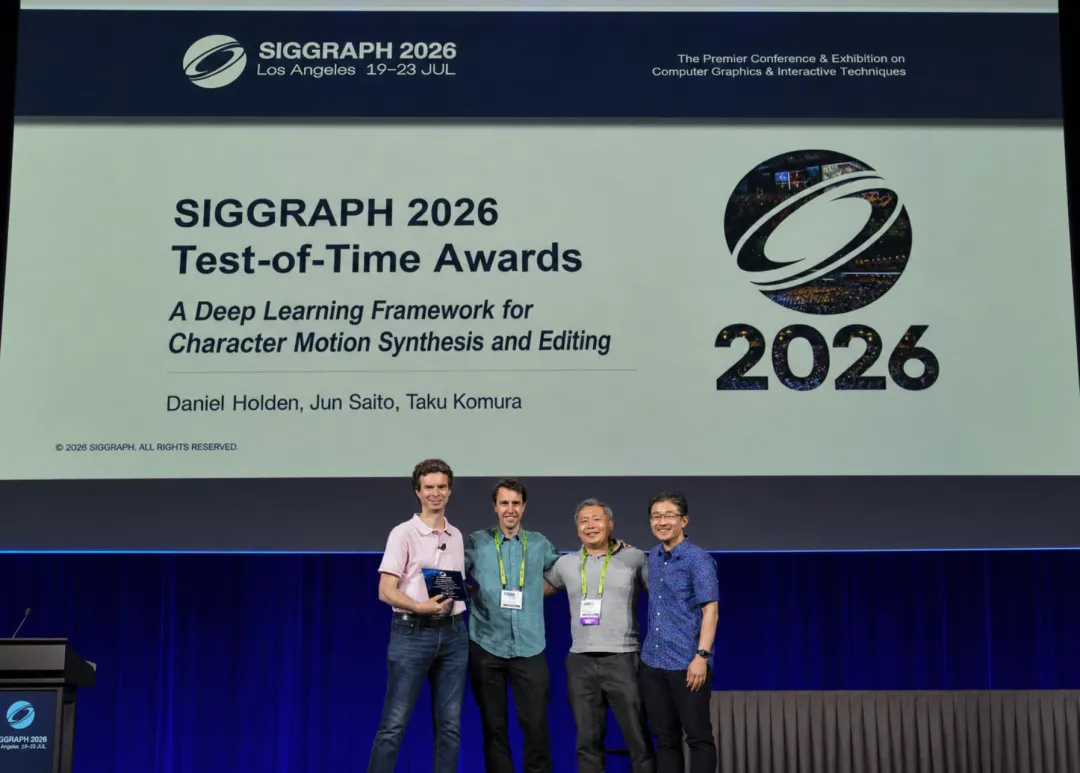
SIGGRAPH时间检验奖揭晓:这项研究,提前十年押中了物理AI
Ranking
Overall
61
Content
65
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
TL;DR - SIGGRAPH honored a 2016 deep-learning framework for character motion synthesis with its Test-of-Time Award. Its learned human-motion representations now underpin work on scalable embodied-AI data collection and physically grounded world models.
- The original framework used a convolutional autoencoder to learn a reusable low-dimensional motion space from motion-capture data, then generated natural movement from high-level controls.
- Follow-up systems modeled scene-aware interactions, multi-contact coordination, and temporal motion phases; the related AI4Animation project has over 8,000 GitHub stars.
- Human-motion priors let the team reconstruct hands, objects, and scenes from noisy consumer-device data, reportedly reducing error by 60% on a public first-person hand-reconstruction benchmark.
- Current work combines egocentric video, reconstructed 3D state, eye tracking, and electromyography to predict physical outcomes such as contact, force, and object-state changes.
Sources (1)
SIGGRAPH时间检验奖揭晓:这项研究,提前十年押中了物理AI
Public signals
N/A
TL;DR - SIGGRAPH honored a 2016 deep-learning framework for character motion synthesis with its Test-of-Time Award. Its learned human-motion representations now underpin work on scalable embodied-AI data collection and physically grounded world models.
- The original framework used a convolutional autoencoder to learn a reusable low-dimensional motion space from motion-capture data, then generated natural movement from high-level controls.
- Follow-up systems modeled scene-aware interactions, multi-contact coordination, and temporal motion phases; the related AI4Animation project has over 8,000 GitHub stars.
- Human-motion priors let the team reconstruct hands, objects, and scenes from noisy consumer-device data, reportedly reducing error by 60% on a public first-person hand-reconstruction benchmark.
- Current work combines egocentric video, reconstructed 3D state, eye tracking, and electromyography to predict physical outcomes such as contact, force, and object-state changes.