阿里Qwen3.8正式发布,编程与办公再进化,推理更快更稳定
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
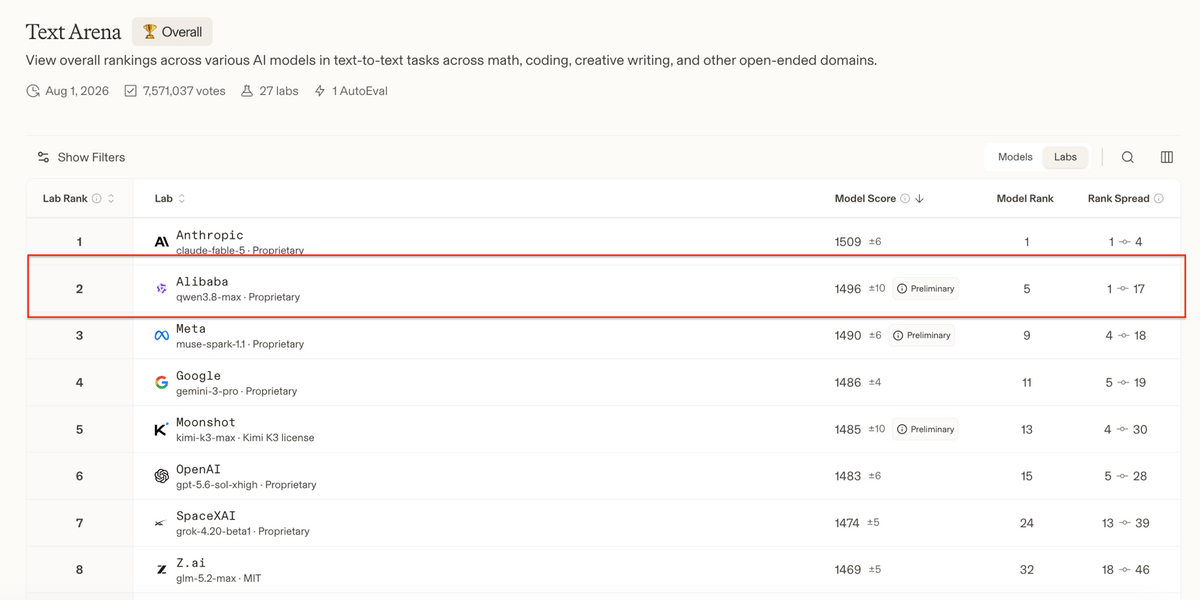
TL;DR — Alibaba released Qwen3.8, a 2.4T-parameter sparse-MoE flagship (95B active) with 1M-token context and native vision, aimed at agentic coding and long-horizon professional "Cowork" tasks. It matters as a price-aggressive frontier alternative — second only to Anthropic's Claude on Arena overall — with Qwen3.8-Max and Qwen3.8-27B slated for open-sourcing next week.
- Architecture & serving: Joint sparse-MoE + hybrid attention optimization scales totals to 2.4T with 95B activated for faster/cheaper inference; 1M-token context and native visual understanding. Alibaba's Zhenwu M890 supernode claims up to 1.5x agentic inference speedup.
- Pricing & availability: API live on the Qwen AI platform at ¥12/M input and ¥36/M output (¥1.5 on implicit cache hits) — stated as 40%/24% of Opus 5's international pricing — and wired into the new "Qianwen Office" agent product.
- Agentic coding: PaperBench 93.0 (+28.2 over prior gen) and 4th on CodeArena; a demo run had the model work unattended for ~16 days from an empty folder to build "oh-my-cli," a self-evolving agent framework now published on GitHub.
- Agent & reasoning benchmarks: WideSearch 81.9, Agent's Last Exam 52.4, IFBench 82.8, GPQA Diamond 92.6, and OSWorld-Verified 86.1 (claimed first among mainstream models).
- Multimodal: 2nd on Vision Arena; BabyVision 82.0 without tools; handles 200-page PDFs and 100+ hour video, plus a self-built RecreationBench for zero-source-code app replication via iterative visual coding.
Emphasis differs slightly: 量子位 flags that all figures are vendor-supplied from an authorized Alibaba release and not independently verified, while 雷峰网 foregrounds productization (API pricing tiers, "Qianwen Office" integration) and the open-source roadmap.
Sources (2)
阿里Qwen3.8正式发布,编程与办公再进化,推理更快更稳定
TL;DR - Alibaba released Qwen3.8, a 2.4T-parameter sparse-MoE flagship (95B active) with 1M-token context and vision understanding, positioned second only to Anthropic's Claude on Arena and aimed squarely at agentic coding and professional "Cowork" tasks. It matters as a price-aggressive frontier alternative, with Qwen3.8-Max and Qwen3.8-27B slated for open-sourcing next week.
- Architecture/serving: joint sparse-MoE + hybrid attention optimization scales totals to 2.4T with 95B activated; API priced at ¥12/M input and ¥36/M output (¥1.5 on implicit cache hits), stated as 40%/24% of Opus 5's international pricing; Alibaba's Zhenwu M890 supernode claims up to 1.5x agentic inference speedup.
- Agentic coding: PaperBench 93.0 (+28.2 over prior gen), 4th on CodeArena; a demo run had the model autonomously build a self-evolving agent framework "oh-my-cli" over ~16 days from an empty folder, with the repo published on GitHub.
- General agent + reasoning: WideSearch 81.9, Agent's Last Exam 52.4, IF Bench 82.8, GPQA Diamond 92.6, OSWorld-Verified 86.1 (claimed top among mainstream models).
- Multimodal: 2nd on Vision Arena; BabyVision 82.0 without tools; handles 200-page PDFs and 100+ hour video, with a self-built RecreationBench for zero-source-code app replication via iterative visual coding.
Note: figures are vendor-supplied (the article is an authorized Alibaba-provided release), not independently verified.
阿里Qwen3.8正式发布,编程与办公再进化,推理更快更稳定
TL;DR - Alibaba released Qwen3.8, a 2.4T-parameter (95B active) sparse-MoE flagship with 1M-token context and vision support, positioned as a top-tier model for autonomous coding and long-horizon professional "Cowork" tasks. It matters because it pairs frontier agentic benchmark claims with aggressive pricing (40%/24% of Opus 5 input/output internationally) and a promised open-source release.
- Architecture: sparse MoE plus hybrid attention scales total params to 2.4T with 95B activated, targeting faster/cheaper inference; 1M-token context and native visual understanding. Alibaba's Zhenwu M890 supernode claims up to 1.5x speedup in agentic inference.
- Claimed benchmarks: PaperBench 93.0 (+28.2 over prior gen), WideSearch 81.9, Agent's Last Exam 52.4, IFBench 82.8, GPQA Diamond 92.6, OSWorld-Verified 86.1 (reported first among mainstream models), BabyVision 82.0 tool-free; 4th on CodeArena, 2nd on Vision Arena, and second only to Claude on Arena overall.
- Agentic showcase: ran ~16 days unattended from an empty folder to produce "oh-my-cli," an open-sourced self-evolving agent framework, plus a RecreationBench app-replication task solved offline via iterative visual coding.
- Availability: API live on the Qwen AI platform (¥12/M input, ¥36/M output, ¥1.5 cached) and wired into the new "Qianwen Office" agent product; Qwen3.8-Max and Qwen3.8-27B slated to open-source next week.