RT by @huggingface: Thinking Machines released Inkling Small (🦖) + NVFP4 12B active 276B total…
Ranking
No observed public metrics; popularity remains neutral/archived.
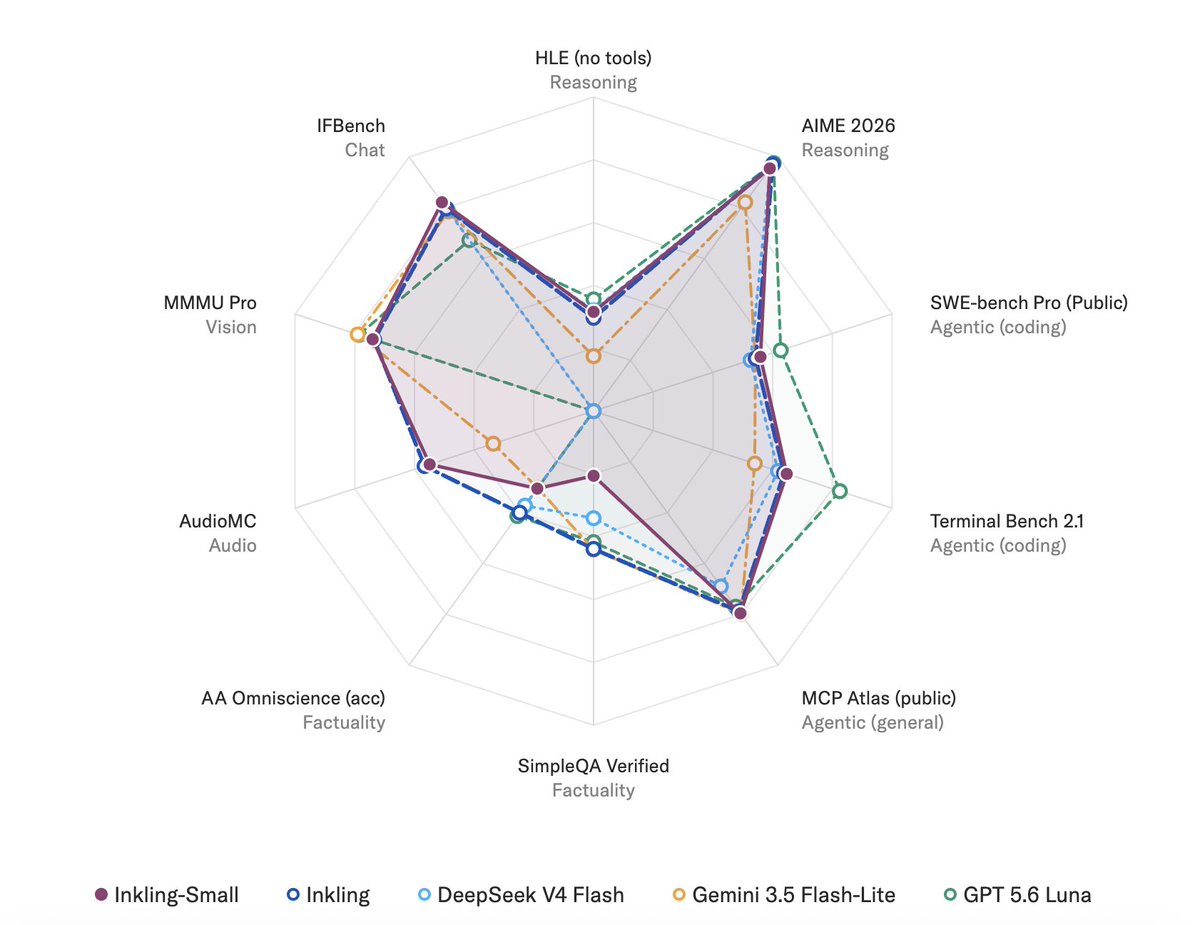
Merged summary
TL;DR - Thinking Machines released Inkling Small, a sparse Mixture-of-Experts model (12B active / 276B total params) shipped in NVFP4 format, with Hugging Face publishing a companion blog on benchmarks, performance, and deployment. It matters because a smaller-active-parameter model reportedly beats the larger Inkling on coding, suggesting gains from sparsity and low-precision formats rather than raw scale.
- Architecture is sparse MoE: 276B total parameters with only 12B active per token, targeting large-model quality at small-model inference cost.
- Distributed in NVFP4 (NVIDIA 4-bit floating point), a quantized format aimed at efficient serving on modern NVIDIA hardware.
- Claimed to outperform the larger Inkling model on coding tasks — a counter-intuitive result, though no specific benchmark numbers are given in this post.
- Weights are available via a Hugging Face collection, with a HF blog covering benchmarks and deployment; details beyond the announcement are thin here and would need the linked blog to verify.
Sources (1)
RT by @huggingface: Thinking Machines released Inkling Small (🦖) + NVFP4 12B active 276B total…
TL;DR - Thinking Machines released Inkling Small, a sparse Mixture-of-Experts model (12B active / 276B total params) shipped in NVFP4 format, with Hugging Face publishing a companion blog on benchmarks, performance, and deployment. It matters because a smaller-active-parameter model reportedly beats the larger Inkling on coding, suggesting gains from sparsity and low-precision formats rather than raw scale.
- Architecture is sparse MoE: 276B total parameters with only 12B active per token, targeting large-model quality at small-model inference cost.
- Distributed in NVFP4 (NVIDIA 4-bit floating point), a quantized format aimed at efficient serving on modern NVIDIA hardware.
- Claimed to outperform the larger Inkling model on coding tasks — a counter-intuitive result, though no specific benchmark numbers are given in this post.
- Weights are available via a Hugging Face collection, with a HF blog covering benchmarks and deployment; details beyond the announcement are thin here and would need the linked blog to verify.