闭源RSI的严父:18个Agent自主科研,Kimi K3靠Harness逼近Opus 5
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
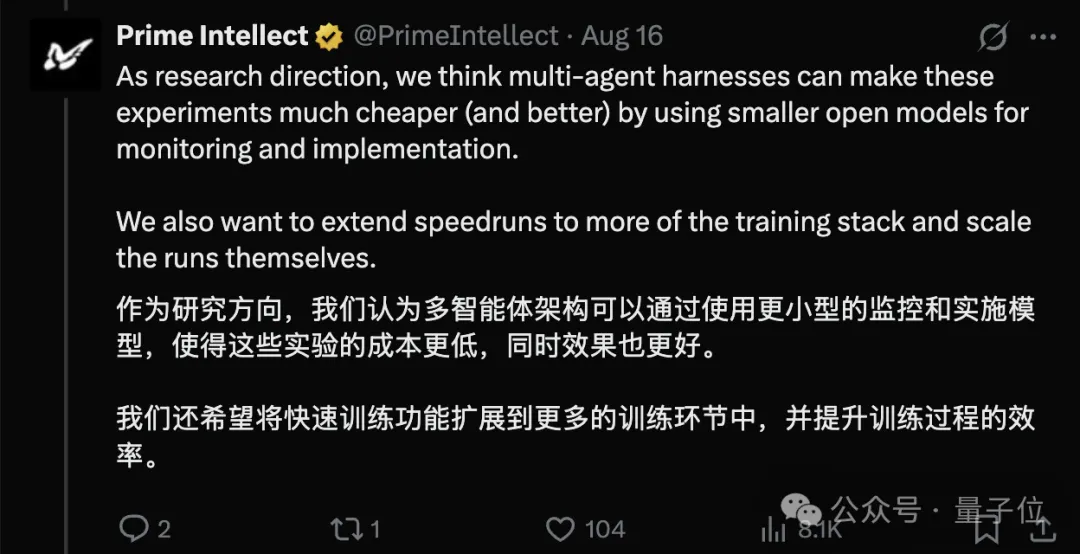
TL;DR - Prime Intellect reports that its multi-agent research harness lets cheaper open-weight models autonomously optimize nanoGPT training, with Kimi K3 reaching 2,930 steps—close to Opus 5’s 2,920 and ahead of GPT-5.6 Sol’s 3,042. The results suggest AI-for-AI progress may depend as much on experimental throughput and infrastructure as on the underlying model.
- Across 153 autonomous runs involving 18 models, agents modified code, launched training, analyzed noisy results, and selected follow-up experiments without internet access.
- The benchmark measured how quickly agents could reduce a 124M-parameter GPT’s validation loss below 3.28, starting from a 3,290-step baseline; the human record is 2,600 steps.
- Fable 5 achieved the best agent result at 2,726 steps, capturing about 82% of the available improvement between the baseline and human record.
- Successful agents did not invent fundamentally new methods; their advantage came from repeated validation, noise handling, revisiting discarded ideas, tool creation, and higher experimentation throughput.
Sources (1)
闭源RSI的严父:18个Agent自主科研,Kimi K3靠Harness逼近Opus 5
TL;DR - Prime Intellect reports that its multi-agent research harness lets cheaper open-weight models autonomously optimize nanoGPT training, with Kimi K3 reaching 2,930 steps—close to Opus 5’s 2,920 and ahead of GPT-5.6 Sol’s 3,042. The results suggest AI-for-AI progress may depend as much on experimental throughput and infrastructure as on the underlying model.
- Across 153 autonomous runs involving 18 models, agents modified code, launched training, analyzed noisy results, and selected follow-up experiments without internet access.
- The benchmark measured how quickly agents could reduce a 124M-parameter GPT’s validation loss below 3.28, starting from a 3,290-step baseline; the human record is 2,600 steps.
- Fable 5 achieved the best agent result at 2,726 steps, capturing about 82% of the available improvement between the baseline and human record.
- Successful agents did not invent fundamentally new methods; their advantage came from repeated validation, noise handling, revisiting discarded ideas, tool creation, and higher experimentation throughput.