硅谷今日最热具身模型!不用后训练,看一遍就学会
Ranking
Overall
75
Content
85
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
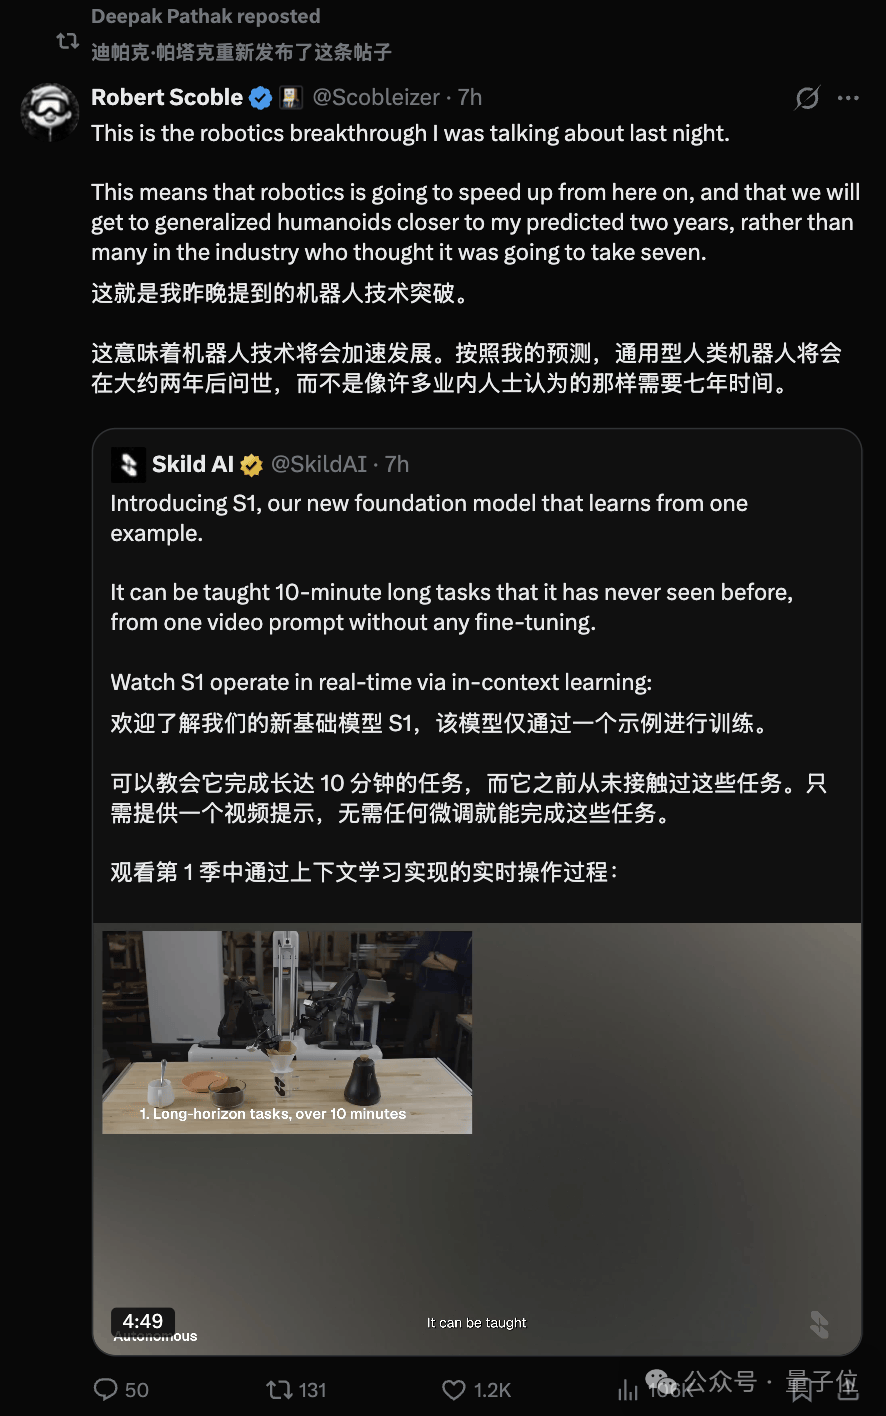
TL;DR - Skild AI released S1, a robot foundation model that learns new, long-horizon tasks from a single human demonstration video without fine-tuning or post-training. Its reported results suggest in-context learning could substantially reduce the real-world data cost of teaching robots new skills.
- S1 uses video demonstrations as prompts while keeping model weights fixed, supporting previously unseen tasks lasting up to 10 minutes.
- Demonstrations include making pancakes and coffee, repotting plants, and assembling equipment, with multi-step execution and recovery from errors.
- On out-of-distribution tasks, S1 reportedly achieved 66% success versus 9% for a language-prompted vision-language-action model.
- A conventionally post-trained model required about 380 demonstrations to match S1’s one-shot 66% result, though 2,000 demonstrations raised it to 86%.
Sources (1)
硅谷今日最热具身模型!不用后训练,看一遍就学会
Public signals
N/A
TL;DR - Skild AI released S1, a robot foundation model that learns new, long-horizon tasks from a single human demonstration video without fine-tuning or post-training. Its reported results suggest in-context learning could substantially reduce the real-world data cost of teaching robots new skills.
- S1 uses video demonstrations as prompts while keeping model weights fixed, supporting previously unseen tasks lasting up to 10 minutes.
- Demonstrations include making pancakes and coffee, repotting plants, and assembling equipment, with multi-step execution and recovery from errors.
- On out-of-distribution tasks, S1 reportedly achieved 66% success versus 9% for a language-prompted vision-language-action model.
- A conventionally post-trained model required about 380 demonstrations to match S1’s one-shot 66% result, though 2,000 demonstrations raised it to 86%.