千问办公首发上线Qwen3.8-Flash,生成速度提升100%,Token消耗减少75%
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
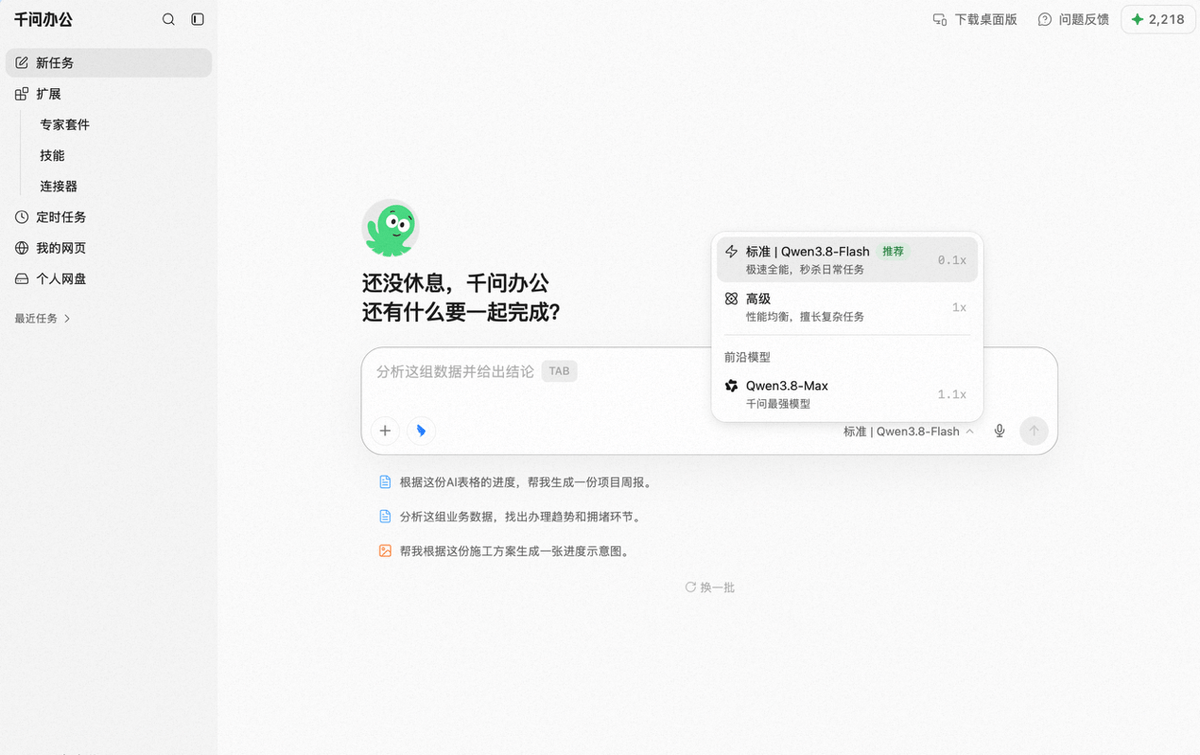
TL;DR — 千问办公上线以办公场景优化版 Qwen3.8-Flash 驱动的标准模式;据官方内部真实办公任务测试,其生成速度提升约 100%,平均 Token 消耗减少 75%,旨在兼顾智能体能力、延迟与成本。
- Qwen3.8-Flash 被描述为采用新架构、总参数达数千亿级,千问称其性能超过 Claude Opus 4.6。
- 办公专用版本重点强化了多步骤规划、工具选择和上下文压缩能力。
- 性能提升不仅来自模型调优,也结合了推理优化与定制化智能体框架,以提高吞吐并降低资源消耗。
- 千问办公预计标准模式可处理 95% 的日常办公任务,其余 5% 的复杂工作由高级模式承担。
- 速度与 Token 效率数据均源于千问内部的真实办公场景测试。
注: 量子位更强调模型架构、参数规模及性能定位,雷峰网则更侧重模型、智能体框架与推理栈的协同优化。
Sources (2)
千问办公首发上线Qwen3.8-Flash,生成速度提升100%,Token消耗减少75%
TL;DR - Qwen Office has launched a standard mode powered by an office-optimized Qwen3.8-Flash, claiming roughly twice the generation speed and 75% lower average token use on real office tasks. The release targets the typical trade-off between agent performance, latency, and cost.
- Qwen3.8-Flash is described as a new architecture with hundreds of billions of total parameters and performance exceeding Claude Opus 4.6, according to Qwen.
- The office-specific model was tuned for multi-step planning, tool selection, and context compression.
- Inference optimizations and a customized agent harness reportedly improve token throughput and reduce resource consumption.
- Qwen expects the standard mode to handle 95% of routine office tasks, reserving an advanced mode for the remaining complex workloads.
千问办公首发上线Qwen3.8-Flash,生成速度提升100%,Token消耗减少75%
TL;DR - Qwen Office launched Qwen3.8-Flash as its new standard model, claiming roughly 2× faster generation and 75% lower average token usage in real office tasks. The release combines a specialized model variant with agent and inference-stack optimizations to improve performance, cost, and latency.
- Qwen3.8-Flash was tuned for multi-step planning, tool selection, and context compression in office workflows.
- Further gains come from inference optimizations and a customized agent harness architecture.
- Qwen Office says its standard mode can handle 95% of everyday tasks, reserving advanced mode for the remaining 5% of complex work.
- The reported speed and token-efficiency improvements are based on the company’s internal real-world office scenario tests.