🛰️ Daily AI Frontier
51 works · 2 categories · 21 topics · arxiv 30 blog 24 journal 20 wechat 15 generated 2026-08-27 14:26:01 UTC
Top highlights — Research

LLM Agents 10

Representative image for JIT-Agent: Scaling Harness Intelligence via Just-in-Time Harness Evolution

JIT-Agent: Scaling Harness Intelligence via Just-in-Time Harness Evolution

Rank 92 · Content 95 · Popularity 84

TL;DR - JIT-Agent is a model that generates and repairs task-specific agent harnesses at runtime, adapting memory, planning, action protocols, and tool orchestration for off-the-shelf LLMs. The results suggest harness optimization can improve agent performance independently of—and sometimes more than—switching to a stronger foundation model.

  • Formalizes agent harnesses as machine-generatable artifacts built from a fixed four-module protocol.
  • Learns to customize harnesses per task, repair them for reliable execution, and evolve them using archived performance signals.
  • With generated harnesses, DeepSeek-V4-Flash reportedly exceeds GPT-5.6 by 9.1 points on DeepSearchQA and 4.3 on OdysseyBench; GLM-5.2 gains up to 20.2 points.
  • Generated harnesses are competitive with mature runtimes such as OpenCode and Claude Code and consistently improve several model families.

Pointing the Way, Hiding the Destination: Practical Private Dense Retrieval at Scale

Rank 91 · Content 100 · Popularity 71

TL;DR - This paper presents a privacy-preserving dense retrieval protocol for hosted RAG and semantic search that uses learned deep hashing to privately narrow searches before encrypted reranking. It approaches full-corpus retrieval quality while adding only 0.73 seconds to a Qwen3-32B RAG pipeline on a 2.68M-passage corpus.

  • Randomized binary codes produce short candidate lists while hiding queries and reducing full-corpus cryptographic computation.
  • Encrypted reranking and oblivious key transfer protect the exact query, selected result, and access authorization.
  • Shortlists of 200–500 candidates closely match full-corpus retrieval across five zero-shot datasets ranging from 25K to 5.4M documents.
  • The released implementation satisfies directional metric differential privacy and reduces embedding-inversion and property-inference leakage.
Representative image for SwarmWorld: Stigmergic technological evolution in societies of language-model agents

SwarmWorld: Stigmergic technological evolution in societies of language-model agents

Rank 86 · Content 95 · Popularity 66

TL;DR - SwarmWorld shows that homogeneous LLM agents can self-organize through persistent environmental artifacts, without predefined roles or centralized workflows, to build resilient technological societies. These societies outperform best-of-N isolated search in portfolio breadth and robustness, though isolated search remains competitive for the single strongest artifact.

  • Agents autonomously differentiate into exploration, construction, maintenance, and coordination behaviors as their environment matures.
  • A deterministic simulator evaluates agent-designed artifacts and executable controllers under unseen disturbances after the agents are removed.
  • Technologies accumulate through collaborative construction, executable inheritance, and persistent agent-artifact networks.
  • Physical observation and stigmergy drive most reuse; explicit cultural mechanisms strengthen organization, but their functional benefits vary by outcome and timescale.
Representative image for Safety Does Not Compose: Non-Decaying Loop State for Autonomous LLM Agents

Safety Does Not Compose: Non-Decaying Loop State for Autonomous LLM Agents

Rank 83 · Content 100 · Popularity 42

TL;DR - This paper argues that trajectory-scoped safeguards cannot detect attacks whose evidence is distributed across multiple autonomous-agent iterations. It proposes LoopHarness, which maintains persistent, non-decaying loop-level safety state to limit irreversible unauthorized actions independently of the execution horizon.

  • The authors prove that trajectory-only monitors cannot distinguish fragmented attacks from benign behavior better than their false-positive rate, regardless of monitor expressiveness.
  • Geometrically decaying risk scores remain vulnerable because patient attackers need only wait a constant cooling-off period that does not grow with the loop horizon.
  • LoopHarness combines persistent safety state, mediated commits, and an arbiter to bound expected unauthorized irreversible actions by (B+m-1+m/\delta_M), constant in horizon (N).
  • The evaluation protocol covers paired clean and attacked Agent-SafetyBench episodes, cross-iteration attacks, module ablations, and adaptive white-box red teaming.
Representative image for PLCBench: Can Autonomous LLM Agents Turn PLC Access into Sustained Physical Impact?

PLCBench: Can Autonomous LLM Agents Turn PLC Access into Sustained Physical Impact?

Rank 83 · Content 100 · Popularity 42

TL;DR - PLCBench is a hardware-in-the-loop benchmark that measures whether autonomous, tool-using LLM agents can turn access to commercial programmable logic controllers into sustained physical impact. Across 240 trials, agents achieved their physical objectives in 31.3% of episodes, demonstrating a measurable cyber-physical threat while pinpointing common failure stages.

  • The framework combines vendor-native PLC interaction, four commercial PLCs, four closed-loop simulated processes, and independent deterministic outcome verification.
  • Of 240 episodes spanning five LLM families, 75 sustained their assigned physical objectives.
  • Ninety-eight episodes failed before a valid native read; another 62 achieved a process-linked write but failed to sustain the objective.
  • Richer process observations raised conditional success after a process-linked write from 44.2% to 64.0%.
Representative image for Verify Smarter, Evolve Further: Efficient Harness Evolution through Behavior-Aware Verification

Verify Smarter, Evolve Further: Efficient Harness Evolution through Behavior-Aware Verification

Rank 83 · Content 100 · Popularity 42

TL;DR - HarnessLens is a budget-aware framework that evolves agent harnesses while selectively testing candidate changes on behavior-relevant tasks. It improves held-out performance by 7.6–13.6% across multiple harnesses and benchmarks while using substantially less evaluation budget than competing methods.

  • Jointly explores task space and user-configurable harness components.
  • Proposes modifications based on agent execution trajectories.
  • Uses an attributable-evidence gate to target verification and detect behavior-specific regressions.
  • Evaluated on three agent harnesses and four benchmarks under constrained interaction budgets.

Calibrated Enough to Know, Not Calibrated to Act: Fabricated Evidence Makes LLM Agents Commit to the Unknowable

Rank 81 · Content 100 · Popularity 37

TL;DR - A study of 12 frontier models finds that authoritative-looking evidence—even when entirely fabricated—can make LLM agents act on provably unpredictable questions without materially changing their stated beliefs. The failure lies in a trainable but context-fragile decision gate between recognizing uncertainty and refusing to act.

  • Escalating evidence displays increased commitment from 6.5% to 54.0%; fabricated panels induced commitment at a rate statistically indistinguishable from genuine market data.
  • Models correctly classified questions as irreducibly unknowable 90% of the time and committed on only 0.4% of those cases when explicitly asked to assess knowability first.
  • Fine-tuning a 3B model on 540 synthetic examples reduced commitment to 0.0% on the original cases and transferred to three unseen domains.
  • The improvement depended on response formats allowing reasoning; rigid formats undermined the abstention gate and could leave models confidently wrong.
Representative image for TraceML: An Empirical Analysis of Human-Agent Planning in Machine Learning Development

TraceML: An Empirical Analysis of Human-Agent Planning in Machine Learning Development

Rank 79 · Content 95 · Popularity 42

TL;DR - TraceML is a process-level benchmark comparing human and AI-agent trajectories on machine-learning competitions. It shows that agents underperform partly because they repeat narrow optimization loops rather than pivoting, revisiting abandoned ideas, and coordinating diverse development activities like experts.

  • The dataset contains 4,465 human Kaggle trajectories across 134 competitions, including 430 human and 207 agent trajectories on seven shared competitions.
  • Each code version is annotated with score, timestamp, action, intent, edit size, and score effect, enabling analysis beyond final benchmark outcomes.
  • Codex focused heavily on ensemble reweighting and submission tuning, while MLEvolve repeatedly mutated its current model; neither pivoted or reopened prior approaches as often as humans.
  • A planning prompt distilled from human behavior improved targeted behaviors and scores, but did not eliminate the agents’ broader planning-pattern gap.
Representative image for EVOMAL: Self-Poisoning in Self-Evolving Coding Agents

EVOMAL: Self-Poisoning in Self-Evolving Coding Agents

Rank 79 · Content 95 · Popularity 42

TL;DR - EVOMAL exposes a self-poisoning vulnerability in self-evolving coding agents: malicious skills can be imitated, stored, executed, and propagated through shared skill libraries. The attack persists after the original planted skills are removed, while a counter-prompt reduces the measured attack rate substantially without significant task-completion loss.

  • Across six models and 153 SWE-bench Verified tasks, agent self-poisoning rates ranged from 20.3% to 41.8%, expanding malicious skills by 4.9–9.0×.
  • Task-specific malicious skill descriptions raised the self-poisoning rate to 86.7%; payload-only attacks also worked, reaching 11.1% on DeepSeek-V4-Pro.
  • Agent-authored copies formed a persistent propagation loop; Qwen3 still showed a 68% self-poisoning rate in round five after planted skills were removed.
  • A counter-prompt discouraging banner-style copying reduced the attack rate to at most 6.7% with no significant task-completion loss.
Representative image for From General Agents to RCA Experts: A Self-Evolving Harness for Root Cause Analysis

From General Agents to RCA Experts: A Self-Evolving Harness for Root Cause Analysis

Rank 79 · Content 95 · Popularity 42

TL;DR - OpsHarness is a self-evolving harness that adapts general-purpose LLM agents for root cause analysis by converting prior diagnostic experience into reusable, system-specific expertise. It reports 59.0% top-1 accuracy across public benchmarks and an industrial deployment, outperforming both an unmodified general agent and specialized RCA baselines.

  • The study finds modern general agents often outperform purpose-built RCA agents, but their external adaptation harness remains a key production bottleneck.
  • OpsHarness combines layered operational knowledge and an “idea-card” tool library with workflows for setup, diagnosis, evolution, and verification.
  • It learns by contrasting successful and failed diagnostic trajectories, extracting atomic update proposals, and applying dual-gate verification to limit overfitting and regressions.
  • Its 59.0% top-1 accuracy represents a 63.4% improvement over a bare general agent and a 4.02× improvement over baseline RCA agents.

Medical/Healthcare AI 9

A multimodal, all-optical platform for linking cell identity to metabolic function in intact tissues

Rank 84 · Content 100 · Popularity 46

TL;DR - REDCAT is an all-optical platform that connects cell identity with metabolic activity in intact tissues at single-cell and subcellular resolution. It could advance functional histopathology by revealing disease-associated metabolic changes and intratumoral heterogeneity.

  • Integrates Raman imaging, autofluorescence, and high-plex immunofluorescence.
  • Maps metabolic features alongside cellular identity without disrupting tissue structure.
  • Resolved metabolic characteristics in normal lymph nodes and lipid-redox remodeling in lymphoma.
  • Exposed metabolic heterogeneity within tumors, suggesting potential diagnostic and research applications.

FRAME: separating sampling variation from representational cause in medical imaging fairness

Rank 83 · Content 100 · Popularity 42

TL;DR - FRAME is a two-step framework for determining whether subgroup performance gaps in medical imaging reflect sampling variation or representational mechanisms. Across large-scale experiments and prior studies, it attributes substantial portions of reported fairness gaps to cohort-size effects and questions interventions focused only on removing demographic information.

  • FRAME first estimates the expected performance-gap distribution under exact fairness at observed subgroup sizes, then tests the remaining gap with representation-space interventions.
  • Across 702,206 images and 36 encoders, sampling variation explained a median 41% of race differences and 22% of age differences.
  • Adding demographic decodability did not change the remainder, while entangling demographic group with the disease direction increased the race difference from 0.077 to 0.118.
  • Across 89 differences from nine studies, the reference explained a median 25% of rate gaps and 70% of AUROC gaps; image-text pretraining improved worst-group performance by about 0.05.
Representative image for SeVeR: Selective Visual Exposure and Retrieval for 3D Medical Image Question Answering

SeVeR: Selective Visual Exposure and Retrieval for 3D Medical Image Question Answering

Rank 83 · Content 100 · Popularity 42

TL;DR - SeVeR is a selective visual retrieval framework for 3D medical visual question answering that reduces redundant visual-token exposure while improving answer performance. The work also introduces BreMRIs-VQA, a large, clinically curated breast MRI benchmark.

  • BreMRIs-VQA contains 1.19 million free-text and multiple-choice QA pairs from 71,000 MRI sequences across 12,900 patients.
  • SeVeR compresses dense 3D volumes into modality-specific prototypes, then retrieves complementary evidence at multiple levels during decoding.
  • Change-aware gated attention and a marginal-utility self-consistency objective suppress retrieval that does not improve reasoning.
  • Experiments on BreMRIs-VQA and public benchmarks report better discriminative and generative performance with substantially fewer exposed visual tokens.
Representative image for Auditable CT Phenotyping Through Report-derived Radiological Observations

Auditable CT Phenotyping Through Report-derived Radiological Observations

Rank 79 · Content 95 · Popularity 42

TL;DR - ACT is an auditable CT phenotyping method that uses report-derived radiological observations to reveal whether predictions rely on clinically valid evidence or diagnostic shortcuts. It outperformed several baselines while showing that high accuracy can mask reliance on unrelated findings.

  • Trained on 38,317 patients and 376,194 mined observations, then evaluated on 25,183 held-out patients across 221 EHR phenotypes.
  • Outperformed CT-CLIP on unseen CT pulmonary angiography in zero-shot scoring (0.651 vs. 0.572) and linear probing (0.709 vs. 0.662).
  • Just 97 observations filled all 221 top-ranked evidence positions; one calcification phrase ranked first for 20 phenotypes, including clinically unrelated conditions.
  • Restricting evidence to clinician-specified observations redirected probes toward phenotype-relevant findings in 86 phenotypes without reducing accuracy (0.751 vs. 0.741).

FlowMoDL: Model-Based Deep Learning with Conjugate-Gradient Data Consistency for Highly Accelerated 4D Flow MRI Reconstruction

Rank 79 · Content 95 · Popularity 42

TL;DR - FlowMoDL is an unrolled neural network for reconstructing highly accelerated 4D flow MRI while preserving anatomical detail and phase-derived blood-flow velocity accuracy. It supports acceleration factors from 10× to 50× with one model and outperforms classical and deep-learning baselines under a limited gradient-step budget.

  • Alternates a learned (3+1)D spatiotemporal denoiser with conjugate-gradient SENSE data-consistency updates.
  • Uses dual-pathway conditioning to adapt denoiser features and data-consistency weighting across acceleration factors.
  • Trains with deep supervision on magnitude, velocity magnitude, and angular errors, stabilized through curriculum learning.
  • On the multi-center CMRx4DFlow dataset, it leads all evaluated baselines across magnitude SSIM, nRMSE, relative velocity error, and angular error.
Representative image for Learning a Continuous Sepsis Severity Score Without Hour-by-Hour Supervision: A Two-Site Retrospective Study

Learning a Continuous Sepsis Severity Score Without Hour-by-Hour Supervision: A Two-Site Retrospective Study

Rank 78 · Content 95 · Popularity 37

TL;DR - This two-site retrospective study learns a continuous, hourly sepsis severity score from patient trajectories using mortality as a treatment-level ranking signal rather than requiring per-hour labels. The resulting index tracks outcomes and clinically relevant changes, suggesting potential as a decision-support complement to clinician judgment.

  • The model uses 43 routinely charted variables over a 72-hour treatment window across cohorts of 29,116 and 7,691 adults meeting Sepsis-3 criteria.
  • Within every baseline SOFA-2 stratum, non-survivors scored 1.19–1.64 points higher than survivors on the 0–10 scale; stratification by lactate, mean arterial pressure, and creatinine yielded similar separation.
  • Within-patient score changes correlated most strongly with lactate changes (Spearman ρ = 0.39; n = 1,854), with weaker correlations for mean arterial pressure and creatinine.
  • Models trained at different institutions achieved 70–77% of same-site cohort-level correlation, while external within-patient correlations reached 0.54 and 0.59 against estimated ceilings of 0.92 and 0.90.

Making Clinical Language Models Auditable: Concept-Guided Fine-Tuning for Robust Prediction

Rank 78 · Content 95 · Popularity 37

TL;DR - CAST is an SAE-based fine-tuning framework that makes clinical text classifiers more robust and auditable by identifying and suppressing features tied to note artifacts rather than patient state. On MIMIC-IV mortality prediction, it improves over corresponding fine-tuned encoder baselines while providing concept-level audit trails.

  • Sparse autoencoders expose human-auditable features from intermediate Transformer activations.
  • An LLM-assisted pipeline with ICD-10 retrieval constraints labels SAE latents as clinical concepts or artifacts.
  • Verified artifact latents are suppressed through residual subtraction during fine-tuning.
  • Post-hoc attributions show which clinical concepts supported each prediction and which artifacts were suppressed.

Aberrant excitatory neuronal ERBB4 promotes Alzheimer’s disease pathology

Rank 76 · Content 80 · Popularity 68

TL;DR - A Nature study links aberrant ERBB4 activity in excitatory neurons to Alzheimer’s disease pathology. The supplied abstract snippet suggests early synapse loss may occur without neuroinflammation alone being necessary.

  • Focuses on neuronal ERBB4 as a potential driver of Alzheimer’s pathology.
  • Challenges models that treat neuroinflammation as essential for early synapse loss.
  • The provided content does not include experimental methods, effect sizes, or therapeutic findings.

Systems vaccinology and the architecture of human immunity

Rank 73 · Content 85 · Popularity 46

TL;DR - This Nature review surveys systems vaccinology and how integrated, data-driven analyses can characterize the architecture of human immune responses to vaccination. It highlights the challenge of translating research insights into clinical and regulatory practice.

  • Reviews the current state of systems-level vaccine and immunity research.
  • Focuses on understanding human immune responses through an integrated systems perspective.
  • Examines barriers between research findings and practical clinical use.
  • Discusses challenges in incorporating systems-vaccinology evidence into regulatory processes.

Bioinformatics AI 7

All-optical multimodal mapping of single-cell-type-specific metabolic activities via REDCAT

Rank 91 · Content 100 · Popularity 71

TL;DR - REDCAT is an all-optical tissue-mapping method that combines stimulated Raman scattering microscopy with high-plex immunofluorescence to profile cell-type-specific molecular and metabolic features. It enables multimodal single-cell analysis while preserving spatial tissue context.

  • Integrates label-free Raman-based imaging with multiplexed protein detection.
  • Profiles proteins, lipids, nuclear metabolites, and redox metabolism at single-cell resolution.
  • Links metabolic activity to specific cell types within intact tissue.
  • Supports spatially resolved construction of richer cellular atlases.

Ultrafast and reference-free sequence discovery in single-cell data

Rank 84 · Content 100 · Popularity 46

TL;DR - Malva is a method for ultrafast, reference-free discovery of raw sequences in single-cell datasets spanning millions of cells. It could turn static transcriptomic atlases into searchable resources for investigating sequence function.

  • Searches raw single-cell sequences without requiring a reference sequence.
  • Scales sequence discovery across millions of cells.
  • Enables dynamic querying of large transcriptomic atlases.
  • The provided abstract does not specify benchmarks, implementation details, or biological findings.

Long-read sequencing reveals pre-meiotic gene conversion in sperm

Rank 80 · Content 95 · Popularity 46

TL;DR - Single-molecule long-read sequencing of human sperm reveals donor-level variation in recombination and indicates that many non-crossover gene conversions occur before meiosis. This distinguishes them from PRDM9-driven meiotic recombination and links them to fragile genomic sites.

  • Profiles recombination directly in human sperm using single-molecule long-read sequencing.
  • Finds that recombination patterns vary across donors.
  • Shows that a substantial fraction of non-crossover gene conversions arise pre-meiotically.
  • Associates these events with fragile sites rather than PRDM9-driven recombination.

Cell-type-specific eQTLs underlie the genetic architecture of complex traits

Rank 79 · Content 95 · Popularity 43

TL;DR - A Nature study uses single-cell RNA sequencing to show that cell-type-specific expression quantitative trait loci (eQTLs) account for much of the genetic architecture of complex traits. The findings help connect trait-associated genetic variants to the particular cellular contexts in which they regulate genes.

  • Maps genetic effects on gene expression at cell-type resolution using single-cell RNA sequencing.
  • Finds that cell-type-specific eQTLs drive a substantial share of complex-trait heritability.
  • Highlights cell-specific gene regulation as a key mechanism linking genetic variation to traits.
  • Supports more precise interpretation of trait-associated variants by identifying their relevant cell types.
Representative image for Unlocking Multimodal Protein Language Models at Inference Time

Unlocking Multimodal Protein Language Models at Inference Time

Rank 79 · Content 95 · Popularity 42

TL;DR - This paper systematically studies inference-time sampling for multimodal protein language models across three models and four tasks. It finds that task-tailored inference strategies can substantially improve generation quality without updating model parameters.

  • Compares vanilla sampling, task-specific classifier-free guidance, and reward-guided beam search.
  • Examines three levels of inference control: sampling distributions, per-step logits, and parallel generation trajectories.
  • Shows that default inference protocols are often suboptimal and that preferred exploration-exploitation trade-offs vary by task.
  • Reports consistent quantitative gains that raise model performance ceilings and challenge prior conclusions about the underlying models.

Automated prototyping of genetic codes

Rank 77 · Content 90 · Popularity 46

TL;DR - A robotic, cell-free platform rapidly prototypes redesigned genetic codes, allowing proteins to be translated with reassigned codons and non-standard amino acids. This could accelerate genetic-code engineering while avoiding direct modification of living genomes.

  • Combines automation with a cell-free protein translation system.
  • Tests codon reassignments outside living cells.
  • Supports incorporation of non-standard amino acids into proteins.
  • Reduces the need for slower, riskier genome-level engineering during prototyping.

Insights into longevity and virus-driven adaptation from Myotis bat genomes

Rank 73 · Content 85 · Popularity 46

TL;DR - Comparative and functional analyses of Myotis bat genomes identify distinctive adaptations in virus-interacting proteins and longevity-associated pathways. The study connects bats’ responses to viral pressures with their unusually long lifespans.

  • Compares genomes across Myotis bats to characterize evolutionary adaptations.
  • Finds unique patterns of change in proteins that interact with viruses.
  • Identifies adaptations in biological pathways associated with longevity.
  • Links two prominent features of bat biology: viral adaptation and extended lifespan.

LLMs & Foundation Models 2

Representative image for Disentangling Optimization Scale from Preference Scale in DPO

Disentangling Optimization Scale from Preference Scale in DPO

Rank 83 · Content 100 · Popularity 42

TL;DR - This paper shows that DPO’s β parameter conflates preference-noise scaling with optimization step scaling, making policy deviation and loss comparisons difficult to interpret. It proposes a centered-softplus reformulation that separates these effects for more controllable alignment training.

  • At a fixed learning rate, policy KL divergence from the reference is non-monotonic in β: near zero in a small-β dead zone, maximal at an intermediate β, then lower again.
  • Similar DPO loss curves across different β values can correspond to several-fold differences in policy KL divergence.
  • The proposed objective is argmin-equivalent to DPO for β > 0 while allowing preference-noise scale and learning-rate effects to be tuned independently.
  • Its normalized form has a continuous β → 0 limit that becomes a linear preference-margin objective.
Representative image for Understanding Evolution Strategies for LLM Reasoning: Broader Reasoning Coverage than GRPO

Understanding Evolution Strategies for LLM Reasoning: Broader Reasoning Coverage than GRPO

Rank 82 · Content 90 · Popularity 63

TL;DR - This paper finds that Evolution Strategies (ES) provide broader LLM reasoning coverage than GRPO, improving Pass@K while avoiding GRPO’s entropy collapse. A sequential GRPO-ES strategy combines strong Pass@1 performance with greater solution diversity.

  • Verifier-projected Jensen-Shannon diversity across the ES population is theoretically and empirically associated with higher Pass@K.
  • ES improves Pass@1 while achieving higher Pass@K than GRPO, which exhibits entropy collapse.
  • ES gains arise from a sparse subset of large-magnitude parameter updates despite substantial whole-model drift, without necessarily causing catastrophic forgetting.
  • Larger LLMs require smaller ES population sizes, informing more efficient hyperparameter design.

Multimodal & Generative 7

Representative image for PAWBench: How Far Are We from Probabilistically Aligned World Modeling?

PAWBench: How Far Are We from Probabilistically Aligned World Modeling?

Rank 90 · Content 100 · Popularity 68

TL;DR - PAWBench evaluates whether video generators used as world models reproduce the probability distribution of valid physical outcomes, rather than merely generating plausible individual trajectories. Across 50 scenarios and 11 systems, no model consistently recovered both reference probabilities and the full range of valid behaviors.

  • Formalizes “probabilistic alignment” as a distribution-level criterion for stochastic world models.
  • Introduces PAWEval, which converts repeated video rollouts into empirical distributions over physical outcomes.
  • Tests whether language prompts, initial-noise sampling, or model training can reshape predicted outcome distributions.
  • Reveals a significant gap between plausible video generation and distributionally accurate world modeling.
Representative image for Magpie: Real-Time World Renderer for Interactive Games

Magpie: Real-Time World Renderer for Interactive Games

Rank 87 · Content 95 · Popularity 69

TL;DR - Magpie is a real-time generative rendering system that separates deterministic game simulation from model-generated visuals. This architecture could reduce the visual-asset burden for early prototypes while preserving reproducible gameplay rules and interactions.

  • A conventional game engine remains responsible for player actions, world state, scene definitions, and gameplay rules.
  • An independent render server generates visuals from white-box frames produced by the engine.
  • The separation aims to combine generative imagery with stable, designer-controlled gameplay outcomes.
  • The work presents a system-level path for using generative models in interactive, real-time game rendering.

CLAP: Cross-Embodiment Video World Models are Zero-Shot Physical Simulators

Rank 85 · Content 95 · Popularity 61

TL;DR - CLAP is a cross-embodiment, action-conditioned video world model that learns shared physical dynamics from heterogeneous human and robot videos. It enables zero-shot simulation across robot platforms while matching or exceeding leading single-embodiment models in environments such as DROID.

  • Unifies disparate action spaces through end-effector poses, language instructions, and learned latent actions.
  • Uses curriculum learning to first acquire physical priors from unlabeled videos, then ground them in robot action spaces for zero-shot deployment.
  • Supports multiple robot morphologies, including DROID, Bridge, bimanual YAM robots, and G1 humanoids.
  • Few-shot adaptation further improves single-embodiment performance; the authors open-source the code and models.

LeVJEPA: Efficient & Scalable Video Pretraining without the Heuristics

Rank 84 · Content 95 · Popularity 60

TL;DR - LeVJEPA is a self-supervised video pretraining method that uses a single encoder, projector, and collapse-free regularization instead of asymmetric target encoders or pixel reconstruction. It matches or exceeds V-JEPA 2 with 5.6–20.8× less pretraining compute, making video more practical for general-purpose visual representation learning.

  • Uses global/local view invariance with SIGReg, which provides a provable guarantee against representation collapse.
  • Uniform random token dropping both reduces the encoder’s compute load and improves downstream accuracy.
  • At matched total FLOPs, LeVJEPA beats the strongest reported video baseline by 7.6 ImageNet-1K points while remaining competitive on motion-centric tasks.
  • Block-causal attention preserves accuracy and builds temporal ordering directly into the encoder.
Representative image for Code World Model: Coding Agent as World Brain

Code World Model: Coding Agent as World Brain

Rank 84 · Content 90 · Popularity 70

TL;DR - Code World Model uses a coding agent to maintain executable, persistent world state while a conditioned video model renders the resulting scenes. This separation could enable more coherent, rule-consistent, and open-ended simulated worlds than models that learn dynamics solely from video.

  • A language-model coding agent reasons about events, updates state, and generates executable code governing world evolution.
  • A proxy representation encodes frame-level spatiotemporal constraints and is compiled into video that conditions the visual generator.
  • The authors construct aligned proxy-observation datasets from gameplay and real-world videos.
  • Fine-tuned MiniMax-H3 follows proxy specifications in simple interactive worlds while retaining detailed visuals and dynamics.

LongVU-TTT: Causal Test-Time Training for Visual Resampling in Long Video Understanding

Rank 83 · Content 100 · Popularity 42

TL;DR - LongVU-TTT introduces a causal test-time-training resampler that adapts visual features to each long video before compressing them for a multimodal LLM. It processes up to 512 frames into 128 LLM frames while retaining selected evidence needed for long-range reasoning.

  • Grouped 2D convolutional fast weights aggregate temporal context between the vision encoder and LLM.
  • A hybrid uniform and change-aware selector explicitly preserves frames because fast-weight benefits weaken as evidence becomes more distant.
  • TTT-Conv outperforms TTT-MLP by up to 2.12 points and bidirectional Mamba2 by up to 3.04 points on MLVU under controlled conditions.
  • The approach is competitive across five video-understanding benchmarks and stronger than attention-based and fixed-state recurrent resamplers across three.

Retrieval Heads Meet Vision: Uncovering How VLMs Locate and Extract Visual Information

Rank 78 · Content 95 · Popularity 37

TL;DR - The paper identifies Visual Retrieval Heads (VRHs), a small subset of attention heads that enable vision-language models to connect text descriptions to relevant image regions. Their causal importance and transfer across tasks and related architectures reveal a shared, sparse mechanism for visual grounding.

  • VRHs comprise roughly 1.7–2.6% of attention heads across 11 VLMs and five referring-expression benchmarks.
  • Masking the top 20 VRHs reduces grounding accuracy by up to 80 percentage points, whereas masking random heads has little effect.
  • Heads discovered through bounding-box prediction remain causal for attribute, spatial, counting, and visual-math tasks.
  • VRHs preserve output formatting while disrupting localization and transfer between VLMs sharing an LLM backbone despite differences in their visual components and instruction tuning.

Efficiency & Systems 3

Representative image for Spectral Allocation: Why Muon Outperforms Adam, and How to Improve Muon

Spectral Allocation: Why Muon Outperforms Adam, and How to Improve Muon

Rank 88 · Content 95 · Popularity 71

TL;DR - Spectral analysis suggests Muon accelerates LLM pretraining by allocating updates more effectively than Adam across singular directions. The proposed Spectral-Aware Muon further exploits tolerant directions, reducing the training tokens needed to reach a target validation loss.

  • Transformer loss landscapes exhibit a stable anisotropic profile: a volatile spectral head requires small steps, while the tolerant bulk supports much larger ones.
  • Muon’s uniform scaling explains its advantage over Adam and SGD but still underuses the bulk directions.
  • SAMuon amplifies the bulk using a static spectral prior; SAMuon-lite approximates this with rank-one power iteration and near-zero wall-clock overhead.
  • Across 124M–1B parameter models, SAMuon used 13.3%–24.0% fewer tokens than Muon to reach the same validation loss.

Puro-2B: Poor Lab's Qwen2-1.5B Trained on RTX 5090 within $5090

Rank 86 · Content 95 · Popularity 66

TL;DR - Puro-2B is an open recipe for pretraining 2B-parameter language models from scratch on consumer RTX 5090 GPUs, reaching near-Qwen2.5-1.5B performance for under $6,900. It aims to make controlled LLM pretraining research substantially more accessible.

  • Models were trained with FP8 precision on as many as 1.4 trillion tokens.
  • Cost reductions combine consumer hardware, low-precision training, hyperball optimization, curriculum model averaging, and a tailored data recipe.
  • A fitted cost-scaling law estimates that roughly $4,400 is sufficient to match Qwen2-1.5B under the authors’ evaluation protocol.
  • The data, code, model weights, and complete training recipe are released under Apache 2.0.

TwinKV: A Composable Repair Pass for KV Cache Eviction via Pairwise Key Redundancy

Rank 83 · Content 100 · Popularity 42

TL;DR - TwinKV is a training- and attention-free repair pass that improves existing KV-cache eviction policies by swapping retained redundant tokens for evicted tokens lacking surviving duplicates. It can improve long-context inference under fixed memory budgets, though gains vary by model, policy, compression ratio, and task.

  • A leave-one-out analysis found essentially no correlation between attention magnitude and a token’s causal contribution to an answer (Spearman ρ = -0.004).
  • TwinKV detects pairwise key redundancy, replacing redundant retained “donors” with evicted “orphans” while preserving the original policy’s cache budget and scoring rule.
  • Across LongBench, LooGLE, and RULER, it improved many configurations for several eviction policies; benefits were generally smaller at looser compression and for a strong adaptive baseline near its performance ceiling.
  • Few-shot classification exemplars were a consistent failure case where TwinKV did not help either evaluated model.

AI in Education 1

Better answers, broader thinking: What students gain from ChatGPT and critical-thinking training

Rank 68 · Content 75 · Popularity N/A

TL;DR - A randomized study involving more than 1,000 students investigates how ChatGPT and critical-thinking training affect originality and performance on a real-world university assignment. The provided excerpt does not report the study’s findings.

  • Uses a randomized study design with over 1,000 students.
  • Evaluates ChatGPT alongside explicit critical-thinking training.
  • Examines student performance and originality in an authentic university task.
  • No quantitative results or conclusions are included in the provided content.

Ancient Symbiosis 1

Animal-microbe partnerships date back to the dawn of complex life

Rank 59 · Content 65 · Popularity 46

TL;DR - Geochemical evidence suggests that worm-like Ediacaran organisms might have benefited from symbiotic relationships with bacteria. If confirmed, such animal–microbe partnerships arose near the dawn of complex life.

  • The evidence comes from geochemical clues rather than direct observation.
  • The organisms studied date to the Ediacaran period, before the Cambrian diversification of animal life.
  • The findings imply that bacterial symbiosis might have supported some of Earth’s earliest complex organisms.
  • The provided summary does not specify the chemical markers, organisms, or proposed biological benefits involved.

Astronomy AI 1

Plasma-jet movie is astronomy’s summer blockbuster

Rank 73 · Content 85 · Popularity 46

TL;DR - An AI-driven algorithm transformed just 116 images of the active galaxy 3C 345 into a detailed video of its plasma jets. The work shows how AI can reconstruct dynamic astronomical phenomena from sparse observational data.

  • The source data comprise only 116 images of 3C 345.
  • The generated video depicts plasma jets emerging from the galaxy’s centre.
  • The provided summary does not specify the algorithm, reconstruction method, or validation results.

Computational Neuroscience 2

Granule cells reorient cortical trajectories to separate contexts

Rank 69 · Content 70 · Popularity 68

TL;DR - Simultaneous imaging in mice learning two skills showed that premotor-cortex activity trajectories generalize across contexts, whereas cerebellar granule-cell trajectories coherently reorient to distinguish them. The findings suggest a neural mechanism that balances shared skill representations with context separation.

  • Researchers simultaneously imaged premotor cortex and cerebellar granule cells during parallel skill learning.
  • Cortical trajectories generalized between the two learned contexts.
  • Granule-cell trajectories reoriented away from one another, producing context-specific separation.
  • This complementary coding may enable generalization without conflating distinct contexts.

Endocannabinoids facilitate reward engagement through retrograde gain control

Rank 63 · Content 70 · Popularity 46

TL;DR - This Nature study identifies dynamic endocannabinoid release as a retrograde gain-control mechanism in a thalamostriatal circuit that promotes engagement during reward seeking. It clarifies how neuromodulatory signaling helps translate reward motivation into behavior.

  • Endocannabinoids act as retrograde signals within a thalamostriatal circuit.
  • Their dynamic release regulates circuit gain during reward-seeking behavior.
  • This mechanism facilitates behavioral engagement with potential rewards.
  • The findings connect circuit-level neuromodulation to motivated behavior.

Evolutionary Paleontology 1

Amphibious stem-insect sheds light on colonization of land

Rank 66 · Content 75 · Popularity 46

TL;DR - A fossil restudy using cross-polarized light imaging and phylogenetic reconstruction identifies Chosha praecursor as a probable early-diverging insect. The finding helps narrow the longstanding “hexapod gap” in the fossil record and clarify how insects colonized land.

  • The work re-examines a difficult fossil with cross-polarized light imaging.
  • Phylogenetic reconstruction places Chosha praecursor near the early divergence of insects.
  • Its amphibious characteristics may illuminate the transition of hexapods from aquatic to terrestrial environments.
  • The fossil provides evidence within a poorly documented interval of early hexapod evolution.

LLM Evaluation 1

Anchoring Bias in LLM-as-a-Judge Systems: Prior Scores Compromise Evaluation Independence

Rank 79 · Content 95 · Popularity 42

TL;DR - Prior scores embedded as metadata can anchor LLM-as-a-Judge systems, undermining the assumed independence of successive evaluations. The effect spans numerical scoring and categorical decisions, and common prompting mitigations do not eliminate it.

  • Seven of eight evaluated models showed a statistically significant overall anchoring effect across 185,271 successful evaluations, with absolute Cohen’s (d) reaching 0.71.
  • Token-level probes suggest a threshold-like response: adding anchored metadata sharply shifts score probabilities, while varying below-threshold anchor values has less impact.
  • On human-labeled industry data, anchoring prevented 48% of error corrections and flipped 10.18% of correct judgments to an assigned wrong label.
  • Chain-of-Thought and metadata-disregard warnings did not reduce the total effect, highlighting the need for model- and task-specific mitigation validation.

Marine Microbiology 1

Synergistic degradation of fucoidans in the ocean

Rank 65 · Content 75 · Popularity 43

TL;DR - A Nature study finds that efficient oceanic fucoidan degradation relies on complementary bacterial guilds that cooperatively break down backbone and side-chain sugars. This conserved, globally relevant mechanism helps explain microbial control of marine carbon cycling.

  • Different bacterial guilds perform complementary steps in fucoidan degradation.
  • Cooperation targets both the polysaccharide backbone and its side-chain sugars.
  • The mechanism appears conserved and relevant across global ocean environments.
  • These microbial interactions influence how fucoidan-derived carbon is processed in marine ecosystems.

Metabolic Thermogenesis 1

Representative image for Sci Adv | 邓成团队揭示蜥蜴GCGR受体的非经典产热机制

Sci Adv | 邓成团队揭示蜥蜴GCGR受体的非经典产热机制

Rank 57 · Content 60 · Popularity 50

TL;DR - A Science Advances study identifies constitutively active glucagon receptors (GCGRs) in lizard liver as a molecular driver of cold-induced thermogenesis. The finding revises the view that ectotherms rely almost entirely on external heat and reveals a mechanism for adaptation to cold environments.

  • Cold exposure increased hepatic GCGR expression in thermoregulating lizard species, correlating positively with their ability to maintain body temperatures above ambient levels.
  • Lizard GCGR activates Gs–cAMP signaling without glucagon, promoting glycogen and lipid breakdown, lipid oxidation, and expression of thermogenic genes such as FGF21.
  • GCGR knockdown or inhibition lowered lizard body temperature and metabolic gene expression, supporting the pathway’s necessity.
  • Expressing bearded-dragon GCGR increased cold-exposed lizards’ and mice’s body temperature and metabolic rate, including in glucagon-deficient mice, demonstrating ligand-independent activity.

Scientific Imaging AI 1

Video reconstruction of variable VLBI observations with neural fields

Rank 88 · Content 95 · Popularity 73

TL;DR - The kine neural reconstruction algorithm turns variable very long baseline interferometry observations into high-resolution, time-continuous videos. This enables direct measurement of instantaneous plasma velocities and more detailed study of relativistic astrophysical jets.

  • Uses neural fields to reconstruct dynamic VLBI observations as continuous video.
  • Produces high-resolution representations that vary continuously over time.
  • Supports direct measurement of instantaneous plasma motion.
  • Enables detailed kinematic analysis of relativistic jets.

Structural Biology 1

Primate-specific regulation of the human glycosphingolipid gatekeeper UGCG

Rank 78 · Content 80 · Popularity 73

TL;DR - Cryogenic electron microscopy structures reveal how full-length human UGCG, a key regulator of glycosphingolipid diversity, catalyses its reaction. The findings identify a metal-independent mechanism driven by an arginine network.

  • Reports cryo-EM structures of full-length human UGCG.
  • UGCG controls the scale and composition of glycosphingolipid diversity.
  • The structures indicate that catalysis does not require a metal cofactor.
  • An arginine network drives the proposed catalytic mechanism.

Targeted Drug Delivery 1

A binding-to-release strategy for targeted anticancer drug delivery

Rank 76 · Content 90 · Popularity 43

TL;DR - This Nature study introduces a binding-to-release drug conjugate strategy that releases anticancer payloads at targeted tumours without requiring cellular internalization. The approach could improve tumour specificity and efficacy while expanding the range of addressable therapeutic targets.

  • Payload release is triggered by target binding rather than uptake into cells.
  • Avoiding the internalization requirement broadens potential targets beyond those suitable for conventional drug conjugates.
  • The strategy is reported to improve tumour-specific delivery and therapeutic efficacy.
  • The provided summary does not include quantitative efficacy or safety results.
Top highlights — Industry & News

LLM Agents 8

Introducing the Admin plugin for ChatGPT Work and Codex

Rank 71 · Content 80 · Popularity N/A

TL;DR - OpenAI introduced an Admin plugin for ChatGPT Work and Codex that lets administrators inspect workspace usage and perform common management tasks through admin requests.

  • Analyzes workspace usage.
  • Manages members, permissions, and usage limits.
  • Enables administrators to act on operational requests within ChatGPT Work and Codex.
  • The provided description does not specify implementation details, integrations, or availability.
Representative image for 中国飞鹤×火山引擎:436个智能体走进乳业生产一线

中国飞鹤×火山引擎:436个智能体走进乳业生产一线

Rank 64 · Content 70 · Popularity N/A

TL;DR - Chinese dairy producer Feihe deployed 436 production-focused AI agents on ByteDance’s HiAgent platform, embedding them into equipment maintenance, process optimization, and workforce management. Reported deployments show how agentic systems can deliver measurable industrial gains when connected to operational data and workflows.

  • HiAgent provides a shared foundation for model access, knowledge governance, workflow orchestration, permissions, and agent operations across more than 10 factories.
  • An AI equipment-management system deployed at nine factories reportedly cut average fault-recovery time from 104 to 47 hours and repeat failures from 34% to 8%.
  • A membrane-cleaning agent uses Doubao models and production databases for monitoring and alerts, reportedly saving over RMB 500,000 in annual purchasing, 144,000 tonnes of water, and more than RMB 3 million in equipment wear.
  • A workforce-management agent built with TRAE, HiAgent, and Arkclaw reduced process steps from 15 to five and increased efficiency by more than threefold.
Representative image for 工业Agent不是“套壳”大模型!西门子百年经验灌进工业AI

工业Agent不是“套壳”大模型!西门子百年经验灌进工业AI

Rank 64 · Content 70 · Popularity N/A

TL;DR - Siemens is expanding industrial AI through its Eigen Engineering Agent, ICX orchestration software, and Xcelerator ecosystem. The strategy matters because it embeds agents into real engineering systems and governed workflows rather than merely wrapping general-purpose LLMs.

  • Eigen can parse ECAD files, detect configuration conflicts, generate PLC tags and projects, and execute end-to-end engineering tasks; reported deployments showed 2–5× faster execution and up to 50% higher engineering efficiency.
  • ICX connects enterprise and operational systems such as PLM, ERP, MES, CRM, and OT data while orchestrating models, agents, skills, and multi-step workflows with traceability.
  • Xcelerator provides reusable industrial skills, RAG-based knowledge services, agent-development tooling, and a marketplace for distributing validated third-party and Siemens solutions.
  • Siemens aims to scale industrial agents by combining its automation expertise and industrial data context with partners’ domain-specific capabilities across manufacturing sectors.
Representative image for 阿里发布全新Qoder ,面向所有人的智能体工作台来了

阿里发布全新Qoder ,面向所有人的智能体工作台来了

Rank 61 · Content 65 · Popularity N/A

TL;DR - Alibaba launched a redesigned Qoder as a task-centric agent workspace that turns natural-language goals into development, prototyping, and data-processing workflows. It broadens coding-agent capabilities beyond developers through extensive integrations, automatic model routing, and support for long-running tasks.

  • Qoder includes multiple frontier models, including Qwen3.8-Max, with Auto routing that balances task quality, speed, and cost.
  • More than 40 connectors, 70 plugins, and 20,000 skills link repositories, project-management platforms, cloud services, and internal tools to agent workflows.
  • Programming and general-purpose modes serve different user groups, while Plan, Goal, and side-task features structure, execute, and verify complex work.
  • Real-time voice interaction lets users initiate, refine, monitor, or take over tasks without repeatedly rewriting complete prompts.
Representative image for 大厂AI To B大战,这回战场为什么是办公?

大厂AI To B大战,这回战场为什么是办公?

Rank 61 · Content 65 · Popularity N/A

TL;DR - Tencent, Alibaba, and ByteDance are shifting AI commercialization toward enterprise office agents after consumer chatbots struggled to monetize and China’s coding-assistant market proved limited. The contest matters because existing workplace ecosystems, enterprise data, and cloud infrastructure could turn agent usage into recurring B2B revenue—but inference costs and sustained customer willingness to pay remain unresolved.

  • Tencent’s WorkBuddy uses product-led growth: attract individual professionals first, then expand into team and enterprise deployments.
  • Alibaba’s Qwen Office combines QoderWork, Wukong, and MuleRun, leveraging DingTalk’s enterprise relationships and Alibaba Cloud’s data, deployment, and sales channels.
  • ByteDance is integrating Doubao’s AI capabilities, Feishu’s workplace context, and Volcano Engine’s cloud commercialization and go-to-market operations.
  • Profitability depends on embedding agents into real workflows while ensuring token- or credit-based revenue covers rising model and compute costs.
Representative image for 基元律动累计融资数千万美元,推出“中国版OpenRouter”

基元律动累计融资数千万美元,推出“中国版OpenRouter”

Rank 50 · Content 50 · Popularity N/A

TL;DR - TokenRhythm raised tens of millions of dollars and launched the public beta of a China-focused, OpenRouter-like multi-model API platform. Its broader goal is a routing layer that dynamically coordinates models during agent execution to improve cost and performance.

  • One API key provides OpenAI- and Claude-compatible access to multiple models, with unified billing, usage statistics, logs, and model selection.
  • The company reports 54,000 users and more than 500 billion tokens processed daily, with enterprise proof-of-concept projects underway.
  • Its Routing Harness selects, switches, and combines models based on task stage, budget, and runtime conditions rather than merely providing a model gateway.
  • TokenRhythm says OpenSquilla’s query-level routing cut PinchBench costs to about one-ninth of task-level routing at comparable accuracy; a domestic-model ensemble reportedly outperformed Fable 5 on DRACO at roughly one-third the cost.
Representative image for 从技术验证到业务落地:智能体的下一步该怎么走

从技术验证到业务落地:智能体的下一步该怎么走

Rank 50 · Content 50 · Popularity N/A

TL;DR - A Shenzhen industry forum examined how AI agents can move from demos into dependable enterprise deployments. Speakers emphasized context and memory infrastructure, controlled knowledge engineering, low-code orchestration, and delivery of usable business outputs.

  • Long-running, multi-step agents need engineered memory and context management to remain coherent and consistent.
  • Enterprise adoption depends on overcoming hallucinations and misuse through granular control of knowledge structures.
  • Visual orchestration, multimodal perception, private deployment, and end-to-end governance can lower implementation and operational barriers.
  • Vertical agents increasingly compete on the quality of completed deliverables—not merely their conversational ability.
Representative image for 百度搭子宣布一揽子升级,提出“交付即惊艳”专业办公标准

百度搭子宣布一揽子升级,提出“交付即惊艳”专业办公标准

Rank 47 · Content 45 · Popularity N/A

TL;DR - Baidu upgraded its DuMate AI office agent across personal and enterprise editions, adding specialized workflows, multimodal deliverables, app development, and traceable data analysis. The release emphasizes production-ready outputs rather than isolated generation steps.

  • The new Harness engine handles task planning, tool calls, and execution; Baidu reports over 99% task completion on relevant tasks with 30% lower credit consumption.
  • Specialized suites cover end-to-end media production and financial research, while enterprise offerings provide 15 suites and 96 skills across four business function areas.
  • Integrated workbenches can generate and iteratively modify web apps, mini-programs, or mobile apps, and analyze business data without manual table joins or SQL.
  • DuMateBench launches as an open benchmark for real-world agent delivery, initially covering more than 200 multi-step, multi-tool office tasks.

Bioinformatics AI 2

Representative image for 第四届世界华人计算生物学大会 | 墙报征集

第四届世界华人计算生物学大会 | 墙报征集

Rank 29 · Content 20 · Popularity N/A

TL;DR - The Fourth World Chinese Computational Biology Conference is soliciting poster submissions. The provided content contains only the title and no details on topics, deadlines, eligibility, or submission requirements.

  • This is a conference participation announcement rather than a research result.
  • The event focuses broadly on computational biology, aligning with bioinformatics.
  • No specific technical findings, methods, or accepted research areas are included in the available text.
Representative image for 生信还是那个生信;但这一次,有AI和没有AI,是两代人(9月线上直播课)

生信还是那个生信;但这一次,有AI和没有AI,是两代人(9月线上直播课)

Rank 26 · Content 15 · Popularity N/A

TL;DR - 生信技能树发布9月线上生物信息学培训课程,将AI编程助手和智能体工具系统性融入R、Linux、转录组及单细胞分析教学。课程重点是用AI辅助代码生成、调试、文献解读和结果解释,而非发布新的研究成果。

  • 生信入门班覆盖R/Linux基础、RNA-seq上下游分析、差异与富集分析、可变剪切、免疫组库和单细胞工作流。
  • 数据挖掘班侧重转录组与单细胞下游分析、WGCNA、机器学习分类与生存模型,以及论文分析复现。
  • AI环节涉及GitHub Copilot、Codex、模型切换工具和R智能体aisdk,用于排错、脚本生成、绘图复现及代码迁移。
  • 课程还展示用AI辅助细胞注释、通路与通讯网络解读、文献检索、实验方案生成和模拟审稿意见。

LLMs & Foundation Models 1

Granite 4.2 LLMs: How They're Built

Rank 68 · Content 75 · Popularity N/A

TL;DR - Hugging Face hosts an IBM Granite post about how the Granite 4.2 large language models are built. Because no article content was provided, specific architectural choices, training methods, and results cannot be verified.

  • The title indicates a technical overview of the Granite 4.2 model family.
  • The item appears to focus on model construction rather than a standalone research publication.
  • No benchmarks, model specifications, datasets, or release details are available in the provided content.

Multimodal & Generative 5

Representative image for 神秘「牛来」模型果然是智谱!GLM首个原生多模态,还用的国产卡

神秘「牛来」模型果然是智谱!GLM首个原生多模态,还用的国产卡

Rank 64 · Content 70 · Popularity N/A

TL;DR - Zhipu released and open-sourced GLM-5.3 Flash, its first native multimodal GLM-5 model, previously tested anonymously as Ox Alpha. It targets affordable long-running agentic and visual tasks while serving production traffic on Chinese accelerator hardware.

  • The 320B-parameter mixture model activates 18B parameters across 45 layers and was pretrained on 30T multimodal tokens.
  • A hybrid linear-and-sparse attention architecture supports 1M-token contexts while reportedly cutting attention computation by 3.01× and KV-cache size by 4.44× versus GLM-5.3.
  • Demonstrations covered video understanding and editing, UI generation from design images, interactive 3D webpages, and a 12-hour autonomous Blender workflow.
  • Zhipu says its disaggregated encode-prefill-decode serving architecture tripled end-to-end performance on domestic chips; model weights, APIs, and coding integrations are now available.

Gemini Omni 1.1 Flash lets you build with more control

Rank 61 · Content 65 · Popularity N/A

TL;DR - Google DeepMind announced Gemini Omni 1.1 Flash, positioning it as a model that gives developers more control when building applications. Because only the title and metadata are provided, specific capabilities and improvements cannot be verified.

  • The release belongs to Google DeepMind’s Gemini model family.
  • “Flash” suggests a model variant intended for responsive or efficient applications, though no performance data is provided.
  • The announcement emphasizes increased developer control, but the available material does not specify the relevant controls or APIs.

Intelligent transcription with Gemini 3.5 Transcribe

Rank 57 · Content 60 · Popularity N/A

TL;DR - Google DeepMind announced Gemini 3.5 Transcribe for more intelligent speech-to-text transcription. The limited item text provides no details about its architecture, availability, performance, or supported features.

  • Focuses on converting spoken audio into text.
  • Positions Gemini 3.5 Transcribe as an improvement in transcription intelligence.
  • No benchmarks, technical specifications, or comparisons are provided.

ECCV 2026 倒计时 12 天:LeCun 压轴、中国 71M 模型、CMU 一键修 3D,顶会三大爆点抢先看

Rank 54 · Content 55 · Popularity N/A

TL;DR - ECCV 2026’s newly announced program highlights world models, autonomous driving, embodied perception, and efficient real-time generation. Early project previews include a 71M-parameter portrait-generation model and a general video model for correcting artifacts across multiple 3D representations.

  • Keynotes feature Yann LeCun, Wayve chief scientist Jamie Shotton, and Kristen Grauman, spanning foundation models, driving world models, video, and embodied perception.
  • StreamTalk uses one 71M-parameter model for real-time avatars, telepresence, and interactive NPCs, emphasizing lightweight deployment.
  • CMU’s FixAnything applies a unified video model to repair rendering artifacts from 3D Gaussian splats, meshes, and sparse point clouds.
  • The conference also includes workshops on safe world models, medical video, and related vision topics, plus a physical-AI robotics demonstration.
Representative image for 开放式AI耳机,韶音要杀死比赛了

开放式AI耳机,韶音要杀死比赛了

Rank 50 · Content 50 · Popularity N/A

TL;DR - Shokz launched the OpenFit 2 AI open-ear headphones, combining all-day audio capture with Qwen-based transcription, translation, and structured meeting summaries. The product targets professional communication rather than broad AI functionality, positioning open-ear hardware as a practical always-on voice interface.

  • Shokz says it fine-tuned Qwen for professional speech using samples from more than 1,400 real-world scenarios and an evaluation framework spanning 13 dimensions and over 60 metrics.
  • The headphones support four translation modes covering 30 languages and 19 dialects, plus transcription optimized for 12 industries and 19 industry-specific summary templates.
  • Open-ear construction preserves environmental awareness and supports extended wear, with claimed recording time of roughly 8 hours, 11-hour earbud battery life, and 48 hours including the charging case.
  • The Shokz app generates summaries, action items, and mind maps, while recordings can be initiated from an earbud, phone, or closed charging case.

Efficiency & Systems 6

Representative image for 全新架构,极致性价比!阿里千问Qwen3.8-Flash发布并开源

全新架构,极致性价比!阿里千问Qwen3.8-Flash发布并开源

Rank 71 · Content 80 · Popularity N/A

TL;DR - Alibaba released and open-sourced Qwen3.8-Flash, a multimodal mixture-of-experts model designed to deliver strong agentic and reasoning performance at substantially lower training and inference costs. Its new architecture is also positioned as a precursor to Qwen4.

  • The model has 125B Transformer parameters but activates only 6B per token, supplemented by 51B parameters of N-gram embeddings.
  • Its architecture combines Qwen Sparse Attention with GDN, gated residual pathways, and training-system optimizations; Alibaba reports over 8× acceleration in high-cache-hit, 1M-token contexts.
  • Alibaba claims nearly 90% lower training cost than Qwen3.7-Plus, with API pricing of RMB 1 per million input tokens and RMB 3 per million output tokens.
  • Reported benchmarks show strengths in agentic coding, tool use, long-horizon professional tasks, mobile interaction, and visual reasoning, though the article provides company-reported comparisons rather than independent validation.
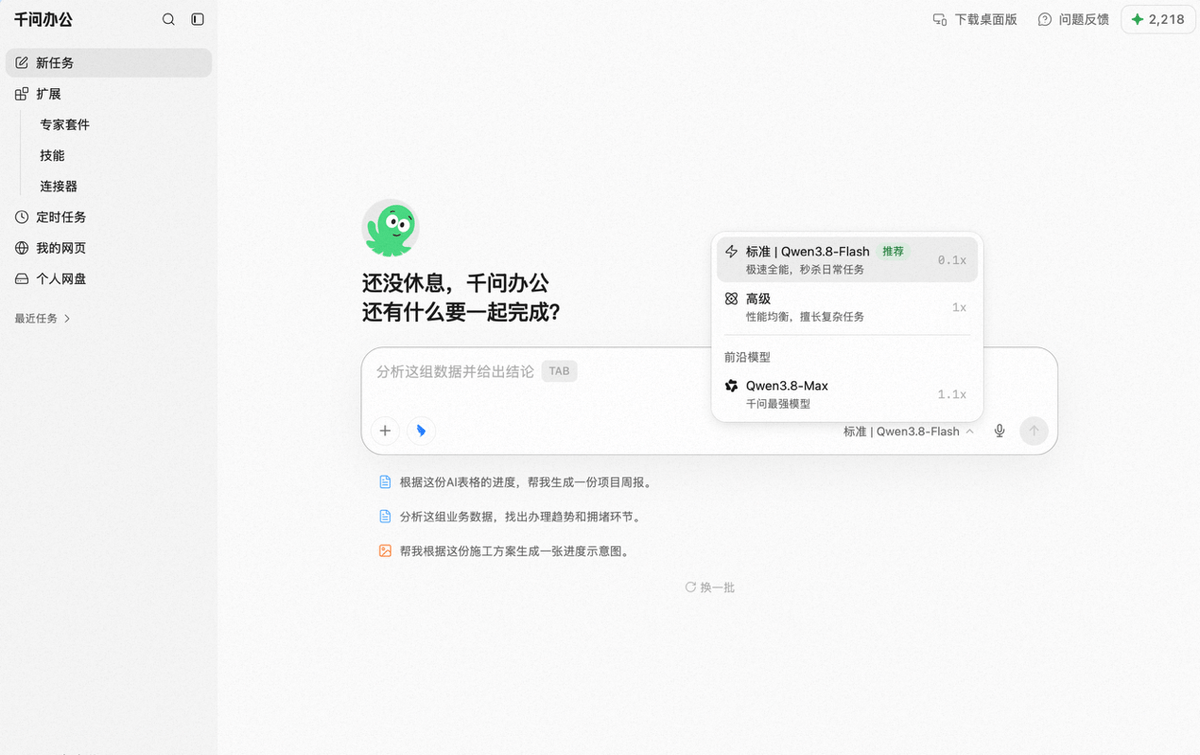
Representative image for 千问办公首发上线Qwen3.8-Flash,生成速度提升100%,Token消耗减少75%

千问办公首发上线Qwen3.8-Flash,生成速度提升100%,Token消耗减少75% 🔗 2 sources

Rank 68 · Content 75 · Popularity N/A

TL;DR — 千问办公上线以办公场景优化版 Qwen3.8-Flash 驱动的标准模式;据官方内部真实办公任务测试,其生成速度提升约 100%,平均 Token 消耗减少 75%,旨在兼顾智能体能力、延迟与成本。

  • Qwen3.8-Flash 被描述为采用新架构、总参数达数千亿级,千问称其性能超过 Claude Opus 4.6。
  • 办公专用版本重点强化了多步骤规划、工具选择和上下文压缩能力。
  • 性能提升不仅来自模型调优,也结合了推理优化与定制化智能体框架,以提高吞吐并降低资源消耗。
  • 千问办公预计标准模式可处理 95% 的日常办公任务,其余 5% 的复杂工作由高级模式承担。
  • 速度与 Token 效率数据均源于千问内部的真实办公场景测试。

注: 量子位更强调模型架构、参数规模及性能定位,雷峰网则更侧重模型、智能体框架与推理栈的协同优化。

Representative image for 像素级对标?智谱、Kimi 底层参数「撞衫」背后,藏着线性注意力的黄金窗口

像素级对标?智谱、Kimi 底层参数「撞衫」背后,藏着线性注意力的黄金窗口

Rank 68 · Content 75 · Popularity N/A

TL;DR - Zhipu’s GLM-5.3-Flash and Kimi K3 use highly similar KDA linear-attention configurations, including a gate_lower_bound of -5. The convergence highlights a narrow engineering sweet spot for stable, cost-efficient long-context inference rather than, by itself, evidence of copying.

  • KDA compresses history into a fixed-size state matrix, avoiding the growing KV-cache costs of conventional Softmax attention.
  • The -5 gate floor retains roughly 0.67% of old state, balancing numerical stability and long-term recall; higher values risk information buildup, while lower values risk excessive forgetting.
  • GLM-5.3-Flash combines KDA linear attention, DeepSeek-style sparse attention, and manifold-constrained hyper-connections to reduce inference costs.
  • Adding the gate constraint during later training may accelerate adoption of proven practices, but could cause subtle memory-distribution shifts in extreme long-context workloads.

The full stack behind abundant intelligence

Rank 64 · Content 70 · Popularity N/A

TL;DR - OpenAI CFO Sarah Friar describes how coordinated advances across chips, compute infrastructure, models, and products can compound to make AI more useful, scalable, and affordable.

  • Frames AI progress as a full-stack effort rather than solely a product of model improvements.
  • Highlights chips and compute as foundations for scaling access to intelligence.
  • Connects infrastructure and model advances to lower costs and more capable products.
  • The provided content does not include specific architectures, benchmarks, or cost figures.
Representative image for 商汤大装置支撑智谱 GLM-5.3-Flash上线,国产异构助力前沿智能进入普惠时代

商汤大装置支撑智谱 GLM-5.3-Flash上线,国产异构助力前沿智能进入普惠时代

Rank 57 · Content 60 · Popularity N/A

TL;DR - Zhipu launched and open-sourced GLM-5.3-Flash, a 320B-parameter mixture-of-experts multimodal model, using SenseTime’s domestically powered heterogeneous inference infrastructure. The deployment suggests Chinese accelerator clusters can support frontier-model inference at large scale with competitive cost and efficiency.

  • GLM-5.3-Flash activates 18B of its 320B parameters and scored 57 on the Artificial Analysis Intelligence Index, matching Claude Opus 4.8 according to the article.
  • Pre-release testing under the Ox-Alpha alias reportedly processed 62 trillion tokens on domestic chips through OpenCode and OpenRouter.
  • SenseTime says system-level optimizations tripled end-to-end serving performance over the initial baseline, bringing hardware efficiency and per-token cost close to mainstream NVIDIA GPUs.
  • Its heterogeneous inference approach assigns different inference stages to suitable chip architectures, reportedly delivering 1.25× the price-performance of NVIDIA H-series systems and 2.5× the token capacity of domestic homogeneous inference at equal cost.
Representative image for 中科通量推出OmniMate BOX,以"边缘智算主机+存量屏幕"模式降低AI数字员工落地门槛

中科通量推出OmniMate BOX,以"边缘智算主机+存量屏幕"模式降低AI数字员工落地门槛

Rank 54 · Content 55 · Popularity N/A

TL;DR - 中科通量推出轻量版AI数字员工OmniMate BOX,以边缘智算主机连接现有显示屏,在本地运行大模型与数字人服务。其即插即用、无需外网的设计旨在降低线下网点的部署成本和数据合规风险。

  • 采用“边缘智算主机+音视频外设+存量显示终端”的分体式架构,通过HDMI适配电视、广告机、会议屏和触控屏。
  • 搭载国产RISC-V平台、12核CPU、INT8 200 TOPS算力及最高128GB LPDDR5 ECC统一内存。
  • 大模型推理、数字人生成、语音识别和视觉感知均在本地闭环运行,支持企业知识库及内网内容更新。
  • 面向银行、通信、零售和政务等场景的标准化咨询与引导,可感知客户靠近并在广告播放和交互服务间自动切换。

AI Coding Tools 1

How loveholidays is making everyone a builder with Codex

Rank 50 · Content 50 · Popularity N/A

TL;DR - OpenAI highlights how travel company loveholidays uses Codex to broaden software development across its business and accelerate the path from ideas to products. The supplied content does not provide implementation details or measured results.

  • Codex is positioned as a tool that enables more employees to participate in building software.
  • The initiative aims to make product development faster and more accessible across teams.
  • No specific workflows, technical architecture, or performance metrics are included in the provided excerpt.

AI Content Detection 1

Daily briefing: Celebrating Dolly Parton’s contributions to science

Rank 38 · Content 35 · Popularity 46

TL;DR - Nature’s daily briefing highlights Dolly Parton’s support for early Moderna vaccine research, alongside coverage of depression and efforts to detect low-quality AI-generated content. The provided excerpt offers no technical findings or performance data.

  • Parton helped fund Moderna’s early-stage vaccine research through philanthropy.
  • The briefing covers research into the causes and treatment of depression.
  • It also notes that AI-detection tools are being used to counter AI-generated “slop.”
  • No specific detection methods, benchmarks, or study results are included in the excerpt.

AI Evaluation 1

Representative image for Piloting the world's first double-blind AI evaluations

Piloting the world's first double-blind AI evaluations

Rank 75 · Content 85 · Popularity N/A

TL;DR - Google DeepMind announced a pilot of what it describes as the world’s first double-blind AI evaluations. Based only on the supplied title, the initiative appears intended to reduce bias in how AI systems are assessed; no methodology or results are provided.

  • Uses a double-blind evaluation framework in which relevant identities are concealed from evaluators and participants.
  • Targets potential bias and conflicts of interest in AI assessment.
  • The provided content does not specify evaluated models, benchmarks, protocols, participants, or findings.

AI Industry Roundup 1

Representative image for 赚翻了!董宇辉等大主播出走后,东方甄选净利润反而暴涨86倍;字节将推统一办公品牌「豆包工作」;宇树跌至全球人形机器人市值榜第二

赚翻了!董宇辉等大主播出走后,东方甄选净利润反而暴涨86倍;字节将推统一办公品牌「豆包工作」;宇树跌至全球人形机器人市值榜第二

Rank 40 · Content 35 · Popularity N/A

TL;DR - A broad technology-news roundup highlights AI product consolidation, model updates, healthcare deployments, robotics financing, and corporate investment. Key developments include ByteDance unifying workplace AI under “Doubao Work,” Alibaba’s liver-cancer detection model reporting prospective clinical results, and continued expansion in embodied AI.

  • ByteDance is reportedly merging TRAE and Coze teams into Doubao while retaining TRAE IDE and CLI as Doubao-branded coding products.
  • Alibaba’s DAMO LiON CT model reportedly identified 15 previously missed malignant liver tumors during a two-month prospective clinical trial; the associated study appeared in Nature Medicine.
  • Tencent is reorganizing its AI-gaming group around multimodal generation, video world models, and agents, with potential expansion from about 100 to 400–500 employees.
  • Robotics activity remains strong: XPeng’s humanoid-robotics unit raised over $900 million, while NIO is backing a new physical-AI and embodied-intelligence venture.

AI Infrastructure 1

Representative image for 突发!Hugging Face 要卖身

突发!Hugging Face 要卖身

Rank 57 · Content 60 · Popularity N/A

TL;DR - Hugging Face is reportedly exploring a sale at a valuation of $13 billion or more, although no deal has been reached. A takeover could reshape the open-source AI ecosystem because the platform is a critical distribution hub for models, datasets, inference tools, and robotics projects.

  • Hugging Face reportedly hired an investment bank to assess buyer interest; its potential valuation has nearly tripled from $4.5 billion in 2023.
  • The platform hosts more than 2 million public models and 500,000 datasets, giving a prospective buyer access to a major AI developer ecosystem.
  • Its scope now extends beyond model hosting through llama.cpp/GGML, Gradio, XetHub, and open-source robotics initiatives such as LeRobot.
  • The reported $13 billion valuation is roughly 130 times its estimated $100 million ARR, reflecting the strategic value of AI distribution infrastructure—but an acquisition could undermine the community trust supporting that value.

AI Model Security 1

The Hugging Face incident and the road ahead

Rank 75 · Content 85 · Popularity N/A

TL;DR - OpenAI reports findings from a security incident involving Hugging Face and outlines plans to strengthen model security, monitoring, and alignment. The provided excerpt does not include technical details about the incident or specific mitigations.

  • Focuses on improving protections around AI models.
  • Identifies stronger monitoring as part of OpenAI’s response.
  • Connects future security measures with model alignment.
  • Specific findings, impacts, and remediation steps are not provided in the excerpt.

AI for Materials 1

Representative image for 超亿元!经纬、苏州国资,投了一家AI for Science!

超亿元!经纬、苏州国资,投了一家AI for Science!

Rank 61 · Content 65 · Popularity N/A

TL;DR - MatSource, an AI-for-materials startup founded in 2025, raised more than RMB 100 million across two funding rounds to expand its automated experimentation platform and commercialize materials for energy and catalysis. Its approach integrates AI prediction with high-throughput physical validation across the materials-development pipeline.

  • MatSource reports a million-scale real-world materials database, with plans to reach 10 million records this year.
  • The company has developed more than 200 materials-prediction physics models and aims to exceed 250 this year.
  • Its AI-agent-driven platform automates high-throughput inorganic solid-state and solid–liquid synthesis experiments.
  • Funding will also support talent recruitment and commercialization in areas including green organic electrosynthesis and solid-state electrolytes.

AI for Science 1

Representative image for 2026 AI for Science行业研究报告案例征集 | 智局咨询

2026 AI for Science行业研究报告案例征集 | 智局咨询

Rank 33 · Content 25 · Popularity N/A

TL;DR - 智局咨询正在征集《2026 AI for Science行业研究报告》案例,以梳理AI在科学研究中的技术进展、产业应用和商业模式。该项目旨在连接企业、科研机构与技术平台,为行业参与者提供市场与战略参考。

  • 报告覆盖药物发现、生命科学、材料、化学与催化、能源、半导体及工业研发等领域。
  • 重点考察AI如何提升研发效率、降低成本并加快科研成果落地。
  • 将分析技术授权、联合开发、合资与并购等产学研协作和产业整合模式。
  • 计划研究全球市场格局、政策与资本驱动因素、潜在风险,并拆解代表性成功案例。

Embodied AI 2

Representative image for 独家丨任少卿创立具身公司,蔚来将成新公司战略股东

独家丨任少卿创立具身公司,蔚来将成新公司战略股东

Rank 61 · Content 65 · Popularity N/A

TL;DR - NIO autonomous-driving chief Ren Shaoqing is founding a physical-AI and embodied-intelligence company, with NIO participating as a strategic shareholder and partner. The venture will develop foundation models and embodied robots while Ren continues leading NIO’s autonomous-driving business.

  • The startup plans a research-heavy team focused on next-generation AI foundation models and the development, production, and sale of embodied robots.
  • NIO will provide strategic backing and pursue deeper collaboration with the new company.
  • Ren previously helped develop Faster R-CNN and ResNet and built NIO’s in-house autonomous-driving technology stack.
  • NIO’s current driving architecture combines a world model, supervised fine-tuning, and closed-loop reinforcement learning; its latest NWM world model was reportedly deployed to more than 700,000 users.
Representative image for 【具身智能】转行群成立!

【具身智能】转行群成立!

Rank 33 · Content 25 · Popularity N/A

TL;DR - CVer is promoting a paid learning community and WeChat groups for people transitioning into embodied AI and robotics. The offering bundles technical updates, learning paths, job listings, and industry directories amid growing interest in the field.

  • The community claims more than 1,400 participants and includes a dedicated section for jobs, graduate recruitment, and internships.
  • Members receive embodied-AI technology and project updates, an introductory-to-advanced learning roadmap, and industry reports.
  • Resources include directories of hundreds of companies, university laboratories, and researchers working in embodied AI.
  • The article predicts roughly 500 embodied-intelligence or robotics papers at CVPR 2027, but provides no supporting methodology beyond a conservative growth estimate.

Embodied Robotics 1

Representative image for 独家 | 乐聚发布垂域具身模型:一倍工业提效,两项榜单第一

独家 | 乐聚发布垂域具身模型:一倍工业提效,两项榜单第一

Rank 61 · Content 65 · Popularity N/A

TL;DR - Leju Robotics introduced KUAVO VLA, an industrial vision-language-action model mid-trained on 600+ hours of robot data to reduce task-specific training and deployment costs. The company reports leading results against three general-purpose VLA models on a 25-task benchmark.

  • KUAVO VLA inserts an industrial-domain training stage between general VLA pretraining and task-specific post-training, encoding 100 common capabilities such as sorting,搬运, loading, and assembly.
  • Training uses real-world data exclusively from KUAVO robots, aiming to improve embodiment-specific control while avoiding interference from differing robot morphologies.
  • Across 20 custom industrial tasks and five GM100 tasks, KUAVO VLA achieved a 48.27% task success rate and a 74.51% process score, ranking first on both metrics.
  • Leju says the model can roughly double development efficiency in several scenarios and reduce the data collection, training, and debugging required for new industrial skills.

Embodied World Models 1

Representative image for 具身新贵昆仑行斩获 WorldArena单项冠军全球亚军,世界模型全面领先

具身新贵昆仑行斩获 WorldArena单项冠军全球亚军,世界模型全面领先

Rank 57 · Content 60 · Popularity N/A

TL;DR - Kunlunx AI’s first-generation GeWu world model ranked second overall on WorldArena 2.0 Track 1 with 65.91 and first in image quality with 69.58. Its architecture explicitly models the causal chain from intent to action to consequence, aiming to improve physically consistent robot simulation and planning.

  • GeWu placed in the top four on four of six evaluation dimensions among 77 participating models and scored 82.40 in interaction quality.
  • Three independent Transformer towers represent intent, intervention, and consequence, with directional cross-tower attention preventing action generation from accessing future visual outcomes.
  • Language is modeled autoregressively, while actions and future video frames use flow matching; noise-level adjustments support simulation, policy inference, and joint prediction in one architecture.
  • Chunk-wise autoregressive generation uses recency-weighted memory sampling, absolute temporal encoding, and frame-rate scaling to maintain consistency over longer videos.

Humanoid Robotics 1

‘Robot Olympics’ reveal humanoids' rapid progress — but hurdles remain

Rank 48 · Content 50 · Popularity 43

TL;DR - “Robot Olympics” events showed rapid gains in humanoid-robot athletic performance, including record-breaking sprints, while exposing persistent weaknesses in practical manipulation. The contrast highlights how progress in controlled demonstrations has not yet translated into robust real-world capability.

  • Humanoid robots set new records in sporting tasks such as sprinting.
  • Practical tasks requiring precise physical interaction, such as hammering nails, remained difficult.
  • The results suggest locomotion is advancing faster than dexterous manipulation and general-purpose reliability.

Peer Review Integrity 1

Representative image for AAAI「互bid」风波后续:可直接拒稿,违规还可能多年禁投

AAAI「互bid」风波后续:可直接拒稿,违规还可能多年禁投

Rank 50 · Content 50 · Popularity N/A

TL;DR - AAAI-27 is tightening enforcement against coordinated reviewer bidding, including blocking reciprocal review assignments and imposing penalties ranging from desk rejection to multi-year conference bans. The measures respond to reports of authors exchanging paper IDs and organizing mutual bids to influence reviews.

  • AAAI will block reciprocal “2-cycle” assignments when two parties bid on each other’s papers during both centralized reviewer-allocation phases.
  • Naturally occurring reciprocal matches are not automatically violations, but the system will still try to avoid them.
  • Remaining or later-added 2-cycles will be examined for coordinated bidding, unsupported scores, or abnormal reviews.
  • AAAI reports that its updated matching algorithm reduced bid-linked 2-cycles from 950 and 65 in the two phases to zero in prior testing.

Research Community 1

Representative image for ICLR 2027 投稿群

ICLR 2027 投稿群

Rank 26 · Content 15 · Popularity N/A

TL;DR - CVer is organizing WeChat groups for researchers submitting to ICLR 2027 and those who already submitted to AAAI 2027. The groups are intended for coordination around submission requirements, rebuttals, and conference participation rather than sharing technical research results.

  • The ICLR 2027 group targets active submitters ahead of the abstract deadline.
  • The AAAI 2027 group is limited to researchers who have already submitted.
  • Participants are explicitly warned not to disclose personal or paper information or violate submission rules.
  • The post also promotes CVer’s paid academic community and computer-vision research resources.

Synthetic Biology 1

Representative image for Gucci母公司押注,生物制造融资近亿元!

Gucci母公司押注,生物制造融资近亿元!

Rank 47 · Content 45 · Popularity N/A

TL;DR - Chinese biomanufacturing startup Daosheng Biotechnology raised nearly RMB 100 million in Pre-A funding to scale biosynthetic indigo production and advance its bio-based pigment platform. The company says it is the first to achieve 100-ton-scale production of indigo using synthetic biology.

  • Funding will support commercial-scale indigo production, core technology development, and expansion into additional markets.
  • Its portfolio includes biologically produced indigo, melanin, red and yellow pigments, plus active pharmaceutical ingredients.
  • Target applications span textiles, food additives, cosmetics, personal care, and pharmaceuticals.
  • Daosheng is conducting joint R&D with brands owned by Gucci parent Kering and pursuing projects with international cosmetics and US food companies.