7 篇 ECCV 论文!极佳视界联合顶尖高校,打通空间智能从「看得稳」到「摸得准」再到「决策灵」的落地瓶颈
Ranking
Overall
70
Content
75
Popularity
58
Observed public metrics from 1 member.
Merged summary
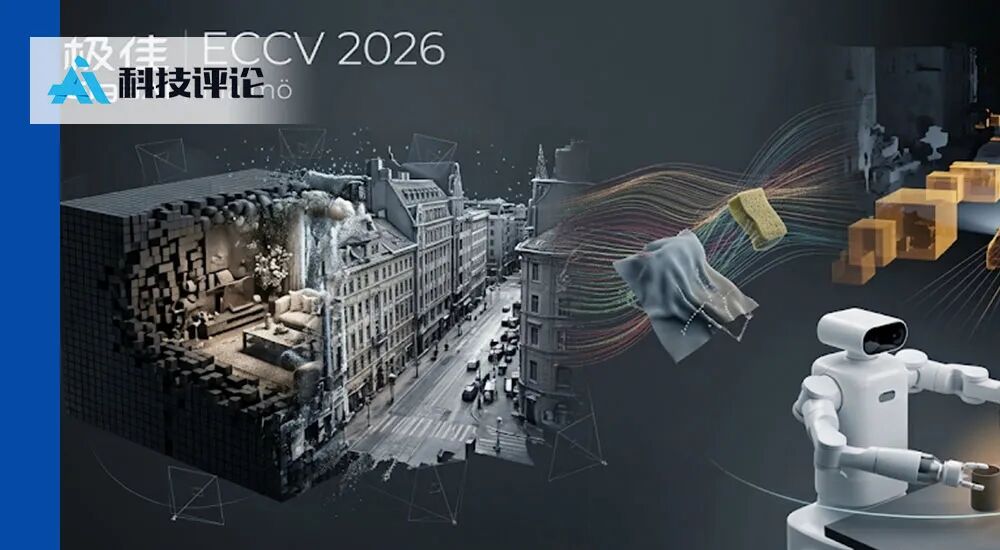
TL;DR - GigaAI and university partners presented seven ECCV papers spanning 3D/4D reconstruction, physically grounded assets, embodied control, and driving world models. Together, they aim to move spatial AI from visually convincing generation toward physically responsive, closed-loop interaction.
- VLA-R1 combines explicit chain-of-thought supervision with GRPO reinforcement learning to improve interpretable, verifiable vision-language-action decisions for robotic manipulation.
- OmniNWM jointly generates multimodal driving states, responds to vehicle controls, and derives safety and traffic-rule rewards from predicted 3D occupancy.
- ReconPhys estimates appearance and physical properties from monocular video, while MoGe4D uses geometry-aware trajectories to synthesize dynamic 4D scenes from one image.
- VolSplat, AnchorSplat, and 2K Retrofit target production-grade 3D geometry through voxel-aligned reconstruction, rapid detail enhancement, and sparse high-resolution refinement.
Sources (1)
7 篇 ECCV 论文!极佳视界联合顶尖高校,打通空间智能从「看得稳」到「摸得准」再到「决策灵」的落地瓶颈
Public signals
Hugging Face upvotes 13
TL;DR - GigaAI and university partners presented seven ECCV papers spanning 3D/4D reconstruction, physically grounded assets, embodied control, and driving world models. Together, they aim to move spatial AI from visually convincing generation toward physically responsive, closed-loop interaction.
- VLA-R1 combines explicit chain-of-thought supervision with GRPO reinforcement learning to improve interpretable, verifiable vision-language-action decisions for robotic manipulation.
- OmniNWM jointly generates multimodal driving states, responds to vehicle controls, and derives safety and traffic-rule rewards from predicted 3D occupancy.
- ReconPhys estimates appearance and physical properties from monocular video, while MoGe4D uses geometry-aware trajectories to synthesize dynamic 4D scenes from one image.
- VolSplat, AnchorSplat, and 2K Retrofit target production-grade 3D geometry through voxel-aligned reconstruction, rapid detail enhancement, and sparse high-resolution refinement.