这个新开源的世界模型只有1.3B,单卡就能实时跑!
Ranking
Overall
74
Content
75
Popularity
70
Observed public metrics from 1 member.
Merged summary
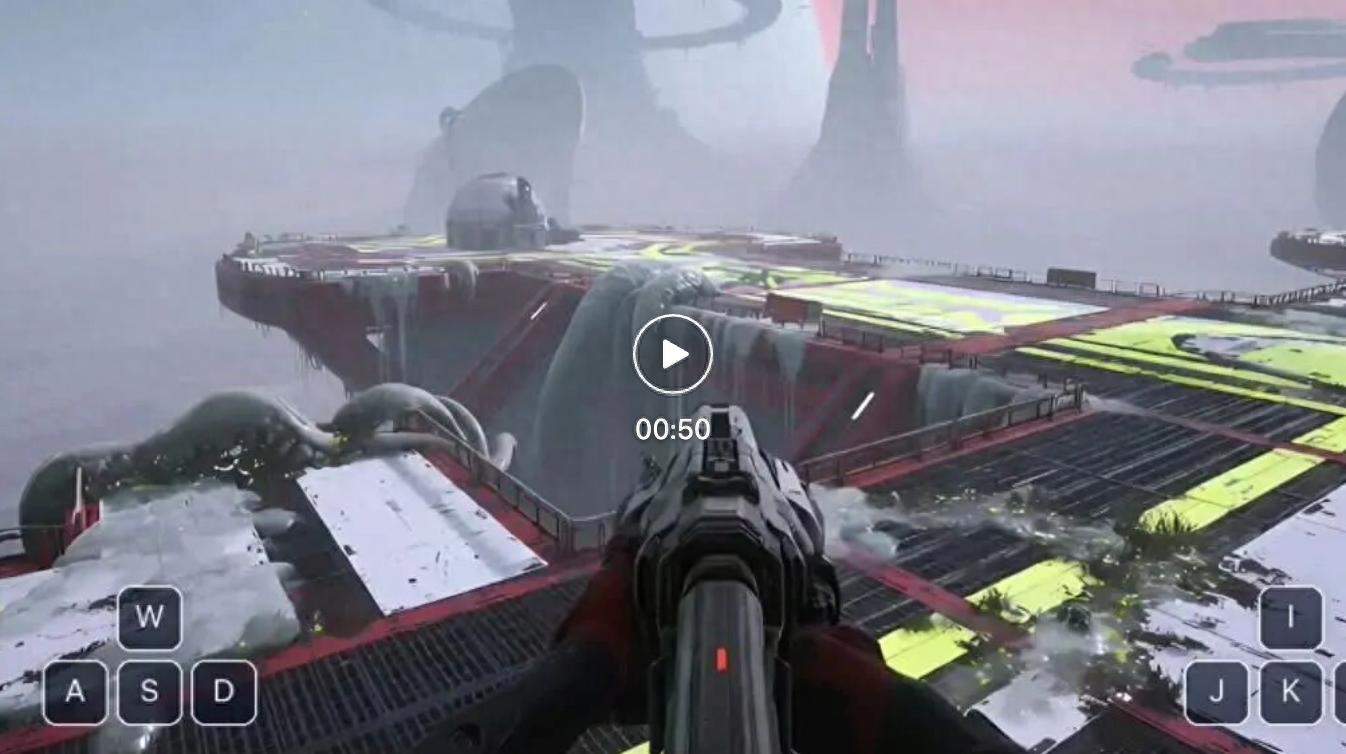
TL;DR - Ant Lingbo released a 1.3B-parameter version of its open-source LingBot-World 2.0, designed for real-time, locally generated interactive worlds on a single consumer GPU. The smaller model could make experimentation with persistent world generation substantially more accessible.
- LingBot-World generates continuously evolving scenes conditioned on user actions, rather than producing a fixed video in one batch.
- Its training pipeline combines causal pretraining with MoBA, a mixture of bidirectional and autoregressive attention masks intended to improve long-context visual stability.
- Consistency distillation reduces the teacher model’s multi-step denoising process, while distribution-matching distillation on student self-rollouts targets accumulated errors during long autoregressive generation.
- Alongside the 1.3B model, the team released causal-pretrained and bidirectional teacher models to support community post-training, distillation, compression, and domain adaptation.
Sources (1)
这个新开源的世界模型只有1.3B,单卡就能实时跑!
Public signals
Hugging Face upvotes 46 · Semantic Scholar citations 25 · Semantic Scholar influential citations 10
TL;DR - Ant Lingbo released a 1.3B-parameter version of its open-source LingBot-World 2.0, designed for real-time, locally generated interactive worlds on a single consumer GPU. The smaller model could make experimentation with persistent world generation substantially more accessible.
- LingBot-World generates continuously evolving scenes conditioned on user actions, rather than producing a fixed video in one batch.
- Its training pipeline combines causal pretraining with MoBA, a mixture of bidirectional and autoregressive attention masks intended to improve long-context visual stability.
- Consistency distillation reduces the teacher model’s multi-step denoising process, while distribution-matching distillation on student self-rollouts targets accumulated errors during long autoregressive generation.
- Alongside the 1.3B model, the team released causal-pretrained and bidirectional teacher models to support community post-training, distillation, compression, and domain adaptation.