吹爆开源!RunningHub让MiniMax H3满血提速12倍,本地部署照样起飞
Ranking
Overall
68
Content
75
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
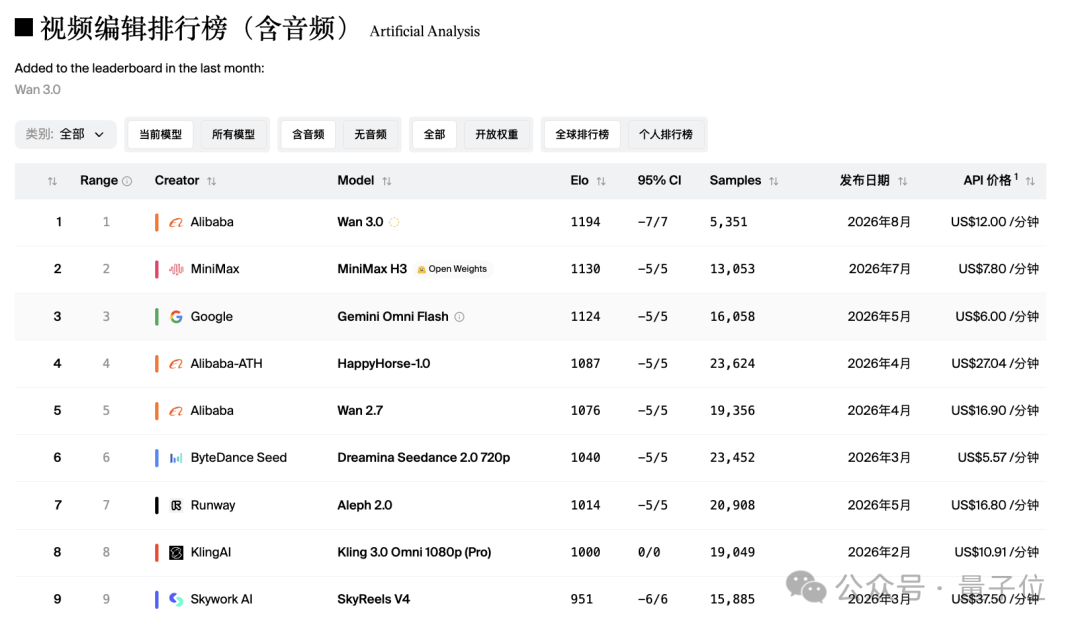
Merged summary
TL;DR - RunningHub open-sourced H3 Lightning, an inference stack that accelerates MiniMax H3 video generation by about 12× while retaining BF16 precision. It targets locally deployable, PCIe-connected multi-GPU systems, reducing the cost and iteration time of AI video production.
- On four RTX 6000D GPUs, a 5-second 1344×768 video took 28.7 seconds, versus 348.8 seconds for the original BF16 50-step setup.
- A post-trained acceleration model cuts denoising to 4–9 steps; SageAttention2, Cache-DiT, and
torch.compilefurther optimize attention, reuse intermediate results, and reduce execution overhead. - For eight GPUs without NVLink, TP2 plus Ulysses4 was reportedly 12% faster and used about 14 GiB less memory than TP4 plus Ulysses2.
- RunningHub integrated the optimizations into SGLang’s multimodal generation engine and published deployment instructions and code for local use.
Sources (1)
吹爆开源!RunningHub让MiniMax H3满血提速12倍,本地部署照样起飞
Public signals
N/A
TL;DR - RunningHub open-sourced H3 Lightning, an inference stack that accelerates MiniMax H3 video generation by about 12× while retaining BF16 precision. It targets locally deployable, PCIe-connected multi-GPU systems, reducing the cost and iteration time of AI video production.
- On four RTX 6000D GPUs, a 5-second 1344×768 video took 28.7 seconds, versus 348.8 seconds for the original BF16 50-step setup.
- A post-trained acceleration model cuts denoising to 4–9 steps; SageAttention2, Cache-DiT, and
torch.compilefurther optimize attention, reuse intermediate results, and reduce execution overhead. - For eight GPUs without NVLink, TP2 plus Ulysses4 was reportedly 12% faster and used about 14 GiB less memory than TP4 plus Ulysses2.
- RunningHub integrated the optimizations into SGLang’s multimodal generation engine and published deployment instructions and code for local use.