7名博士生仅用3个月从零训练7B大模型:代码+数据+训练日志全公开
Ranking
No observed public metrics; popularity remains neutral/archived.
Merged summary
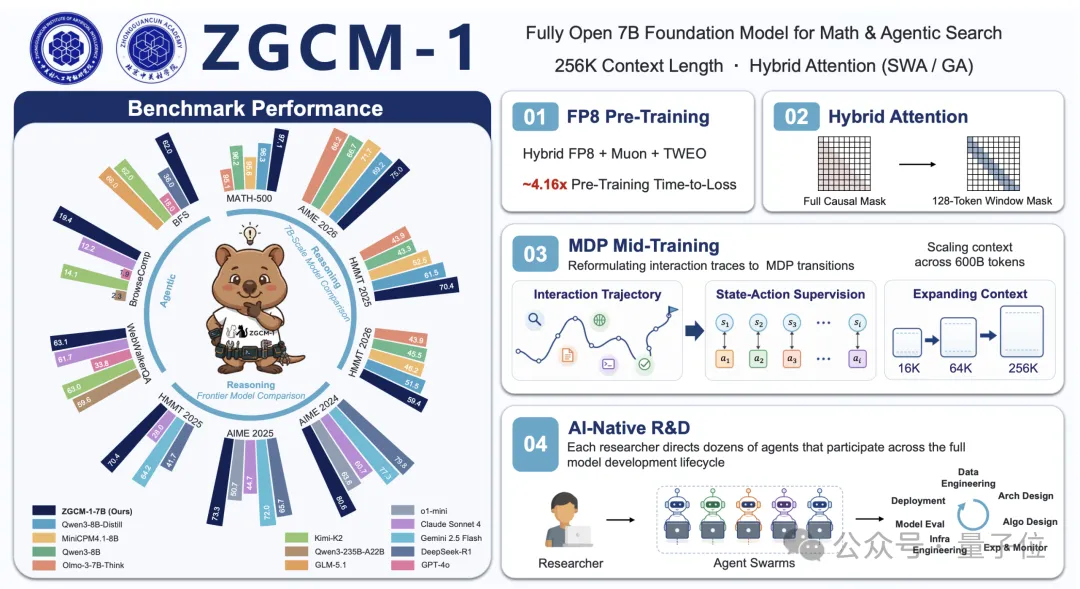
TL;DR - Seven doctoral students trained the open-source ZGCM-1 7B model from scratch in three months, using hundreds of AI agents to support data processing, experimentation, monitoring, and evaluation. The release includes weights, code, data recipes, checkpoints, and logs, offering an unusually reproducible view of end-to-end foundation-model development.
- ZGCM-1 reportedly performs competitively with similarly sized models such as Qwen3-8B, including strong results on reasoning, search, and tool-use evaluations.
- A hybrid local/global attention design achieved about 3.94× higher throughput and roughly one-sixth the KV-cache usage versus full attention at 256K context.
- Muon, FP8, delayed scaling, and TWEO delivered approximately 4.2× better efficiency to reach the same 16K pretraining loss than a BF16/AdamW baseline.
- Agents reached high autonomy in monitoring and deployment, but architecture and algorithm design remained human-led; the team rated these tasks only at L2 autonomy.
Sources (1)
7名博士生仅用3个月从零训练7B大模型:代码+数据+训练日志全公开
TL;DR - Seven doctoral students trained the open-source ZGCM-1 7B model from scratch in three months, using hundreds of AI agents to support data processing, experimentation, monitoring, and evaluation. The release includes weights, code, data recipes, checkpoints, and logs, offering an unusually reproducible view of end-to-end foundation-model development.
- ZGCM-1 reportedly performs competitively with similarly sized models such as Qwen3-8B, including strong results on reasoning, search, and tool-use evaluations.
- A hybrid local/global attention design achieved about 3.94× higher throughput and roughly one-sixth the KV-cache usage versus full attention at 256K context.
- Muon, FP8, delayed scaling, and TWEO delivered approximately 4.2× better efficiency to reach the same 16K pretraining loss than a BF16/AdamW baseline.
- Agents reached high autonomy in monitoring and deployment, but architecture and algorithm design remained human-led; the team rated these tasks only at L2 autonomy.