GPT-6之后,具身智能走向何方?诺因发布GLOW技术报告,给出机器人“一教就会”的答案
Ranking
Overall
68
Content
75
Popularity
N/A
No observed public metrics; popularity remains neutral/archived.
Merged summary
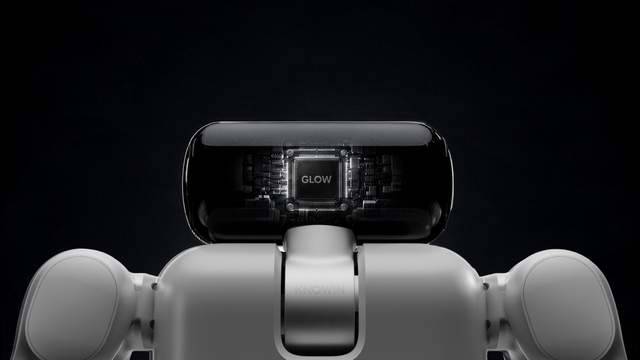
TL;DR - Knowin released a technical report for GLOW, a generative learning architecture designed to let robots reuse skills across objects and environments after a single human demonstration. The system unifies multimodal reasoning, action generation, world simulation, synthetic experience, and execution feedback.
- GLOW combines KnowinGLOW, KnowinDream, KnowinWorld, and KnowinAgent to cover task understanding, synthetic physical experience, action-outcome prediction, and closed-loop replanning.
- Its autoregressive multimodal model jointly handles vision, spatial reasoning, planning, and action generation rather than connecting separate perception and control modules.
- Demonstrations included transferring multi-step tasks such as storage, watering, patterned wiping, and drink preparation without retraining model parameters.
- The report claims 62.2% average success on RoboDojo, 86.7% on LIBERO-Pro, and a 65.62 top score for KnowinBrain-1.5 on Embodied Arena’s 2D embodied-QA benchmarks.
Sources (1)
GPT-6之后,具身智能走向何方?诺因发布GLOW技术报告,给出机器人“一教就会”的答案
Public signals
N/A
TL;DR - Knowin released a technical report for GLOW, a generative learning architecture designed to let robots reuse skills across objects and environments after a single human demonstration. The system unifies multimodal reasoning, action generation, world simulation, synthetic experience, and execution feedback.
- GLOW combines KnowinGLOW, KnowinDream, KnowinWorld, and KnowinAgent to cover task understanding, synthetic physical experience, action-outcome prediction, and closed-loop replanning.
- Its autoregressive multimodal model jointly handles vision, spatial reasoning, planning, and action generation rather than connecting separate perception and control modules.
- Demonstrations included transferring multi-step tasks such as storage, watering, patterned wiping, and drink preparation without retraining model parameters.
- The report claims 62.2% average success on RoboDojo, 86.7% on LIBERO-Pro, and a 65.62 top score for KnowinBrain-1.5 on Embodied Arena’s 2D embodied-QA benchmarks.