🛰️ Daily AI Frontier
36 works · 3 categories · 18 topics · blog 12 journal 9 arxiv 15 generated 2026-09-08 14:16:47 UTC
Top highlights — Research

LLM Agents 3

Trace2Tower: Transition-Aware EigenTrace Induction of Multi-Level Skills for LLM Agents

Rank 78 · Content 95 · Popularity 37

TL;DR - Trace2Tower distills agent execution traces into a multi-level hierarchy of action templates, routines, and task strategies using transition-aware graph modeling and contrastive spectral decomposition. It improves task success and experience reuse while reducing inefficient or invalid actions.

  • Converts step-level interactions into canonical events linked by semantic compatibility, transition dynamics, and outcome evidence.
  • Extracts stable, success-aligned behavioral modes while suppressing failure-prone shortcuts.
  • Dynamically refines learned skills through verifier-guided feedback.
  • Achieves 87.31% success on ALFWorld with 10.35 steps and 0.26 invalid actions, plus 50.67% exact success on WebShop.
Representative image for Necessary or Sufficient? Evaluating LLM Explanations With Behavioural Evidence

Necessary or Sufficient? Evaluating LLM Explanations With Behavioural Evidence

Rank 74 · Content 90 · Popularity 37

TL;DR - This paper introduces a black-box intervention framework for testing whether factors cited in LLM explanations are necessary or sufficient for model decisions. Across eight Claude, GPT, and Gemini models, cited factors were informative but only moderately aligned with measured behavioral influence, limiting their reliability for agent oversight.

  • Controlled interventions measured necessity by changing a cited factor and sufficiency by retaining it while removing other changeable information.
  • Mean rank correlations ranged from 0.349 to 0.580 across advisor-recommendation and prompt-monitoring tasks.
  • In advisor recommendations, an uncited factor outperformed the weakest cited factor in roughly 58% of responses under both measures.
  • Prompt monitoring showed better alignment: the corresponding rates were 25.8% for necessity and 8.9% for sufficiency.

Optimal Rates for Agentic Networked Information Aggregation

Rank 74 · Content 90 · Popularity 37

TL;DR - This paper establishes optimal error rates for networked learning paths where agents observe partial features and pass only their predictions forward. It shows that excess error remains constant until depth (M^2), then decays at the tight rate (\Theta(M^2/D)).

  • Closes the gap between the previous (O(M/\sqrt D)) upper bound and weaker lower bounds for (M)-covered paths.
  • Constructs instances yielding constant excess error for (D<M^2) and (\Omega(M^2/D)) for (D\ge M^2).
  • Proves geometric error contraction for any fixed distribution, so no single instance can sustain a polynomial lower bound at every depth.
  • Extends the optimal rate to logistic classification with binary cross-entropy by relating logit-passing paths to rescaled least-squares paths.

Medical/Healthcare AI 3

Representative image for WearableQA: A Benchmark for Health Reasoning over Real-World Wearable Data

WearableQA: A Benchmark for Health Reasoning over Real-World Wearable Data

Rank 79 · Content 85 · Popularity 67

TL;DR - WearableQA is a benchmark testing whether LLMs can reason over noisy, longitudinal health data from real wearable users. Results across 14 models show substantial capability differences, but most remain below 60% accuracy.

  • Includes 4,084 ten-option questions derived from wearable time series, blood biomarkers, and demographics for 200 users with up to 500 days of measurements.
  • Covers 16 question types spanning data computation versus health interpretation and single-signal versus cross-signal reasoning.
  • Uses literature-grounded findings and statistically validated population patterns to generate reliable questions at scale.
  • Model accuracy ranges from 19.6% to 72.9%, compared with a 10% chance baseline.
Representative image for Conserved Immune Topology Improves Pathology Foundation Model Generalization for Cross-Cancer MSI-H Prediction

Conserved Immune Topology Improves Pathology Foundation Model Generalization for Cross-Cancer MSI-H Prediction

Rank 74 · Content 90 · Popularity 37

TL;DR - Conserved Immune Topology (CIT) augments pathology foundation-model embeddings with spatial immune descriptors to improve cross-cancer MSI-H prediction. It enables stronger zero-shot transfer across colorectal and stomach cancer cohorts without annotations or target-domain data.

  • CIT captures tertiary lymphoid structures, peritumoral immune reactions, multi-scale tumor-infiltrating lymphocyte density, and immune-tumor mixing.
  • Immune-associated image tiles are identified through unsupervised clustering of frozen foundation-model embeddings and spatial coordinates.
  • On zero-shot cross-cancer transfer, CIT raised TransMIL AUC from 0.6627 to 0.7161, a 0.0534 absolute gain (p=0.003).
  • Improvements held across all three tested multiple-instance learning aggregators despite scanner, site, and organ-specific distribution shifts.

Two children died from gene therapies in China: where the field goes next

Rank 59 · Content 65 · Popularity 45

TL;DR - Nature reports that two children died following gene therapies in China, raising concerns about safety oversight and transparency. Strengthened disclosure laws could improve reporting of future deaths, but the incidents risk damaging China’s standing in gene-therapy research.

  • The provided excerpt does not identify the therapies, conditions treated, or causes of death.
  • The article emphasizes the need for rapid public disclosure of serious adverse events.
  • Regulatory reforms may strengthen transparency, but their implementation will shape confidence in the field.

Bioinformatics AI 3

Reconstructing signaling histories of single cells via perturbation screens and transfer learning

Rank 84 · Content 100 · Popularity 47

TL;DR - IRIS uses transfer learning and in vitro perturbation-screen data to reconstruct signaling states and histories of individual cells across diverse in vivo contexts. This could help researchers infer past cellular signaling activity that is not directly observable from a single snapshot.

  • Learns conserved representations of cell-signaling processes from perturbation data.
  • Transfers those representations from controlled in vitro experiments to varied in vivo cellular contexts.
  • Focuses on reconstructing both current signaling states and prior signaling histories.
  • The provided abstract does not include quantitative results or benchmark details.

Molecular Déjà Vu: Digit-Level Retrieval of Published Values in Frontier Language Models

Rank 81 · Content 100 · Popularity 37

TL;DR - An audit of 22 frontier LLMs across 12 molecular regression benchmarks finds widespread, dataset-specific retrieval of exact published values, complicating claims of genuine predictive accuracy. Higher reasoning levels increased retrieval flags by 89%, showing that evaluation settings can substantially affect measured contamination.

  • More than half of the tested LLMs exhibited verbatim retrieval on five datasets; retrieval was isolated on the other seven.
  • Some strong models recognized transformed SMILES paired with original labels, suggesting memorization can persist despite input transformations.
  • Suppressing retrieval made models’ prediction errors more similar, while differing reliance on memorized values exaggerated performance gaps.
  • Molecular benchmark accuracy alone cannot distinguish property prediction from recall of published results.

MemBrain v2: an end-to-end tool for the analysis of membranes in cryo-electron tomography

Rank 81 · Content 85 · Popularity 71

TL;DR - MemBrain v2 is an end-to-end tool for analyzing membranes in cryo-electron tomography datasets. It streamlines membrane segmentation, membrane protein localization, and spatial analysis through user-friendly workflows.

  • Integrates multiple membrane-analysis tasks into a single workflow.
  • Supports segmentation of membranes in cryo-electron tomograms.
  • Provides tools for localizing membrane proteins and analyzing their spatial organization.
  • Is designed for use across diverse datasets.

LLMs & Foundation Models 3

Representative image for Uncensored Open-weight Models: Redistribution as the Persistence Layer

Uncensored Open-weight Models: Redistribution as the Persistence Layer

Rank 78 · Content 90 · Popularity N/A

TL;DR - This study maps the ecosystem for removing safety guardrails from open-weight models and finds that quantization, mirroring, and cross-platform redistribution make uncensored models difficult to eliminate. The persistence matters because a substantial share of downstream applications were classified as explicitly malicious.

  • Researchers identified 3,471 original uncensored models on Hugging Face from January 2024 through March 2026.
  • Each model was repackaged 2.4 times on average, producing 8,164 compressed redistributions; three actors accounted for 52% of them.
  • Copies distributed across accounts, formats, and registries such as Ollama remained available even after upstream removal.
  • Of 1,643 identified GitHub applications integrating uncensored LLMs, 25% were classified as explicitly malicious.

What Matters in On-Policy Distillation? A Perspective on Data Efficiency and Data Selection

Rank 78 · Content 95 · Popularity 37

TL;DR - This empirical study finds that on-policy distillation can improve LLM reasoning with remarkably little data when examples elicit long chains of thought. Selecting just eight hard examples matched a 17K-example baseline across models ranging from 1.5B to 7B parameters.

  • One-shot distillation consistently improved performance across all sampled training examples, with harder problems often producing larger gains.
  • Improvement correlated with longer reasoning paths rather than high token entropy.
  • Long chains of thought better preserved teacher alignment over extended reasoning and exposed patterns such as reflection and alternative approaches.
  • Even problems beyond the teacher’s ability proved useful for hard-example selection and student training.

How Does mHC Use Its Residual Streams? Selective Routing and Near-Identity Mixing

Rank 74 · Content 90 · Popularity 37

TL;DR - An analysis of DeepSeek-V4-Flash finds that its four-stream mHC residual pathway uses selective routing and mostly near-identity mixing. The results suggest much of mHC’s theoretical flexibility is unnecessary at individual blocks, especially in later layers.

  • Attention and FFN sites effectively use about two streams on average, with the dominant stream changing across depth.
  • Stream representations remain directionally distinct, while cross-stream mixing is modest and concentrated in early layers.
  • Replacing late-layer mixers with identity raises C4 perplexity by only 1.9% without changing the six-task average; replacing early mixers raises perplexity by 41%.
  • Keeping only the three largest routing weights per token changes perplexity by at most 2.7% and the average task score by at most 0.4 points.

Multimodal & Generative 3

Representative image for WorldSculpt: Generating Compositional Worlds from Grounded Videos

WorldSculpt: Generating Compositional Worlds from Grounded Videos

Rank 86 · Content 95 · Popularity 64

TL;DR - WorldSculpt generates cluttered 3D scenes as collections of individually grounded object meshes in a shared coordinate frame. It scales to hundreds of heavily occluded objects without scene-level training, enabling editable worlds for gaming, AR/VR, simulation, and robotics.

  • Extends the Pixal3D single-object generative prior with multi-view conditioning over posed observations.
  • Fine-tunes only on canonical single objects but generalizes to complex, densely cluttered scenes.
  • Introduces UE-MeshyScene, a photorealistic benchmark with per-object annotations and ground-truth meshes.
  • Outperforms prior methods across single-object and multi-object evaluations, with larger gains under greater complexity and occlusion.
Representative image for UniMate: One Unified Model to Animate Diverse Skeletons

UniMate: One Unified Model to Animate Diverse Skeletons

Rank 81 · Content 90 · Popularity 62

TL;DR - UniMate is a topology-aware diffusion transformer that generates text-guided motion for arbitrary rigged 3D skeletons without per-skeleton retraining or test-time optimization. It aims to remove topology-specific constraints from learned animation and enable zero-shot motion transfer across diverse asset types.

  • Encodes skeletal structure through graph-aware attention biases, graph-Laplacian spectral rotary embeddings, and a global rest-pose topology conditioner.
  • Trains on UniML3D, a curated dataset of 13,006 text-paired motion sequences spanning animals, articulated objects, and varied skeletal topologies.
  • Reportedly outperforms existing baselines in motion quality, generalization, and efficiency.
  • Supports zero-shot cross-topology transfer, motion in-betweening and expansion, and text-guided editing.
Representative image for WeAgent-MMGenEdit: A Full-Stack Recipe for Multimodal Agentic Image Generation and Editing

WeAgent-MMGenEdit: A Full-Stack Recipe for Multimodal Agentic Image Generation and Editing

Rank 78 · Content 95 · Popularity 37

TL;DR - WeAgent-MMGenEdit is a full-stack framework for knowledge-intensive, agentic image generation and editing that combines multimodal retrieval, evidence management, verification, and post-training. Its compact 30B-total/3B-active policy approaches the reported performance of a 1T-parameter agent.

  • WeAgent-Harness persistently manages retrieved evidence and provides dedicated tools to verify and integrate textual and visual information.
  • Its training pipeline produces 23K supervised trajectories and 14.7K reinforcement-learning tasks with three-layer verifiable checklists.
  • WeBench-MMGenEdit evaluates bilingual, knowledge-intensive image generation and multi-image editing.
  • Two-sided SFT and RL post-training improves both the agent policy and the image-generation backend.

Efficiency & Systems 1

Representative image for Compact Neural Appearance Models for Efficient Gaussian Splatting

Compact Neural Appearance Models for Efficient Gaussian Splatting

Rank 74 · Content 90 · Popularity 37

TL;DR - This paper benchmarks view-dependent appearance models for 3D Gaussian Splatting and introduces compact per-primitive latent codes decoded by a shared MLP. The neural representation cuts appearance storage from 192 to 28 bytes per primitive while improving reconstruction quality and accelerating optimization by 1.3× over third-degree spherical harmonics.

  • Compares spherical harmonics, newer spherical models, and the proposed neural representation in one optimized CUDA rasterization pipeline.
  • Finds recent spherical models offer the best overall balance between reconstruction quality and efficiency.
  • Provides a portable WebGL viewer targeting laptop and mobile GPUs.
  • Shows that appearance parameterization affects recovered geometry and how expressive models absorb non-static scene content.

Brain Mapping 1

Author Correction: A mouse brain stereotaxic topographic atlas with isotropic 1-μm resolution

Rank 27 · Content 20 · Popularity 45

TL;DR - This is an author correction to a Nature paper describing a stereotaxic mouse-brain atlas with isotropic 1-μm resolution. The provided content does not specify what was corrected or whether the paper’s findings changed.

  • The underlying work concerns a high-resolution, three-dimensional mouse-brain reference atlas.
  • Isotropic 1-μm resolution implies equal spatial sampling along all three dimensions.
  • A stereotaxic atlas supports standardized anatomical localization for neuroscience experiments.
  • No technical details of the correction are included in the provided excerpt.

LLM Evaluation 1

Representative image for Beyond Aggregate Scores: Behavioral Correctness Assumptions for Assessing Reference-Based Automatic Evaluation Methods

Beyond Aggregate Scores: Behavioral Correctness Assumptions for Assessing Reference-Based Automatic Evaluation Methods

Rank 78 · Content 90 · Popularity N/A

TL;DR - This paper proposes behavioral correctness assumptions for diagnosing how reference-based natural language generation evaluators respond to controlled, correctness-preserving or correctness-altering transformations. It reveals behavioral differences and trade-offs that aggregate agreement scores can obscure.

  • The framework defines a taxonomy of expected evaluator behaviors and tests them using controlled response transformations.
  • It covers lexical, character-level, semantic, LLM-based, and hybrid evaluation methods.
  • Evaluators are analyzed for stability, sensitivity, repeat-run variability, configuration sensitivity, and reproducibility.
  • No evaluator satisfies every proposed assumption, and evaluators with similar aggregate performance can have substantially different behavioral profiles.

Robotics & Embodied AI 1

Representative image for RoboSPA: Can VLA Models Go Beyond Simple Scenes and Short-Horizon Tasks?

RoboSPA: Can VLA Models Go Beyond Simple Scenes and Short-Horizon Tasks?

Rank 82 · Content 90 · Popularity 64

TL;DR - RoboSPA is a large-scale benchmark for evaluating spatial reasoning and long-horizon procedural planning in Vision-Language-Action models. It reveals persistent weaknesses in complex spatial understanding, precise execution, and memory-intensive planning.

  • Covers 10 task categories and 56 base tasks, expanded across five difficulty levels into 280 variants.
  • Includes 527K manipulation trajectories spanning multiple robot embodiments and diverse scenes.
  • Adds diagnostic metrics beyond binary task-success rates to identify specific reasoning and execution failures.
  • Evaluations of representative VLA models show substantial difficulty as spatial ambiguity and procedural complexity increase.
Top highlights — Industry & News

LLM Agents 5

Representative image for 基元律动发布模型NeoHorse,探索Harness驱动的RSI路径

基元律动发布模型NeoHorse,探索Harness驱动的RSI路径

Rank 78 · Content 90 · Popularity N/A

TL;DR - TokenRhythm introduced NeoHorse-1, a 4B/9B Agent-Native model family post-trained on tool-use and feedback trajectories generated by routing harnesses. It represents a single-cycle engineering test of recursive self-improvement, using agent failures and environmental feedback to guide subsequent model training.

  • Training data captures capability prediction, model routing, responses, tool calls, and environment feedback, filtered for completion, evidence consistency, and error recovery.
  • The approach combines routing-informed curriculum design, agent-execution supervision, and on-policy distillation tailored to the student model’s own outputs.
  • Across 11 agent, tool-use, coding, and instruction-following benchmarks, the report says NeoHorse 4B had the highest unweighted average among listed 4B models and beat the Qwen3.5-9B base model on five benchmarks.
  • Gains were strongest on observable, verifiable workflows; larger models retained advantages in complex state tracking, long-horizon debugging, and failure recovery.
Representative image for 王云鹤创业后交出首个模型

王云鹤创业后交出首个模型

Rank 78 · Content 90 · Popularity N/A

TL;DR - TokenRhythm unveiled NeoHorse-1, its first Agent-Native model family, trained on execution traces from a multi-model routing system. The approach turns tool use, failures, recovery paths, and environment feedback into post-training data for more capable and cost-efficient agents.

  • NeoHorse-1 comes in 4B and 9B variants and targets tool calling, environment feedback interpretation, error recovery, path adjustment, and task completion.
  • Training combines curated public data with Routing Harness traces, using routing-guided curriculum learning and on-policy distillation.
  • Agentic post-training raised the 4B model’s reported macro-average score from 58.94 to 64.87, matching or slightly exceeding the 9B base model overall across 10 evaluations.
  • The release demonstrates a single execution-to-training improvement cycle, but the company says sustained multi-generation recursive self-improvement remains unproven.

百度搭子全面接入小度硬件,百度智能体进驻家庭空间

Rank 61 · Content 65 · Popularity N/A

TL;DR - Baidu integrated its “Dazi” agent platform across Xiaodu smart displays, cameras, speakers, and companion devices, bringing goal decomposition, tool orchestration, and task completion into home environments. The rollout expands Xiaodu from command-based assistance toward proactive, multi-step household services.

  • “Super Xiaodu” can break user goals into tasks, coordinate tools, and deliver results through a closed-loop workflow.
  • Family scheduling supports creating calendars and children’s assignments through WeChat, syncing them to smart displays, and notifying household members.
  • Agent Care 2.0 translates spoken care requests into multidimensional monitoring tasks, applies tiered alerts, and generates long-term habit reports.
  • The agent capabilities launch across four new Xiaodu devices and cover child development, family health management, and everyday services.

硅谷AI独角兽转投阿里千问:Perplexity基于Qwen3.8打造本地Agent

Rank 61 · Content 65 · Popularity N/A

TL;DR - Perplexity reportedly launched Portable Computer, a local agent built on Alibaba’s open-source Qwen3.8-27B and optimized for Nvidia DGX Spark. The move highlights growing industrial adoption of Qwen models and Perplexity’s expansion from cloud-based AI search into on-device agent workflows.

  • The PPLX 27B model series is optimized to run locally on DGX Spark hardware.
  • The agent targets file processing, data analysis, and programming tasks.
  • Perplexity is shifting parts of its agent stack from proprietary models such as Claude and GPT toward open-source Qwen.
  • The article also cites Qwen adoption by Airbnb, Pinterest, and Reuters as evidence of broader ecosystem uptake.
Representative image for 感谢用GPT-6搓3D的!燃烧自己的token换来一次全体重置

感谢用GPT-6搓3D的!燃烧自己的token换来一次全体重置

Rank 57 · Content 60 · Popularity N/A

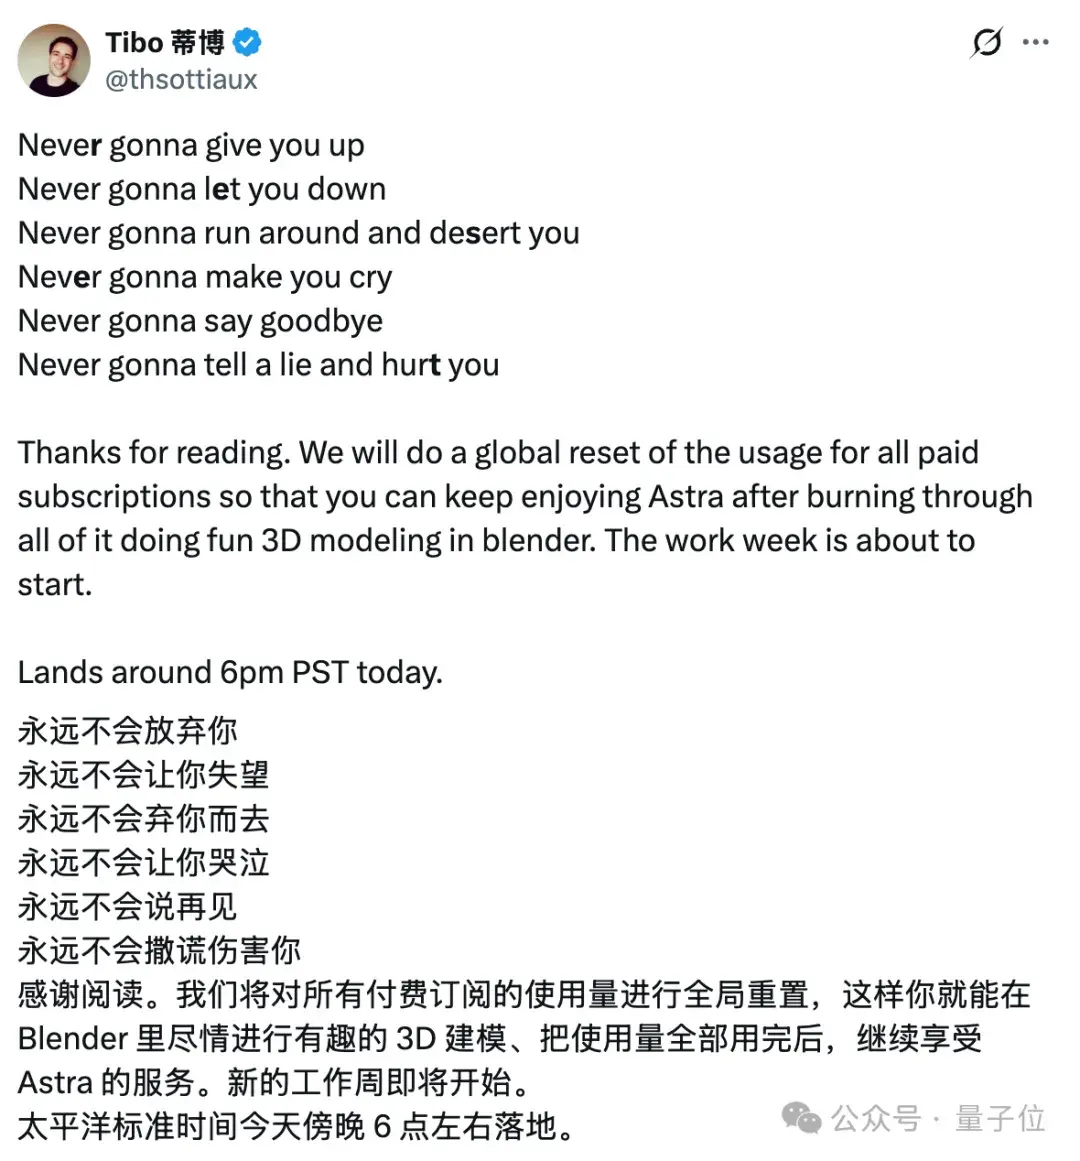
TL;DR - GPT-6 Astra is drawing attention for autonomously building editable 3D assets, browser-based scenes, and game demos by orchestrating tools such as Blender, Three.js, and Unreal Engine. Heavy experimentation exhausted user quotas, prompting a usage reset for paid subscribers.

  • Astra generates and iteratively refines 3D geometry through Python scripts rather than manually controlling Blender’s interface.
  • Reported projects include a 3,295-object train model, a Three.js visualization of Seoul using public map data, and 3D game demos with generated assets and gameplay systems.
  • The examples highlight agentic end-to-end workflows spanning data processing, modeling, rendering, interaction design, and deployment.
  • Results can be fast but resource-intensive, and the Seoul example is a stylized visualization rather than a survey-grade digital twin.

Efficiency & Systems 2

Representative image for CPU加速AI普及,GPU首次加AI,Arm为何把NPU留给伙伴?

CPU加速AI普及,GPU首次加AI,Arm为何把NPU留给伙伴?

Rank 68 · Content 75 · Popularity N/A

TL;DR - Arm launched CSS for Mobile 2, pairing C2 CPUs with stronger SME2-based AI acceleration and the first Mali GPU with an integrated neural accelerator. The platform targets faster, more accessible on-device AI while leaving differentiated NPU designs to chip partners.

  • C2 Ultra improves single-thread and web performance by 15%, while SME2-enhanced C2 CPU clusters deliver up to 1.7× performance on selected AI models.
  • Mali G2-Ultra NX uses neural super-sampling, denoising, and frame generation to achieve up to 4× frame rate and energy efficiency while reducing DRAM traffic by as much as 70%.
  • Arm positions CPUs for low-latency orchestration and lightweight models, GPUs for graphics and general AI compute, and partner-designed NPUs for sustained, compute-intensive workloads.
  • KleidiAI kernels, SDKs, open neural-graphics models, and engine integrations abstract hardware details so developers can adopt the new capabilities without rewriting applications.

燧原科技发行结果出炉!募资61.19亿元,国产AI芯片龙头即将登陆科创板

Rank 57 · Content 60 · Popularity N/A

TL;DR - Chinese cloud AI chipmaker Enflame Technology raised RMB 6.119 billion in its Shanghai STAR Market offering, reflecting strong investor demand for domestic AI compute infrastructure. The company is scaling a full-stack portfolio spanning AI chips, accelerators, clusters, and programming software.

  • Enflame has developed four chip architectures and five cloud AI chips using its independently controlled DSA architecture, GCU-CARE compute units, and GCU-LARE interconnect technology.
  • Its TopsRider platform provides an integrated software stack covering drivers, compilers, operator libraries, and development tools.
  • The fourth-generation product has passed hardware and model compatibility checks at several prospective customers, with small-scale deliveries targeted for 2026 and volume shipments for 2027.
  • First-half 2026 revenue reached RMB 1.12 billion, up 279.08% year over year; the company expects profitability in 2026 or 2027.

AI Economics 1

The Work Now Within Reach

Rank 50 · Content 50 · Popularity N/A

TL;DR - OpenAI argues that increasingly capable and affordable AI can expand what workers and businesses accomplish while making economic growth less costly. The provided excerpt is high-level and offers no specific technical results or product details.

  • Frames AI capability gains and falling costs as complementary drivers of broader adoption.
  • Suggests AI could increase the scope of economically feasible work.
  • Emphasizes potential productivity and growth benefits rather than a specific model, benchmark, or release.

AI Talent Market 1

Representative image for AI人才3次大迁徙:百度先行、六小虎分化、腾讯「腾笼换鸟」

AI人才3次大迁徙:百度先行、六小虎分化、腾讯「腾笼换鸟」

Rank 61 · Content 65 · Popularity N/A

TL;DR - China’s AI sector has undergone three talent migrations—from Baidu to model startups, then toward ByteDance and Tencent, and now toward post-training and agent teams. The shifts reflect competition moving from foundation-model pretraining to inference, applications, infrastructure, and high-quality data.

  • Demand for pretraining specialists has reportedly fallen 30%–40% from its peak, while hiring for reasoning, post-training, and coding-agent expertise is intensifying.
  • Strategic retrenchment at startups such as Baichuan and 01.AI released foundation-model talent, with ByteDance and especially Tencent emerging as major destinations.
  • AI infrastructure specialists in GPU scheduling, FPGA compilation, and inference optimization are highly sought because they directly determine compute utilization.
  • High-quality data is becoming a central competitive advantage as compute availability stabilizes and model architectures reach a perceived near-term plateau.

AI Theorem Proving 1

Anthropic AI ‘formalizes’ proof of Fermat’s last theorem — a milestone for mathematics

Rank 84 · Content 100 · Popularity 47

TL;DR - Anthropic’s Claude reportedly formalized a proof of Fermat’s last theorem into 13 million lines that were computer-checked. Completing the task in 11 days marks a notable milestone for AI-assisted formal mathematics.

  • The result concerns formalizing the famed theorem, rather than discovering its original proof.
  • Computer checking provides machine verification of the generated formal proof.
  • The proof’s 13-million-line scale highlights the substantial complexity of translating mathematics into a formal system.
  • The limited item content does not specify the Claude model, proof assistant, or degree of human involvement.

Biomedical Data Security 1

A data leak shut a top research biobank: lessons from the recovery

Rank 59 · Content 65 · Popularity 47

TL;DR - The UK Biobank is introducing new safeguards after a data leak forced the research resource to shut down. The incident highlights the challenge of protecting sensitive biomedical data without unduly restricting legitimate research access.

  • The security incident disrupted access to a major biomedical research repository.
  • Recovery includes new safety measures, although the provided excerpt does not specify their technical details.
  • The central trade-off is stronger data protection versus continued researcher accessibility.

Clinical Trials 1

China’s fast-track clinical trials are in the spotlight after child deaths

Rank 59 · Content 65 · Popularity 47

TL;DR - Nature reports on scrutiny of China’s fast-track clinical-trial system following child deaths. A new government policy aims to preserve faster medical innovation while strengthening safety protections.

  • The deaths have intensified attention on the risks of accelerated clinical trials.
  • China’s policy response seeks to balance trial speed and innovation against patient safety.
  • The limited excerpt does not specify the policy’s measures, the therapies involved, or investigation findings.

Edge AI Hardware 1

Representative image for 在IFA重新认识安克:从技术底座到场景贯通

在IFA重新认识安克:从技术底座到场景贯通

Rank 57 · Content 60 · Popularity N/A

TL;DR - Anker unified five product brands under the Anker name while unveiling an edge-AI strategy spanning personal audio and smart homes. Its Thus audio chip and MindBase home hub aim to deliver private, locally processed intelligence and coordinated device experiences without cloud subscriptions.

  • The Thus A1 compute-in-memory audio chip delivers a claimed 5 GFLOPS—about 150× traditional Bluetooth-chip compute—enabling larger noise-cancellation models on low-power earbuds.
  • Thus-powered AeroClip 2 Pro earbuds perform recording transcription, summarization, and Q&A entirely on-device; the chip also supports localized sound processing in an OTC hearing aid.
  • Sleep A40 Pro uses a closed feedback loop that senses heart rate, HRV, and sleep stages, adapts audio interventions, and measures whether relaxation improves.
  • MindBase combines a 6-TOPS NPU with up to 48 TB of local NAS storage to run home AI agents, coordinate security, cleaning, and energy devices, and keep sensitive household data off the cloud.

Embodied AI 1

Representative image for “ONE FOR ALL”背后,帕西尼正在构建怎样的物理AI闭环?

“ONE FOR ALL”背后,帕西尼正在构建怎样的物理AI闭环?

Rank 61 · Content 65 · Popularity N/A

TL;DR - PaXini AI presented its “PIE” strategy for creating a closed-loop embodied-AI stack spanning tactile perception, learning data, and robotic execution. The company aims to make physical AI commercially viable by reducing sensing costs, automating multimodal data processing, and validating systems on real production lines.

  • The GEN4 FUSE chip provides mass-produced native 6D tactile sensing across robot fingertips, palms, joints, skin, and feet.
  • PXCap Pro captures synchronized touch, pose, and visual data, while OmniSharing DB automates multimodal calibration, cleaning, and labeling.
  • Dexterous hands and TORA humanoid robots turn learned capabilities into tasks including industrial sorting, material transport, and service interactions.
  • A partnership with BYD will collect factory-floor interaction data and jointly develop tactile robotic systems for specific manufacturing processes.

Embodied Robotics 1

Representative image for 3秒变身!会合体的机器人,卖到全球50国

3秒变身!会合体的机器人,卖到全球50国

Rank 54 · Content 55 · Popularity N/A

TL;DR - Chinese robotics company Direct Drive Technology is commercializing direct-drive wheeled-legged robots, including the modular D1, which can separate or combine into different configurations in three seconds. The approach emphasizes adaptable, reliable robot bodies as a prerequisite for deploying embodied-AI models in real environments.

  • D1 supports interchangeable two- and four-wheeled-legged forms that share one algorithm stack, reducing development and testing costs.
  • The XingTian model can carry or pull more than 80 kg, while TITA offers eight degrees of freedom, a 10 kg dynamic payload, and operation from −10°C to 45°C.
  • Removing gear reducers reportedly makes the company’s integrated direct-drive joints smaller, quieter, and capable of 50,000–100,000 operating hours.
  • The article says its robots have shipped to more than 50 countries and regions, while its direct-drive modules held 61.1% of China’s consumer-robot market in 2025.
Top highlights — Opinions

Medical/Healthcare AI 1

Put patients at the centre of medical AI governance

Rank 63 · Content 70 · Popularity 47

TL;DR - This Nature commentary argues that patients should be central to the governance of medical AI. The provided content contains only the title and publication metadata, so specific recommendations or evidence cannot be determined.

  • Focuses on patient-centred oversight of AI used in healthcare.
  • Frames medical AI governance as an issue requiring direct attention to patients’ interests and perspectives.
  • No technical framework, empirical results, or concrete policy proposals are included in the supplied excerpt.

Clinical Trial Ethics 1

Limit bets on clinical-trial outcomes being placed on prediction markets

Rank 49 · Content 50 · Popularity 47

TL;DR - This Nature commentary calls for limits on prediction-market bets tied to clinical-trial outcomes. With only the title provided, its specific rationale and proposed safeguards cannot be determined.

  • The focus is wagering on whether clinical trials will succeed or fail.
  • The article advocates restrictions rather than describing experimental research results.
  • The issue matters because such markets could create financial incentives around sensitive medical outcomes.
  • No evidence, policy mechanism, or recommended limit is included in the supplied content.